Quick brief
Choose independent agents where the work benefits from separate decisions, evidence gathering or ownership, and make their handoffs explicit. Preserve a controlled baseline and expand only when the accepted outcome justifies the added coordination, authority and operating cost.
Listen to the AI-generated overview · about 2 minutes
Read the audio transcript
Timestamps are approximate.
0:00
This is an AI-generated overview of the revised article on compound AI and multi-agent systems. The contract review is fictional.
0:09
A team proposes three specialist agents: one for commercial terms, one for security, and one to prepare the recommendation. Giving them separate names does not establish that they need independent control. Three model calls inside a controlled workflow might be enough.
0:25
A compound system combines components such as models, retrieval, and tools. A multi-agent design adds agents that can make meaningful choices within their responsibilities. These ideas overlap. They are not stages on a universal ladder from prototype to production.
0:41
The commercial and security reviews can start from the same contract revision. Then the commercial reviewer proposes a different data-processing term. The earlier security conclusion may need another look. Parallel first drafts do not make the final decisions independent.
0:56
The handoff should preserve that changed term, its source revision, and the unresolved question. A coordinator must not turn missing agreement into a confident approval merely to finish its summary. Preparing a recommendation also does not authorize signing the contract or contacting the supplier.
1:12
More agents can bring broader evidence coverage, but also more repeated context, coordination, retries, and review. Compare the same work under the same acceptance rule. Faster worker responses are not necessarily a faster accepted outcome, and a lower token count is not proof of quality.
1:29
Start with a controlled baseline. Add another agent when it solves a demonstrated problem and its contribution justifies the operating work. The useful architecture is the one the team can explain, test, and recover when a handoff fails.
Full analysis
Originally published November 3, 2025. Revised October 18, 2026.
A team proposes three specialist agents for a contract review: one for commercial terms, one for security, and one to prepare a recommendation. Before choosing a framework, ask what each agent can decide independently and what information has to move between them. Three prompts inside one controlled workflow may be entirely adequate.
The distinction matters because extra agents introduce more than extra model calls. Someone has to divide the work, preserve the evidence, resolve disagreements, control access, and decide when the result is complete. Those responsibilities should be visible in the architecture before they become an operational surprise.
Compound AI and multi-agent systems describe overlapping ideas. They are useful ways to reason about a design, but neither label establishes the system’s quality, autonomy, cost, or business value. The right choice comes from the work and the failures the organization must be able to handle.

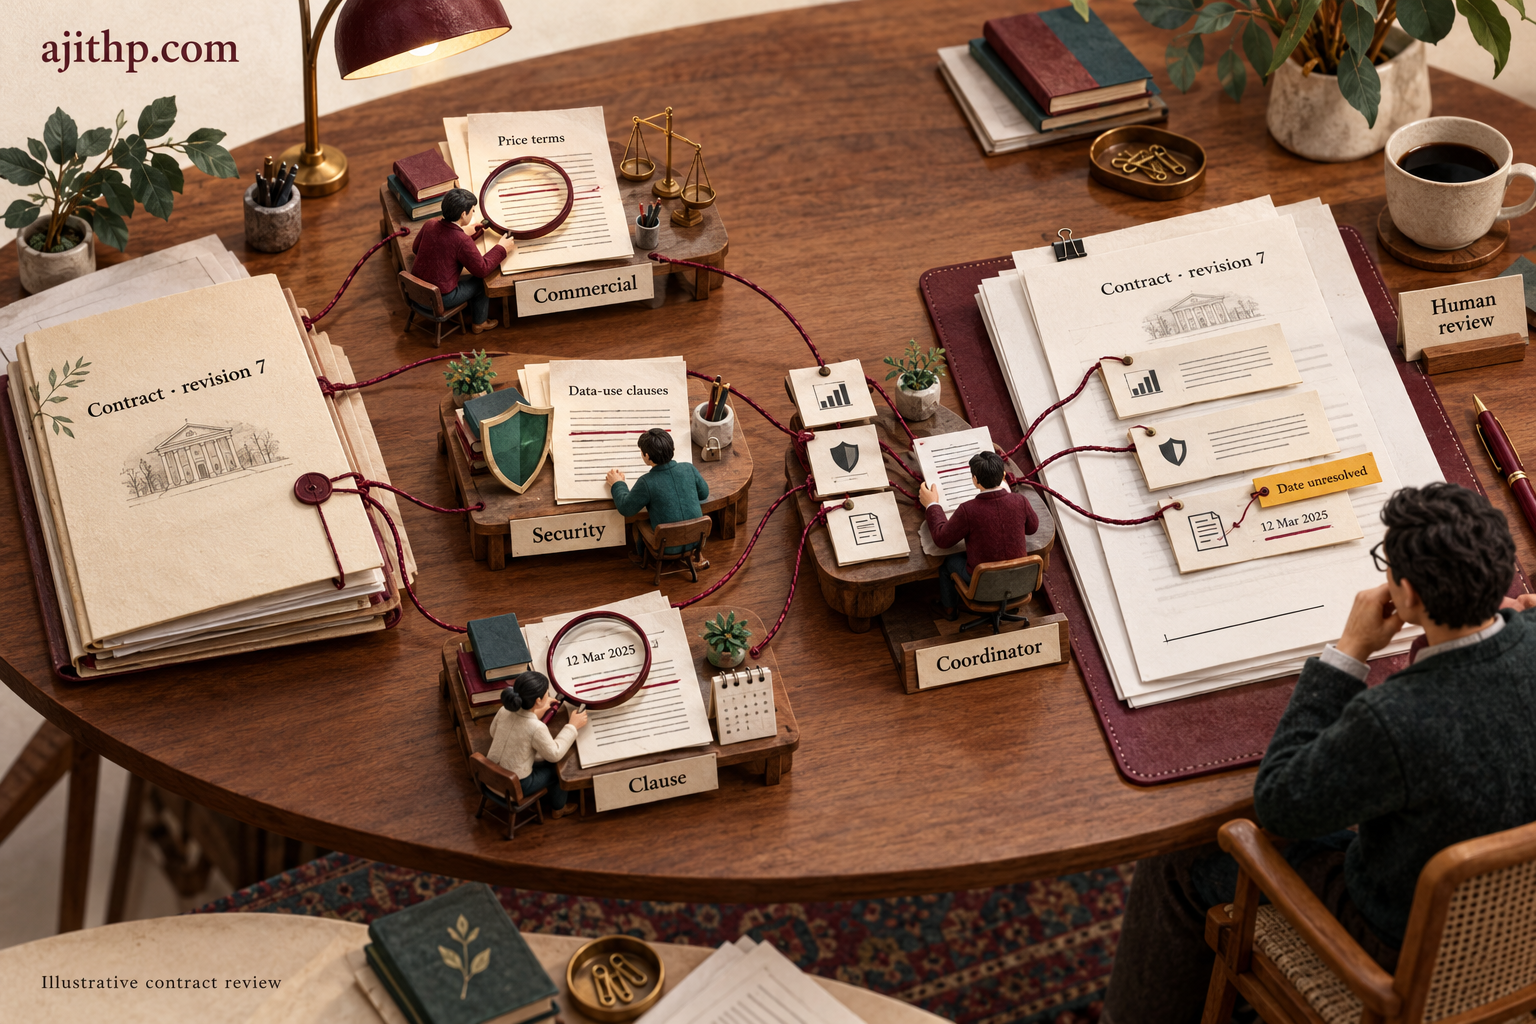
Download the printable framework map.
Separate system composition from independent agency
The Berkeley AI Research explanation of compound AI systems, published in February 2024, describes systems assembled from interacting components such as model calls, retrieval, and external tools. A retrieval-augmented assistant can be a compound system without containing a team of autonomous agents.
For an architecture review, I use multi-agent to mean that more than one agent can make meaningful runtime choices within an assigned responsibility. A coordinator that delegates research to workers with their own tool-use loops fits that description. Calling three fixed prompts in sequence does not require the same coordination model, even if the application gives each prompt a job title.
These are working distinctions, not a universal maturity ranking. A single-agent application can use a sophisticated compound architecture. A multi-agent design can sit inside a tightly controlled workflow. Count the independent decisions, state transitions, and permissions rather than treating the number of named roles as a measure of capability.
Anthropic’s workflow and agent patterns provide a useful complementary distinction: predefined application paths versus model-directed choices about how to proceed. Use those descriptions to inspect the actual control flow, not to conclude that more autonomy must be better.
The distinction between an agent and an agentic system also deserves care. An individual component might select a tool, inspect the result and decide whether to continue. The surrounding system still decides which tools exist, which identity it uses, how long it may continue and which outcomes require approval. A reasoning loop is one part of the architecture; it does not own every responsibility around it.
I find a capability map more useful than a ladder from chatbot to autonomous enterprise. A service can have persistent state and strong recovery while using a fixed workflow. Another can delegate dynamically yet have weak evidence tracking. Record those capabilities separately. Otherwise, a team can appear to advance by adding autonomy while making the service harder to operate.
Choose among three coordination patterns
A controlled workflow is a sensible starting point when the steps and completion conditions are well understood. In the contract example, the application can retrieve approved documents, compare specified clauses, validate required fields, and route exceptions to a person. A model may perform one or more steps while application code owns the sequence.
A coordinator with delegated workers becomes useful when the task contains bounded branches that can proceed independently. A worker might investigate a particular clause or gather evidence for a known question, then return a structured result to a coordinator responsible for synthesis. The design needs a response to a missing, late, conflicting, or unsupported worker result.
More distributed coordination can be appropriate when agents represent separate services or operating responsibilities. It also creates harder questions about shared state, conflicting actions, delegation, and recovery. A conversational exchange between agents does not itself resolve those problems.
The words planner and orchestrator are often used differently across frameworks. A planner may propose a set of tasks while an orchestrator manages their execution; one component can perform both roles. Inspect which component can change the plan, authorize a tool, retry a step, and declare completion. A product label cannot answer those questions.
| Pattern | Who controls the next step? | Where it helps | Failure to design for |
|---|---|---|---|
| Controlled workflow | Application rules, with bounded model decisions inside steps | Repeatable review, extraction and approval processes | An unexpected case falls outside the defined path |
| Coordinator with workers | A coordinator delegates bounded work and combines results | Independent research branches or specialist assessments | A missing or conflicting branch is hidden during synthesis |
| Coordination across agent services | Several services manage their responsibilities through an agreed exchange | Work crossing service or organizational ownership boundaries | Conflicting state, duplicated action or an unresolved handoff |
These are alternatives within a compound system, and they can coexist. A controlled intake workflow might invoke a delegated research team, then return its recommendation to a fixed approval path. That design has several agents without making the whole business process open-ended.
Give each architectural component a defined responsibility
The original attraction of compound AI remains sound: a model does not have to perform every function itself. Retrieval can supply evidence, ordinary software can calculate values, and a transaction service can enforce the rules for a write. The design becomes easier to reason about when each component has an explicit contract.
| Component | Responsibility | State or evidence to retain | Boundary to test |
|---|---|---|---|
| Planning and execution control | Decompose the task, schedule work and enforce stopping conditions | Plan revision, dependencies, budgets and status | A worker or tool fails after a dependent step has started |
| Agent or model step | Make bounded choices or produce a specified result | Input references, model/configuration version and material output | An unsupported answer looks complete |
| Memory and case state | Preserve relevant context across steps or runs | Record identity, revision, provenance and permitted readers | A later step acts on a stale or unauthorized record |
| Retrieval and knowledge services | Find evidence appropriate to the question | Source references, access scope and index version | A retrieved passage is outdated, incomplete or misleading |
| Tools and action services | Read or change an external system through a defined interface | Request identity, validated arguments and destination result | A retry duplicates an action or changes its target |
| Evaluation and operating controls | Assess outcomes and explain failures | Acceptance results, timing, cost and intervention history | A plausible transcript masks an incorrect business state |
This separation is useful even when the implementation runs in one process. It prevents a common design mistake: using a model response as the only place where planning, authorization, state updates and success are represented. A textual claim that an invoice was corrected cannot substitute for the invoice system’s result.
A plan should expose dependencies rather than merely list tasks. “Review the security terms” and “review the pricing terms” may be independent at first. “Approve the revised agreement” depends on both, on the final document revision and on the approver’s authority. The execution layer should be able to represent that dependency even if a model suggested the plan.
Keep the distinction between proposing and executing visible. A planner can suggest a new research branch within an agreed budget. It should not silently convert a research assignment into permission to contact a supplier. When a proposed step crosses the approved scope, the system needs a new decision about that step.
Check whether the work is genuinely parallel
Suppose three independent research branches take 30, 45, and 60 seconds, followed by 30 seconds of synthesis. Under a purely sequential design, that is 165 seconds. If the branches run concurrently, with five seconds of additional coordination and the same synthesis step, the illustrative elapsed time is 95 seconds: five plus the longest branch, 60, plus 30.
Those are assumed durations, not benchmark results. They show where the possible time reduction comes from. They also reveal what would invalidate the comparison: a shared rate limit, a branch that needs another branch’s output, unequal source coverage, retries, or a slower synthesis step.
For the contract review, a security assessment and a commercial assessment may start from the same document package. If the commercial reviewer proposes a different data-processing term, the security conclusion may need to be revisited. Running the first drafts in parallel does not make the final decisions independent.
Measure the complete accepted outcome under realistic load. Parallel work can reduce wall-clock time while increasing simultaneous resource demand and coordination cost. A system that returns quickly by abandoning difficult branches is performing a different task from one that resolves them.
For these assumed durations, the speedup is 165 / 95, approximately 1.74 times, and the elapsed-time reduction is (165 − 95) / 165, approximately 42.4%. The calculation describes this example only. It does not establish a general 40–60% benefit from using a planner, three agents or any particular framework.
The useful scheduling question is which path determines completion. If the 60-second branch has to wait for the 45-second branch, the concurrent estimate changes. If the system permits only two simultaneous calls, scheduling changes again. Include queue time, rate limits and the reconciliation step in a real comparison; counting just the fastest worker response hides the service the user is waiting for.
Design memory around evidence and ownership
“Give the agents shared memory” leaves several different requirements unresolved. Working context helps a step continue its current task. Durable case state records what has happened. A searchable history may help a later task find relevant information. A reusable procedure describes how to perform a class of work. Each has a different lifecycle and a different reason to be trusted.
For the contract review, working context might contain the clause under examination and the question assigned to a worker. The durable case record should identify the contract revision, completed checks, unresolved findings and approvals. A reusable review procedure could specify the required clauses and escalation rules. Storing all three in one conversation history makes it difficult to distinguish an instruction, an observation and an approved rule.
Long-term storage is not automatic learning. A successful execution trace may contain accidental choices, sensitive data or assumptions that no longer apply. Before turning it into a reusable procedure, decide what was actually successful, remove case-specific material, review the procedure and version it. A previous answer is useful evidence to inspect, not a standing instruction to repeat.

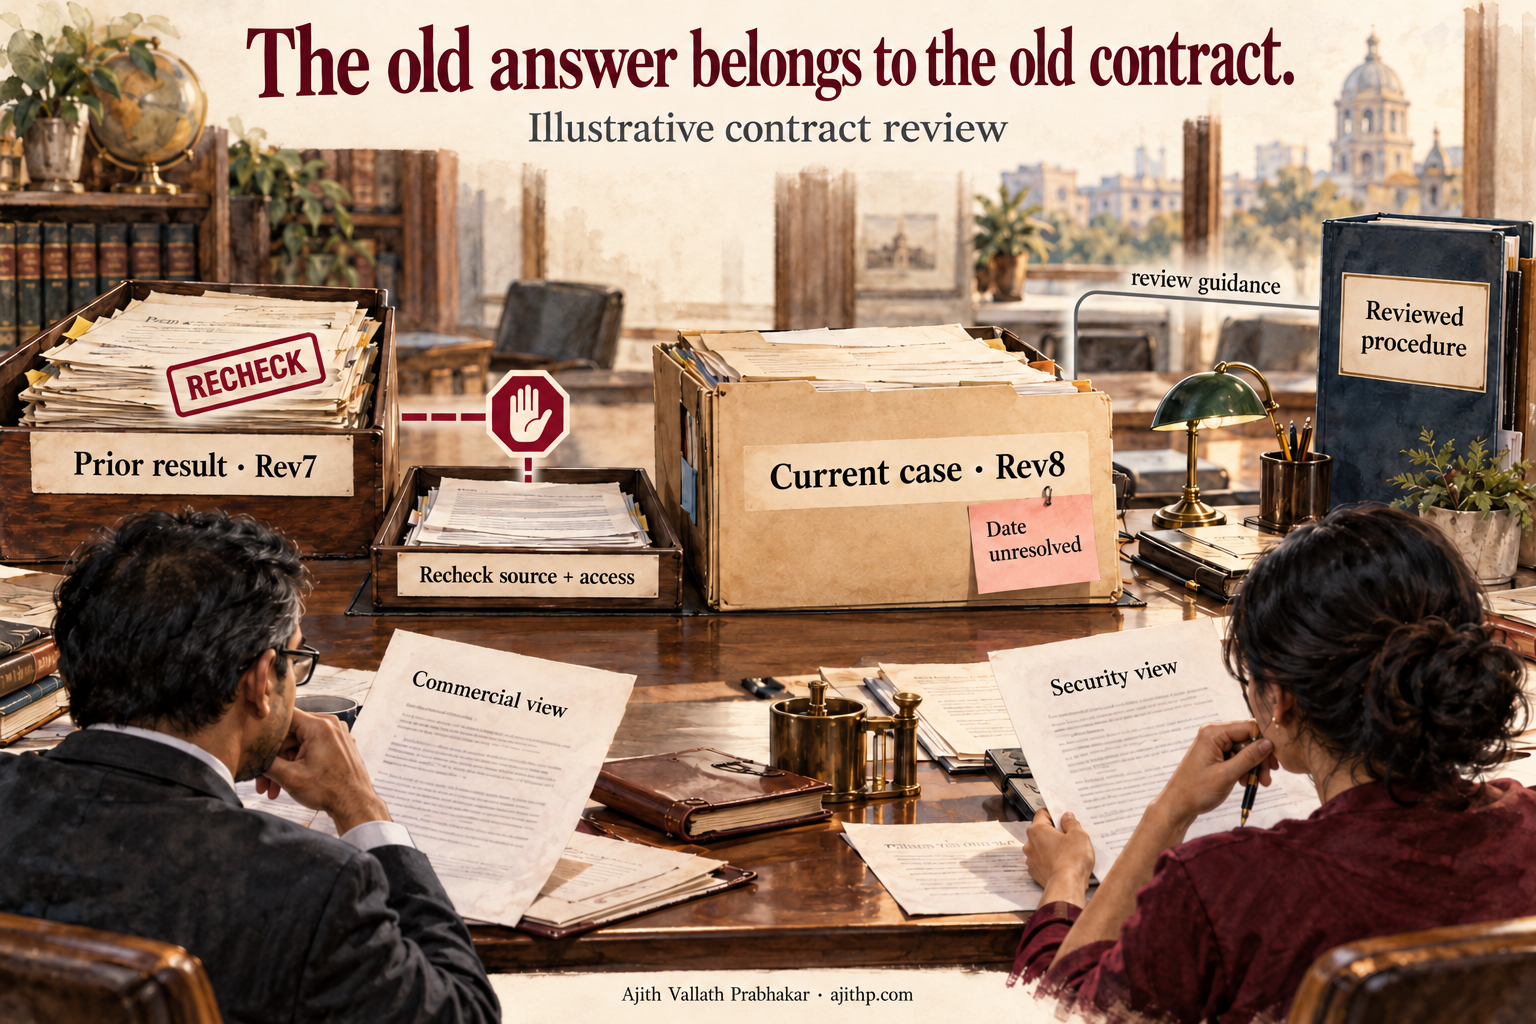
Different roles may need different views of the same case. A commercial reviewer may need price schedules while a security reviewer needs the data-processing terms. Keep the common case identity and revision visible without copying every document into every worker’s context. That reduces unnecessary exposure and makes it easier to see why two workers reached different conclusions.
Concurrent updates need a policy. One option is to let workers append findings while a coordinator alone changes the case’s decision state. Another is to require a revision check when committing an update. Neither prevents every conflict; both make the conflict observable. Define what happens when a worker finishes against revision 7 after revision 8 has become authoritative.
Memory also creates an operating obligation. Decide which records expire, which can be corrected, who can retrieve them and how a deletion affects derived summaries or indexes. A short context window does not make retained case data disappear, and a shared store does not make every reader entitled to its contents.
Use retrieval for the question the system has to answer
Retrieval-augmented generation is a design family, not a synonym for one vector search. A service can use keyword search, metadata filters, structured queries, vector retrieval or combinations of these. The relevant question is whether the retrieval method can supply the evidence needed for this task within its access and freshness constraints.
For a specific contract clause, targeted retrieval may be enough. A question about recurring dependencies across a large document collection may need a broader representation. Microsoft’s GraphRAG documentation describes an approach that builds a graph-based index and summaries from source material. Its global search uses community reports, produces intermediate responses and combines them into an answer. That is a concrete mechanism for collection-level questions, rather than evidence that every enterprise needs a knowledge graph.
The graph still reflects extraction choices and source quality. A relation inferred from an old document is not necessarily current business truth. Community summaries may omit a qualification that matters for a particular decision. Keep a route back to the underlying sources and test questions that require exceptions, dates and contradictory evidence.
Indexing has costs and responsibilities of its own. Measure initial construction, refresh work, query latency and the effort needed to investigate an incorrect answer. Decide how an updated or withdrawn document changes entities, summaries and cached responses. An index can be technically available while being too stale for the action under consideration.
Access control must extend to derived material. A summary assembled from several restricted records can reveal information even if the original documents remain protected. The retrieval service should enforce the reader’s permitted scope, and the evaluation should include attempts to obtain restricted information through summaries or indirect questions.
GraphRAG is MIT-licensed; describing it as a proprietary alternative to RAG would be inaccurate. The enterprise choice is about the workload, implementation and operating obligations, not a blanket division between open retrieval and proprietary graphs.
Define what crosses each agent boundary
A useful delegation names the question, permitted sources and tools, expected evidence, completion condition, time or cost budget, and escalation rule. It should also identify the case and versions of the material being reviewed. “Investigate the supplier” gives a worker little basis for deciding when it has done enough.
In the illustrative contract workflow, the commercial worker might return the proposed price change, relevant clause references, unresolved conflicts, and a recommendation within its scope. The coordinator needs those material findings, rather than a long conversation transcript with no reliable connection to the source versions.
Do not assume that shared memory solves coordination. Two workers can read the same record and still use different versions or make incompatible changes. Establish ownership of mutable state and a way to detect conflicting updates. Where possible, give workers read-only access to evidence and keep consequential writes behind a separate action service.
Preserve disagreements that matter. A synthesizer should not turn “the effective date is unresolved” into a confident single date merely because its output format expects one. An unresolved finding can be the correct result for the next human decision.
A result contract makes that behavior easier to test. This illustrative message records a partial finding without authorizing a transaction:
{
  "case_id": "contract-example-042",
  "source_revision": "7",
  "worker_role": "commercial_review",
  "status": "needs_review",
  "findings": [
    {
      "question": "Which effective date governs the renewal?",
      "evidence_refs": ["contract-r7:clause-3", "appendix-r7:section-2"],
      "conclusion": null,
      "unresolved": "The two source provisions specify different dates."
    }
  ],
  "requested_next_step": "Resolve the conflicting provisions before approval."
}
This is an example interface, not an implemented schema or an executed integration. A production contract would also need validation rules, identity, error handling and a way to distinguish an authentic worker response from untrusted content. The important property here is that an unresolved question can survive the handoff intact.
Choose the topology for its failure behavior
A hierarchy can make ownership clear: a coordinator assigns work and is responsible for a result. It can also become a bottleneck or a single point of failure. Recovery requires durable state and a way to resume without repeating an already completed action.
A linear pipeline makes dependencies visible and often simplifies testing. It can include parallel branches; linear ownership does not require every operation to run sequentially. Its weakness is usually the cost of handling cases that do not fit the expected path.
Peer coordination can suit services with separate owners, but it introduces agreement and conflict-resolution work. Removing a central coordinator does not automatically produce resilience. A team still needs to decide who may write shared state, how duplicate messages are handled and when a disagreement becomes an exception for a person.
| Topology | Useful property | Operating question before adoption |
|---|---|---|
| Hierarchical delegation | One component owns decomposition and synthesis | Can ownership resume safely after that component fails? |
| Pipeline or explicit task graph | Dependencies and completion gates are visible | How are unexpected branches and invalidated results handled? |
| Peer or federated services | Responsibilities can remain with separate service owners | What resolves conflicting state, authority or completion claims? |
Use these as design choices, not framework labels. The same framework may support several topologies, and a single service can use different ones at different boundaries.
Keep permission separate from delegation
Assigning an agent a task does not automatically authorize every action that could help it complete that task. A worker allowed to inspect a contract may not be allowed to send it to a new destination, negotiate terms, or update the purchasing system. Permissions should follow the initiating identity, workflow scope, and destination rules.
Enforce consequential restrictions outside the model’s own reasoning. Validate the proposed target and material values, check the relevant authorization, and use the destination’s supported safeguards against duplicate or conflicting operations. If the evidence or approval changes, the action path needs a defined recheck or escalation.
Treat retrieved documents and worker messages according to their trust level. A document can contain useful contract evidence alongside an instruction to disclose unrelated files. Passing that text through another agent does not make it authorized. Test the attempted tool action as well as the explanation shown to a reviewer.
The CTRS framework connects these concerns to an accountable decision. Its value is the control map the team can inspect: who owns the action, where the rule is enforced, what evidence is retained, and what happens when the check fails.
Use protocols for their actual purpose
Model Context Protocol provides a host/client/server interface for capabilities such as tools and resources. Agent2Agent describes exchanges between agent services using concepts including Agent Cards, messages, tasks, and artifacts. They address different integration boundaries and can be used together.
Neither protocol determines the organization’s decision rights. A discoverable capability still needs review and appropriate access. A successful task exchange does not prove that a downstream business action was approved or completed.
An enterprise may not need both protocols in its first workflow. A direct application call can be sufficient when the integration is small and controlled. Introduce a protocol because it solves an interoperability or operating problem, and test the actual versions and capabilities implemented on each side.
Connect the system to enterprise work
Consider an illustrative manufacturer handling a delayed shipment. An operations service identifies the affected orders in ERP. A customer-service step retrieves the relevant account commitments from CRM. An analysis step looks at shipment history in the data platform. The system prepares a proposed response with evidence and routes it to the responsible person before sending a message or changing an order.
That example has useful parallel work, but it also has dependencies. Historical analysis and account review can begin from the same order snapshot. A compensation proposal depends on the customer terms and the organization’s policy. Sending it depends on approval and a final check that the order has not already been resolved.
Prefer supported, narrowly scoped interfaces for those operations. An API gateway can help centralize authentication, limits and routing, but it is not mandatory for every integration. A curated read view or a service-specific interface may be more appropriate. Direct database access needs its own justification and restrictions; the label “agent” does not make arbitrary queries or writes acceptable.
A tool’s interface should make the business operation unambiguous. “Update customer” is too broad if the task only needs to add a reviewed delivery note. Specify the target identifier, allowed fields, required revision, validation errors and response that establishes completion. Separate a proposed action from the service call that commits it.

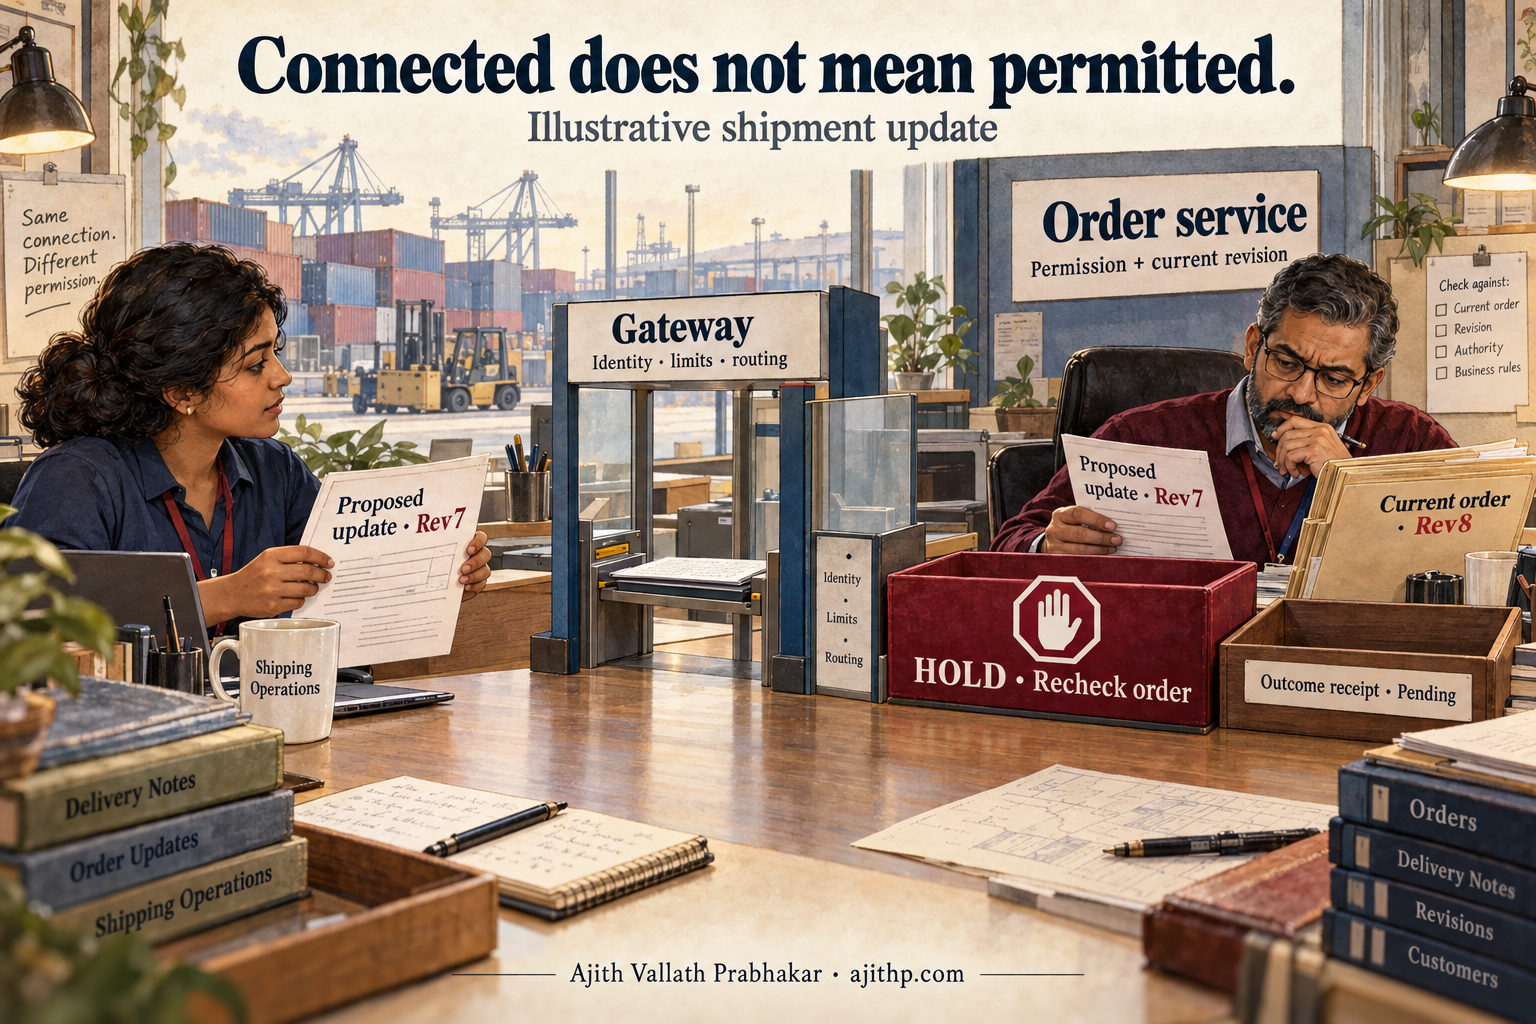
Recovery matters as much as the happy path. If a notification was sent but the case update failed, retrying the entire workflow could send it again. Record destination identifiers and use supported duplicate-prevention mechanisms. If the destination cannot offer an atomic outcome, define reconciliation and a human exception path rather than claiming the workflow is transactional.
Put simulation before action where it is useful
A digital twin can add a model of a physical or operating system to the decision loop. In the shipment example, a simulation might compare alternative allocation or routing plans before anyone changes the operating schedule. The useful sequence is to observe the current state, propose a change, simulate its consequences, examine the result and decide whether to act.
The decision depends on what the model represents. Record its assumptions, state timestamp, relevant constraints and known blind spots. A simulation of average transit time may say little about a particular hazardous load or a supplier’s contractual commitment. Calling a model a digital twin does not establish real-time synchronization or sufficient fidelity for the proposed action.
Keep simulated results separate from observed outcomes. A predicted improvement is a reason to examine an option, not a measured business benefit. Before execution, recheck the material state and authority at the real system. The plan may have been valid when simulated and invalid by the time a transaction is attempted.
Adapt the architecture to the consequence of the decision
In financial services, a KYC review can combine document extraction, evidence retrieval, research and a critical check before a qualified reviewer decides what to do. The value of specialist steps is the ability to preserve missing documents, conflicting ownership information and unresolved risk. A confident summary that conceals those exceptions can make the workflow worse. This is an illustrative design, not a claim of measured productivity or regulatory acceptance.
In healthcare, distinguish administrative coordination from clinical decision support. Scheduling and assembling a record already require identity, current information and careful access. A clinical recommendation adds questions about intended use, evidence, validation and the responsible clinician. A team of model roles does not establish diagnostic accuracy or an improvement in patient outcomes. Those outcomes require appropriate study of the actual system and setting.
For a public-benefit service, an assistant could check whether the requested documents are present, gather relevant policy passages and prepare a case summary. Document completeness is different from eligibility, and a recommendation is different from a lawful decision. Preserve the applicant’s opportunity to correct information and the agency’s review and appeal process. Parallelizing the checks should not make their reasons harder to explain.
The common architecture is bounded evidence gathering followed by an accountable decision. The boundaries differ by setting: who can see the source, who may resolve a conflict, what must be recorded and which actions can be delegated. Those differences should shape the workflow before a common agent platform is selected.
Measure the coordination cost instead of importing a multiplier
In its June 2025 account of a multi-agent research system, Anthropic reported roughly four times the tokens for agents and fifteen times for multi-agent systems, both compared with chat interactions in its own data. The fifteen-times figure is not a universal comparison with a single-agent system, and it is not a forecast for an enterprise workflow.
Use it as a reason to measure your design. Count planning, worker calls, repeated context, tool results, retries, synthesis, and verification within the same cost boundary. Include the human work required to turn the result into an accepted outcome. A low token bill can be a poor trade if the reviewer must reconstruct the evidence manually.
Compare architectures against the same task population and acceptance rule. A single-agent baseline that searches one document is not a fair comparator for a team that examines twenty. Conversely, a team that produces more words or cites more pages has not necessarily produced a more useful decision.
The token-economics workbook makes that cost boundary explicit. Record completion latency and resource consumption separately: the architecture that finishes first need not be the one that consumes least.
Build a cost model that includes the work between agents
Here is a synthetic token ledger for one completed attempt. These numbers are assumptions for explaining the accounting, not observations from a deployed system or a forecast for a framework.
| Call or group of calls | Input tokens | Output tokens | Total tokens |
|---|---|---|---|
| Planning | 600 | 200 | 800 |
| Three workers, 1,200 input and 600 output each | 3,600 | 1,800 | 5,400 |
| Synthesis | 1,000 | 400 | 1,400 |
| Verification | 500 | 200 | 700 |
| Total | 5,700 | 2,600 | 8,300 |
A hypothetical baseline using 3,000 tokens would make the token-count ratio 8,300 / 3,000, approximately 2.77. That is not yet a price or a value comparison. Models can have different input and output rates; caching, tool fees and infrastructure can change the bill. The comparison also needs evidence that the two designs perform the same task to the same acceptance standard.
Track retries and unsuccessful attempts in the total. If a worker must restart because a source revision changed, its first attempt still consumed resources. If a person spends twenty minutes reconciling the answer, that work belongs in the operating view even when the model bill is small. Cost per accepted outcome uses all in-scope cost in the numerator and accepted outcomes in the denominator.
Optimization then becomes a design decision with a quality test. A cheaper model may be adequate for a bounded extraction step. A compact evidence package may reduce repeated context. Caching may help when the material and access scope genuinely match. Each change can also remove information or reuse something stale, so evaluate the result rather than treating a lower token count as success by itself.
Allocate budgets at the workflow level as well as the worker level. Three agents that each obey a local limit can still exceed the total through retries, recursive delegation or an expensive synthesis step. Define who can authorize extra work and what useful partial result is returned when the budget is exhausted.
Measure outcomes and diagnose coordination separately
Task success rate is a useful starting measure when success is defined before the run:
Task success rate = accepted task outcomes / attempted tasks.
Specify the task population, acceptance rule and observation period. Report which outcomes required a person, which were partial and which were abandoned. If a person corrected an answer before acceptance, that may be a successful assisted workflow; it is not an autonomous success. Do not silently remove difficult or failed tasks from the denominator.
A universal target such as 85% would hide more than it explains. A draft-research assistant and a system making consequential changes have different failure costs. Inspect error severity, distribution across task types, review burden and the consequences of accepting the wrong result. A good average can conceal a small group of cases the service should refuse or escalate.
Research metrics can help diagnose behavior, but their definitions matter. The GEMMAS paper, first posted in July 2025, defines Information Diversity Score using a weighted combination of syntactic and semantic message similarity over its cooperation graph. Its structure is:
IDS = sum of [interaction weight × (1 − combined similarity)] / sum of interaction weights.
It is not simply one minus the cosine similarity of any two messages. GEMMAS also defines Unnecessary Path Ratio as 1 − necessary paths / all paths, with necessity assessed using its contribution procedure and threshold. Its algorithm compares node answers with a correct answer and marks a path necessary when its fraction correct is at least 0.5. It is not a count of reasoning steps compared with an assumed shortest answer. The paper’s algorithms matter when reproducing either measure. The study covers mathematical reasoning with small language models, rather than validated enterprise operating thresholds.
For a separate arithmetic illustration, suppose two interactions have weights 2 and 1, and combined similarities 0.8 and 0.2. The weighted diversity calculation is [2 × (1 − 0.8) + 1 × (1 − 0.2)] / 3 = 0.4. With no weighted interactions, that denominator would be zero, and the implementation would need an explicit convention. This example checks the calculation; it does not validate the underlying similarity measure.
Diversity is not correctness. Two workers can disagree because one misunderstood the question, and identical messages may correctly report the same evidence. Nor does a low unnecessary-path score establish that an answer is safe or useful. Treat these as diagnostic research measures, with task-specific validation, rather than production thresholds of IDS above 0.7 or UPR below 0.3.
AgentsNet provides another distinct research lens: coordination on graph problems through constrained message passing. Tasks such as graph coloring or consensus can help investigate the effects of network structure and coordination. They do not establish an enterprise service-level objective or prove that a particular business workflow tolerates failures.
For an operational evaluation, connect those diagnostics to observable work. Does specialist review find a material issue the baseline misses? Does synthesis preserve it? Does the correct destination change, under the correct authority? An LLM judge can help screen results against a rubric, but check its judgments on a reviewed sample and retain human or deterministic checks where the acceptance rule requires them.
Evaluate failures at the handoffs
Build a test set around representative work and deliberate boundary failures. For the contract review, include a missing appendix, conflicting effective dates, a worker that cannot finish, a duplicated task, a revoked permission, and a source change while synthesis is pending. Define the expected outcome before observing what the system does.
Check the coordinator’s behavior when a branch fails. Does it return a partial result with the missing evidence clearly identified, retry within a bound, ask for help, or incorrectly declare the work complete? Test whether a repeated task can cause a duplicate consequential action.
Retain enough event history to explain the task assignment, relevant source versions, material outputs, authorization, and destination result. Do not log every private payload indiscriminately. Access, retention, and redaction remain part of the design.
Repeat variable tasks and inspect the resulting state. A convincing transcript establishes only what the transcript contains. If the service promises an updated contract record, the acceptance test needs to inspect that record and its authorization evidence.
The evidence should connect the whole attempt. Record the task and case identifiers, source revision, delegation, material tool request, authorization outcome and destination receipt. Timing and usage records should cover waiting, retries and failed branches. Keep sensitive content to the minimum needed for the purpose, with access and retention rules that apply to the trace itself.
Runtime controls and pre-release evaluation serve different needs. Testing helps discover failure patterns before rollout. Runtime controls limit what a particular attempt can do and route exceptions when its conditions are not met. A separate “guardian agent” may contribute a review, but its model judgment is not a substitute for enforcement at the action boundary.
Select frameworks by the responsibilities they can support
The implementation ecosystem is useful when it reduces work the team would otherwise have to build and maintain. It is less useful as a ranking from experimental open source to enterprise-ready commercial software. Either can leave important responsibilities to the application.
The following descriptions are grounded in the linked project documentation checked for this revision. They describe capabilities, not a benchmark, security assessment or guarantee about a deployed configuration.
| Project | Documented emphasis | What the team still needs to decide |
|---|---|---|
| LangGraph | Stateful graph orchestration, persistence, durable execution and human intervention | Which state is checkpointed, how interrupted actions resume and which side effects must not repeat |
| AutoGen (archived) | AgentChat for conversational applications; Core for event-driven agent systems and workflows | Whether the application needs conversation abstractions or lower-level events, and how it owns shared state and recovery |
| CrewAI | Crews for collaborative agents and Flows for event-driven application control | Where delegated work ends and controlled state transitions, validation and approval begin |
| DSPy | Declarative Python programs and optimization of language-model components | The training/evaluation data, optimization objective and independent checks needed to prevent a benchmark gain from hiding a regression |
Microsoft’s AutoGen repository now identifies the project as archived and no longer maintained, without Microsoft bug fixes, security fixes or support. Its row is a historical architecture reference for existing implementations. Microsoft directs new projects and migration planning to Microsoft Agent Framework.
DSPy’s role in this table is important: program optimization and multi-agent coordination are different concerns. A program can use both, but choosing an optimizer does not decide how multiple services exchange authority or recover from failure. Similarly, a conversational API does not require a purely conversational production architecture.
Review the actual release and configuration you intend to use. Prototype state persistence, interrupt/resume, timeout behavior, tool restrictions, trace export and recovery with your task. Read the license and dependency obligations. A feature listed in documentation may need additional infrastructure or may not behave identically across language implementations and versions.
Managed model endpoints, self-hosted inference, orchestration libraries and observability tools are also different purchasing decisions. A capable planning model does not supply the organization’s authorization service. A packaged inference runtime does not make its host environment secure. A hosted agent service does not remove the need to inspect retention, data destinations, quotas and failure behavior.
For example, NVIDIA NeMo Agent Toolkit documents workflow integrations, evaluation and profiling, while Microsoft Semantic Kernel documents an SDK for integrating models and application functions. The Semantic Kernel repository now identifies Microsoft Agent Framework as its successor, which changes the evaluation path for new implementations. These resources illustrate different parts of the implementation work. Compare the capabilities your service needs rather than assuming a product family supplies an entire operating architecture.
Separate the application’s business contract from a vendor-specific implementation where practical. Keep case identifiers, result schemas, acceptance tests and consequential action interfaces understandable outside one framework. Protocol support can help interoperability, but portable messages alone will not move state, policies or operating procedures without work.
Expand only when another agent solves a demonstrated problem
Start with a controlled baseline and one workflow owner. Add a delegated worker where the evaluation shows a useful gain in evidence coverage, task quality, or completion time that justifies the added operating cost. Keep the alternative design available long enough to understand the tradeoff.
Framework selection follows those requirements. Review state persistence, interrupt/resume behavior, tool permissions, version compatibility, tracing, recovery, and the skills needed to operate the service. Open-source and managed products both need that inspection; neither category guarantees maturity or flexibility.
A multi-agent team can be a good answer to valuable, divisible work. It can also be unnecessary complexity around a task that ordinary software and a few model calls would handle well. The architecture earns its place when the complete workflow performs better under the conditions the organization actually has to manage.
Build organizational capability without making autonomy the destination
The architecture has to fit an operating model. A workflow owner defines the result and acceptance rule. Domain specialists decide what evidence and exceptions matter. Engineering owns execution and recovery. Security and risk functions help define authority and information boundaries. Operations needs a way to investigate failures and restore service. These responsibilities can sit in existing teams; they do not require an invented new department for every agent.
Start with a process whose boundaries are understood. Identify the existing handoffs, decisions, evidence and exception paths before automating them. A model can make an undocumented process run faster while leaving its ambiguity intact. The initial design work is often to decide what a completed case actually means.
At the portfolio level, connect that work to a business priority. Several pilots may depend on the same contract evidence, customer identity or action service; treating them as unrelated experiments can duplicate both integration work and risk. A shared program can establish those foundations while keeping each workflow’s acceptance rule and economics visible. A useful point solution still has a place when it solves a bounded problem without requiring a wider redesign.
At the process level, examine the handoffs around the model step. Faster extraction may accomplish little if a reviewer still has to locate the source and re-enter the result into another system. Redesigning that path can be more valuable than adding another reasoning role. This does not require assigning an arbitrary percentage of the process to agents; it requires identifying where a changed responsibility would improve the accepted outcome.
Delivery then needs continuity between the people who understand the work and those who will operate the service. Include domain, process, engineering, data and control responsibilities early enough to change the design. Carry the same discipline into the operating budget: maintenance, review, incident response and supplier changes continue after the demonstration. Fund and staff the service you intend to run, rather than assuming the pilot’s model bill describes its total cost.
Use a staged adoption plan with gates rather than a promise that every workflow will reach distributed autonomy:
| Stage | Work to establish | Evidence before expanding |
|---|---|---|
| Foundation | Bounded task, authoritative sources, baseline and acceptance criteria | Representative cases can be evaluated, including known exceptions |
| Controlled composition | Retrieval, tools, case state and explicit approval paths | End-to-end results and recovery work within the intended access scope |
| Selective delegation | Independent branches with defined result contracts and budgets | A comparison shows a useful gain without hiding failed branches or review effort |
| Wider coordination | Cross-service ownership, conflict handling and operating support | Handoffs, revocation, duplicate messages and reconciliation have been tested |
A team may reasonably stop at the second stage. Another may need peer services early because the work already crosses organizational boundaries. The gates describe responsibilities to establish, not a universal sequence or a maturity score.
For investment decisions, distinguish a promising demonstration from a supported service. A demonstration can show that the model can produce a result. An evaluation can show how a defined configuration behaves on selected tasks. A limited rollout can expose operating problems under controlled conditions. None establishes an enterprise-wide return without the relevant costs, outcomes and observation period.
Choose an expansion decision the evidence can answer. For the contract example, it could be whether a security worker adds material findings that justify its latency and review burden. That is more useful than requiring a fixed percentage of the enterprise to be “agentic” or reserving a universal fraction of the budget for multi-agent systems.
Keep the longer-term possibilities separate from the release decision
Models may improve at planning, tool use and handling longer context. Systems may use historical outcomes to propose better procedures or allocate work differently. Those possibilities do not remove the need for explicit state, authority and acceptance rules around a real service.
If a system proposes an improvement, the organization still needs to decide who may change the procedure, model, prompt or evaluation rule that governs future cases. A candidate change needs its own evidence, review and rollback path. A successful result on one task should not silently become a new policy for every task.
An “economy of agents” is a useful subject for research when it makes allocation, incentives and coordination explicit. An enterprise design needs to establish who owns the budget, how competing objectives are resolved, whether an agent can game its reward and who bears the consequence of a bad trade. Autonomous negotiation between components does not, by itself, authorize a business commitment.
Choose the architecture by the decision it must support, the evidence it needs and the actions the organization is prepared to authorize. Compound components and independent agents are ways to assemble that service. Use the simplest architecture that handles the real exceptions, and require each added degree of freedom to justify its operating cost.
Related reading
- Model Context Protocol and enterprise integration
- LLM observability and monitoring
- Enterprise adoption of AI code assistants
- Persistent memory and context-aware agents
- Neuro-symbolic AI and multimodal reasoning
Discover more from Ajith Vallath Prabhakar
Subscribe to get the latest posts sent to your email.