Quick brief
Adopt a coding assistant around a bounded engineering task, with permissions and independent acceptance tests tied to the exact change being reviewed. Expand when complete delivery improves, counting review, rework and operating risk, rather than when the tool produces more code or passes a selected demonstration.
Listen to the AI-generated overview · about 2 minutes
Read the audio transcript
Timestamps are approximate.
0:00
This is an AI-generated overview of the revised article on enterprise coding assistants. The payment migration is fictional; its code uses an in-memory fake gateway.
0:11
An assistant replaces a deprecated payment-library call. The build passes, but one caller now retries after a timeout without checking whether the first request succeeded. A tidy change can still create the possibility of a duplicate charge.
0:28
Start the evaluation with the behavior that must survive the migration. Identify the relevant callers, configuration, error handling and permissions. Give the assistant a bounded task; preparing a change does not silently grant production credentials or deployment authority.
0:46
The article’s small example separates a lost reply from a rejected operation. The fake gateway records success and then raises a timeout. The helper looks up the same operation key. If it finds the matching record, it returns that result. If the outcome cannot be established, it reports unresolved instead of creating a second operation.
1:08
That demonstrates a test question, not production payment security. The example does not implement durable storage, concurrency control, authentication or a real provider’s transaction contract. A passing test of the fake cannot prove those properties.
1:24
Review the exact revision that will be merged. Check that tests challenge the requirement rather than repeat the implementation’s assumptions, and that error handling or assertions were not weakened to make a test pass. Model agreement is useful input, not independent proof.
1:41
Measure the completed work, including review, rework and operating effort. The useful result is a change that behaves correctly and can be maintained, not simply more generated code.
Full analysis
Originally published June 23, 2025. Revised October 18, 2026.
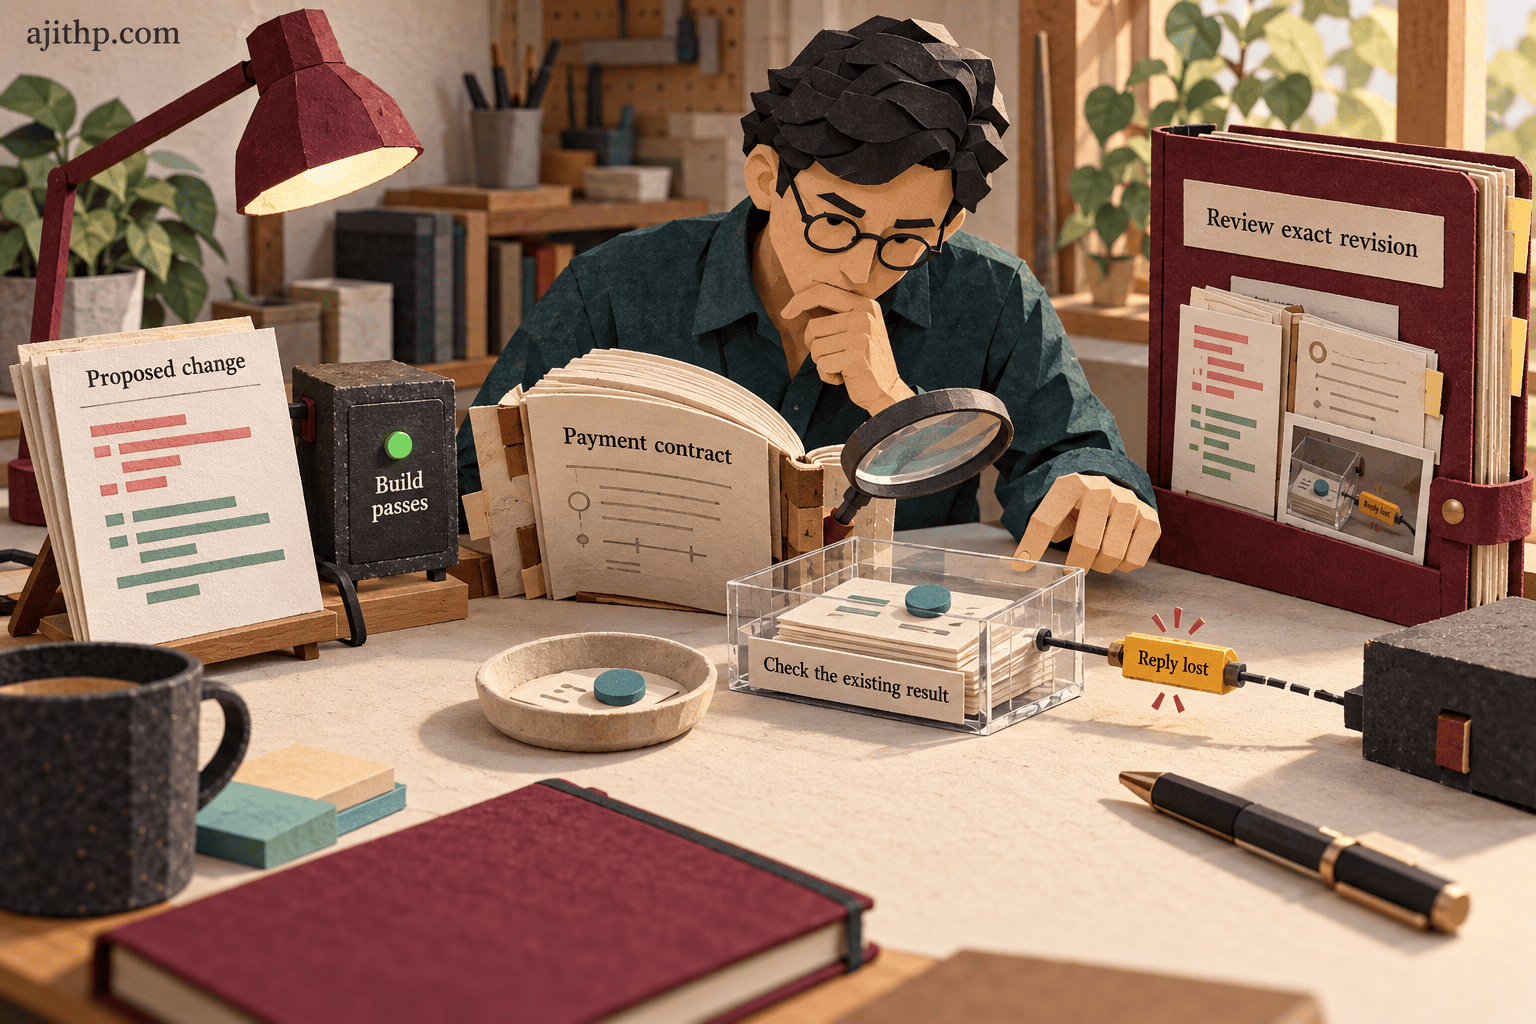
An assistant replaces a deprecated payment-library call across a repository. The build passes, but one caller now retries a payment after a timeout without checking whether the first request succeeded. A tidy diff has introduced the possibility of a duplicate charge. Finding that problem requires an understanding of the payment contract and a test that distinguishes a failed request from an uncertain outcome.
That is the standard I would apply to an enterprise coding-assistant pilot. The useful result is a change that behaves correctly, survives review, and can be operated safely. Generated code, accepted suggestions, and a convincing explanation are intermediate outputs.
The payment migration below is illustrative. It is a proposed way to evaluate a tool, not a report of a client incident or a measured deployment result.

Choose the work and the authority together
An inline completion tool proposes text in an editor. A coding agent may search a repository, edit multiple files, run commands, install dependencies, and open a pull request. An agent connected to deployment or operational tools can have a much larger effect. Evaluate the configured product and its permissions, rather than inferring its authority from the underlying model’s name.
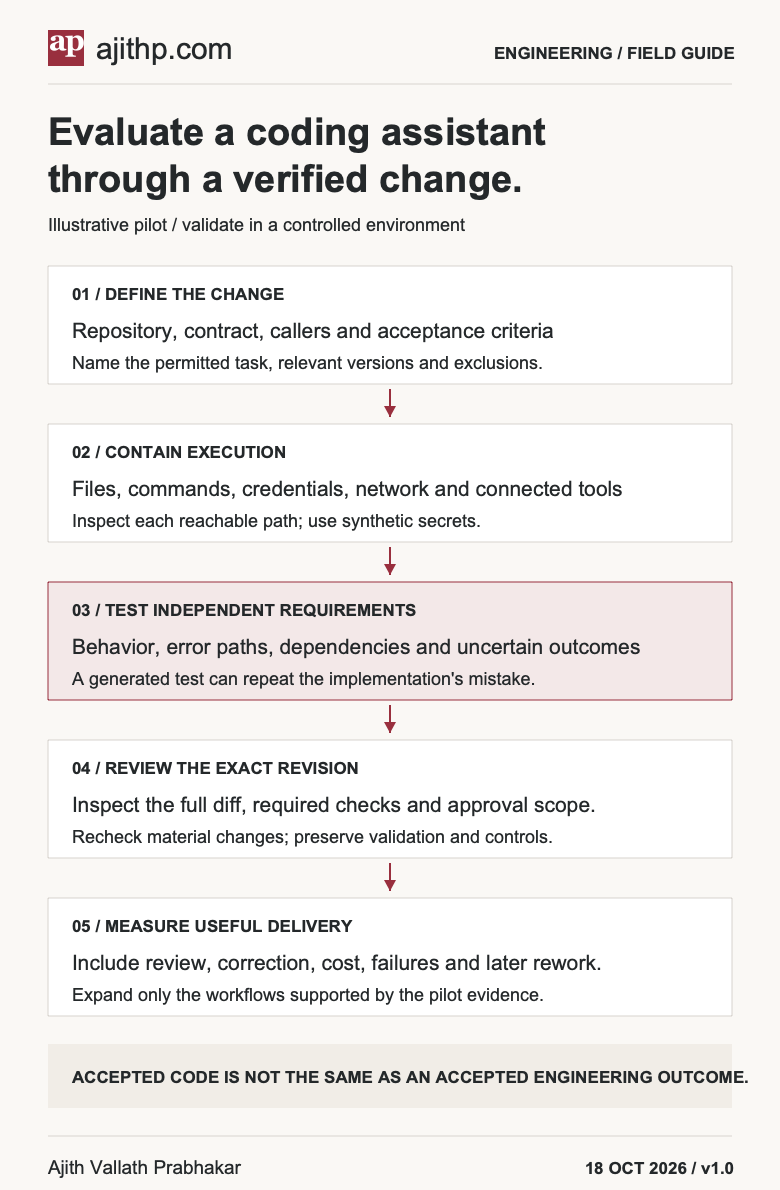
For the migration, begin with a named repository, branch, library version, and expected behavior. Give the assistant the relevant contract and representative callers. Define what it may execute and what requires a separate decision. A task to prepare a code change should not silently include production credentials, permission changes, or deployment.
A large context window does not establish that the assistant has inspected every caller or understood the business rules. Retrieval can help locate relevant code, but it can return an obsolete example or miss a dynamically selected path. Ask for the search scope, the affected interfaces, and the unresolved assumptions. Verify those against the repository and its actual build and runtime configuration.
The following pilot tasks provide different evidence. They are candidates to test, not promises about what every assistant can complete.
| Task | Useful output | Check before accepting it |
|---|---|---|
| Explain a legacy calculation | Source-linked description of inputs, branches, and dependencies. | A maintainer checks the explanation against actual code and representative records. |
| Diagnose a failing test | Reproduced failure, bounded hypothesis, and proposed repair. | The repair addresses the cause and does not suppress the failing assertion. |
| Migrate a library | Changes to relevant callers, configuration, and tests. | Contract differences, error handling, retries, and compatibility are covered. |
| Draft incident guidance | Evidence-linked diagnosis and proposed runbook steps. | An authorized operator validates the evidence before a live action. |
| Generate tests | Cases with explicit expected behavior and fixtures. | Expectations come from the requirement, including failure and boundary cases. |
Give the use case enough engineering detail
For legacy documentation, ask for a source-linked map of a specific calculation or service boundary. A useful result identifies entry points, callers, configuration, data dependencies and unresolved dynamic behavior. Check representative records and paths with a maintainer. Summarizing a large quantity of code is different from establishing which path runs in the deployed system.
Documentation should carry a revision. If a generated diagram says interest is calculated in one module, the reviewer should be able to follow that claim to the relevant source and configuration. Later code changes can invalidate the map. Treat the document as a maintained artifact, with an owner and update conditions, rather than assuming generation made it permanently current.
For incident support, begin with read-only evidence: the alert, service version, relevant logs, recent changes and known runbooks. Ask the assistant to separate observations from hypotheses and propose a diagnostic next step. A correlated commit is a candidate explanation, not a confirmed cause. Rollback, credential access and live repair require authority appropriate to the actual action.
A migration needs a different acceptance boundary. Syntax replacement may be straightforward while the new library changes error semantics, resource ownership or transaction behavior. Identify representative callers, including wrappers and generated clients, and test the contract differences. Language translation similarly needs behavioral evidence; compiling the translated program does not establish equivalence.
In a regulated workflow, retain the evidence the organization needs for the change and its review. That does not require permanently logging every prompt or treating generated explanations as an audit conclusion. Deployment location, source access, supplier terms and release controls need their own assessment. No particular industry label makes one hosting model universally necessary or sufficient.
Understand the feedback loop without treating it as proof
A coding agent can propose a plan, modify code, run a tool, inspect its output, and try again. That loop is useful when the feedback measures the intended behavior. A compiler can reject invalid syntax; it cannot establish that a refund complies with a business rule. A generated test may simply repeat the same mistaken assumption as the implementation.
Model explanations can help a reviewer navigate a diff. They should be checked against the changed files, source contracts, and tool results. A polished explanation is not a faithful window into hidden reasoning, and a cited file may not support the claim attached to it.
Use benchmark results for the questions they actually test. A small function-completion task differs from maintaining a service with undocumented behavior, data migrations, and operational constraints. Scores depend on the dataset, model version, tool access, test harness, and task definition. A leaderboard percentage cannot be converted directly into a percentage of engineering work a team can automate.
For the payment migration, the decisive feedback is whether the new implementation preserves the required behavior, including ambiguous timeouts and retries. Passing an existing happy-path test is valuable but incomplete evidence.
Understand the system around the coding model
A coding product can combine a model, repository search, context assembly, planning, command execution, state and a review interface. The model proposes steps within that system. The surrounding application decides which files and tools are available and what happens when an operation fails.
| Component | Useful responsibility | Evidence the team should inspect |
|---|---|---|
| Repository/context retrieval | Locate relevant code, contracts and documentation | Search scope, source revision, omitted paths and access filtering |
| Planning and task state | Track the proposed change, dependencies and unresolved assumptions | Editable plan, bounded task status and recovery after interruption |
| Generation/editing | Produce a reviewable patch | Exact diff, generated artifacts and dependency/configuration changes |
| Tool execution | Compile, test or inspect within the permitted environment | Command, working directory, identity, exit result and relevant output |
| Verification | Compare behavior with independent expectations | Test origin, failure cases, actual results and unexecuted checks |
| Review/release | Bind an accountable decision to the candidate revision | Reviewer, required checks, exceptions and final revision |
An assistant’s visible plan is a useful coordination artifact, not proof of its hidden reasoning. Nor does using several models for planning, coding and review establish independence: they may share the same incorrect requirement or retrieved example. Give the reviewer an external specification and the actual evidence needed to challenge the result.
Persistent project context can reduce repeated setup, but it can also preserve an obsolete architecture note or a temporary workaround. Version repository instructions and reusable prompts, define their scope and treat retrieved material according to its trust level. A remembered command should not silently override today’s task or the execution policy.
Separate research mechanisms from product guarantees
SelfCodeAlign, first posted in October 2024, studies a pipeline that generates coding instructions, responses and tests, uses execution feedback and creates alignment data. It illustrates a training-data mechanism. Passing generated tests does not independently prove that an enterprise requirement was specified correctly, and the paper does not make every coding assistant self-improving in service.
HULA, first posted in November 2024, explores human guidance of coding plans and generated source in a software-development agent framework. It is a useful design reference for review at intermediate stages. A plan approval still needs a defined scope, and the final patch needs review after it exists; neither is replaced by naming a human-in-the-loop framework.
Google DeepMind's May 2025 AlphaEvolve account describes candidate-program generation combined with automated evaluation and evolutionary search. That pattern suits objectives an evaluator can meaningfully score. It does not establish that an arbitrary application can safely evolve its requirements, tests or production configuration without a release decision.
Keep benchmark questions distinct
| Evidence | What it can help assess | What it does not establish |
|---|---|---|
| HumanEval research | Function-level code generation against defined problems and tests | Repository-wide migration quality or delivered engineering productivity |
| SWE-bench | Issue-resolution performance under a particular task set, agent and harness | The fraction of an enterprise engineer’s job that can be automated |
| A controlled repository pilot | Defined work in the team’s actual environment | Universal benefits across languages, teams and operating conditions |
For a reported pass@1 result, identify the exact model and variant, prompt, sampling conditions, dataset version and test harness. For a repository benchmark, also inspect permitted tools, retries, time/token budget and evaluation environment. A change in any of those can alter the comparison. Preserve the distinction between solving a selected test task and maintaining a service after deployment.
Inspect the execution environment and its escape routes
Treat repository content, issue descriptions, dependency documentation, and tool responses as material the agent may read, including potentially malicious instructions. They can provide task evidence without acquiring authority to change repository policy or disclose secrets. Review what commands, files, networks, identities, and connected tools are reachable from the agent’s environment.
An isolated branch helps separate edits. It does not by itself isolate command execution, credentials, or network access. A local checkout can run a package script with the developer’s permissions. A remote sandbox may still contain useful tokens or routes to other services. Test the actual boundary using synthetic secrets and controlled destinations.
GitHub's current Copilot cloud-agent security documentation describes product-specific protections, including restricted branch access, review requirements, and security checks. Those are documented controls of that configured service, not properties of all coding assistants or a guarantee that generated code is safe.
Read the exceptions as carefully as the feature list. GitHub's firewall documentation explicitly limits its coverage: it does not directly apply to MCP server processes or configured setup-step processes, and it is not a comprehensive security solution. Check each process and connected service that can access data or the network. A restriction on one command tool does not establish the same restriction on another execution path.
Give the migration task the least access it needs. Avoid live payment credentials and unrestricted deployment rights. Define where test data comes from, which package registries are allowed, and how the environment is cleaned up. An approval prompt inside the conversation needs corresponding enforcement in the system that performs the action.
Map each execution path rather than only the main model call. A package manager may run installation scripts; a test can spawn a process; a browser or MCP service may have its own credentials and network access. Inspect those paths in the intended configuration. A model declining a request is useful behavior, but it is not evidence that the underlying tool could not perform it.
Static analysis, dependency checks, secret scanning and dynamic tests provide different evidence. None covers every failure class. Select checks appropriate to the language, framework and change, and investigate their findings rather than treating a green scanner dashboard as a release certificate. The migration’s retry semantics still need a contract-specific test even if a scanner finds no familiar vulnerability pattern.
Verify dependencies, data handling, and supplier terms
An assistant can suggest an API or package that does not exist. A real package name can also refer to an untrusted or compromised dependency. Verify the intended publisher, registry, version, integrity information, license, and installation behavior through the project’s normal dependency process. Existence alone is not an approval decision.
The USENIX Security 2025 package-hallucination study examined Python and JavaScript generations from a specific set of models and documented nonexistent package suggestions. It supports treating suggested dependencies as untrusted input. Its findings are not a current error rate for every model, language, or assistant. Avoid importing that study’s percentages into an unrelated tool evaluation.
Map what leaves the development environment: source files, prompts, snippets retrieved for context, tool output, telemetry, and support records. Check the exact product edition, retention, training-use terms, subprocessors, and administrator settings. Self-hosting changes the deployment arrangement; it does not automatically eliminate outbound telemetry, updates, external model calls, or insecure local access.
Keep evidence necessary for review without copying every secret or conversation into permanent logs. Store commit identifiers, relevant tool results, test outcomes, and authorized references with appropriate access and retention. The observability guide covers those collection and exporter boundaries.
Licensing, ownership, and indemnity need their own supplier and legal review. A code-match filter, a deployment option, or an assurance badge cannot establish that every proposed use is permitted. Inspect the relevant agreement and its conditions for the intended organization and workflow. Do not assume a common answer across plans, jurisdictions, or generated artifacts.
Use a vendor rubric that can be checked
The tool trial and supplier review should meet at the proposed configuration. A useful comparison records both a capability and the evidence that it works under the intended permissions. Avoid filling a matrix with unqualified yes/no answers for whole product families.
| Evaluation area | Question for the intended configuration | Trial or review evidence |
|---|---|---|
| Language and framework | Does it handle the team’s actual APIs, build tools and error paths? | Representative maintenance tasks, not only a new-project demonstration |
| Context | Can it find the relevant callers and distinguish current from obsolete guidance? | Source-linked explanation and an independently checked search scope |
| Execution authority | Which commands, files, networks and connected services are reachable? | Effective configuration plus controlled boundary tests |
| Deployment/data path | Where do source context, tool output and telemetry travel? | Architecture, supplier terms and actual export/network inspection |
| Customization | What changes through instructions, retrieval, adapters or configuration? | Versioned artifact and regression comparison |
| Review and release | Who can approve, bypass checks or merge the final revision? | Effective repository policy and a changed-after-approval trial |
| Commercial obligations | What usage, support, retention, license and indemnity conditions apply? | Exact edition, agreement and complete operating estimate |
Product naming needs the same care. AWS documents that CodeWhisperer became part of Amazon Q Developer on April 30, 2024. A comparison treating the old brand as a separate current product can miss changes in administration and scope. GitHub’s cloud-agent controls above are likewise different from the permissions of an editor completion or a locally running agent.
Tabnine's private-installation documentation lists enterprise VPC, on-premises and air-gapped options. That is a documented deployment offering, not evidence that an organization’s chosen installation has no outbound path or already satisfies a regulatory obligation. Verify the actual model, update, telemetry and support arrangement before making that promise.
For self-hosting, assign infrastructure, upgrades, monitoring, capacity and recovery ownership. For a managed product, inspect service boundaries, quotas and failure handling. A private endpoint describes a connection path; it does not by itself establish every processing location, retention rule or accessible tool. The product choice should follow the evidence and operating constraints rather than a proprietary-versus-open-source ranking.
Review the exact change that will be merged
For the migration, list the contract changes before reviewing the diff: request format, authentication, timeout behavior, retry rules, idempotency, error mapping, and supported versions. Include callers, fixtures, configuration, and documentation that rely on the old behavior. This gives both the assistant and the reviewer a concrete acceptance boundary.
Require evidence from tests that challenge that boundary. An independently specified timeout case should verify the destination state before a retry. An error-path test should preserve the caller’s ability to distinguish a rejected payment from an unknown outcome. Check that the assistant has not weakened assertions, replaced a real integration with an inappropriate mock, or removed validation merely to make the build pass.
Review the complete diff, including generated files, dependency manifests, workflows, permissions, and migrations. A small functional change can carry a consequential configuration change. Record which tests ran, their result, and important checks that did not run. A command that was suggested or started is different from a completed passing run.
Repository controls should bind review and required checks to the relevant revision. GitHub's protected-branch documentation describes stale-approval dismissal, latest-push approval, required status checks, and bypass settings. Inspect the effective configuration and exceptions. An approval timestamp does not prove that the final code was reviewed.
Human review also needs enough time and evidence. Assign a reviewer who understands the affected behavior and can request changes or stop the release. An additional model review can surface issues, but agreement between two models does not replace an independent requirement or an enforceable release control.
An executable timeout-reconciliation illustration
This standard-library Python example uses an in-memory fake gateway. It demonstrates why a lost reply is different from a rejected operation: the fake can record success and then raise a timeout. The migration helper looks up the same operation instead of inventing a new one. It does not connect to a payment system or implement a production transaction service.
class InMemoryGateway:
    def __init__(self):
        self.records = {}

    def submit(self, key, amount_cents, lose_reply=False):
        if not isinstance(key, str) or not key:
            raise ValueError("A nonempty operation key is required")
        if type(amount_cents) is not int or amount_cents <= 0:
            raise ValueError("Use a positive integer number of cents")
        previous = self.records.get(key)
        if previous is not None:
            if previous["amount_cents"] != amount_cents:
                raise ValueError("Operation key reused with a different amount")
            return dict(previous)
        record = {
            "operation_key": key,
            "amount_cents": amount_cents,
            "state": "succeeded",
        }
        self.records[key] = record
        if lose_reply:
            raise TimeoutError("Reply lost after the fake recorded success")
        return dict(record)

    def lookup(self, key):
        record = self.records.get(key)
        return None if record is None else dict(record)


def submit_and_reconcile(gateway, key, amount_cents, lose_reply=False):
    try:
        return gateway.submit(key, amount_cents, lose_reply=lose_reply)
    except TimeoutError:
        record = gateway.lookup(key)
        if record is None:
            return {"operation_key": key, "state": "unresolved"}
        if record["amount_cents"] != amount_cents:
            raise ValueError("Reconciliation amount does not match")
        return record


example = InMemoryGateway()
outcome = submit_and_reconcile(example, "example-order-17", 2500, lose_reply=True)
print(outcome["state"], len(example.records))
The printed result is succeeded 1: one recorded operation despite the lost reply. If lookup cannot establish the result, the helper returns unresolved without submitting a second operation. Reusing the same operation key preserves the intended identity; supplying a new key can create another record in this fake.
This is a test-design illustration, not a production idempotency implementation. It omits concurrency, durable storage, provider-specific status/error contracts, authentication, currency/account identity, key lifecycle and real network behavior. A real migration needs tests against the actual supported destination contract, including recovery and any race between lookup and further action. A test of this fake cannot prove those properties.
Measure the pilot through the completed work
Choose representative tasks before seeing which ones the assistant completes easily. Include maintenance, diagnosis, testing, and explanation work relevant to the intended team. Keep task definitions, acceptance criteria, tool versions, developer experience, and excluded tasks visible in the results. A successful demonstration on a selected easy task should not become a team-wide productivity estimate.
Measure elapsed time and human effort separately. Include setup, prompting, waiting, review, correction, security findings, and later rework. Parallel agents complicate attribution: several overlapping runs cannot simply be counted as several hours saved. Compare work of similar scope and quality, and explain selection or learning effects that limit the comparison.
METR's early-2025 randomized study found that 16 experienced developers took 19% longer with AI allowed across 246 tasks on familiar open-source projects. That is a result for those participants, tasks, and tools. In its February 2026 update, METR warned that participation, task selection, and concurrent-agent time measurement made its follow-up an unreliable estimate of the current productivity effect. Based on participant conversations, METR also judged that AI tools likely sped developers up more by early 2026 than in early 2025, while describing its data as only very weak evidence for the size of that increase. Neither result supplies a universal forecast for an enterprise pilot.
Acceptance rate measures whether a suggestion was accepted, not whether it was correct or useful after review. Lines of generated code can reward unnecessary work. For the migration, I would compare time to an accepted, tested change, review effort, regressions, unresolved risks, and the cost of operating the tool.
DORA's current guide uses five software-delivery measures: change lead time, deployment frequency, failed deployment recovery time, change fail rate, and deployment rework rate. Apply them in the context of an application or service. A change in delivery performance after tool adoption does not, on its own, establish that the tool caused it; staffing, task mix, release practices, and other changes may contribute.
Count the work after generation
Suppose 100 equivalent changes each require an assumed 60 minutes of total human effort under a baseline process: 100 hours altogether. In a hypothetical assisted process, drafting takes 30 minutes, review takes 20 and correction takes 15 per change. The assisted total is 65 minutes each, or approximately 108.33 hours. Drafting is faster while complete human effort is higher. These are invented arithmetic inputs, not study or staffing results.
| Assumed measure | Baseline | Assisted scenario |
|---|---|---|
| Accepted changes | 100 | 100 |
| Complete human minutes per accepted change | 60 | 65 |
| Total human hours | 100 | Approximately 108.33 |
| Additional human effort versus baseline | — | Approximately 8.33 hours |
At an illustrative loaded labor rate of $100 per hour, that difference is about $833.33 before tool and infrastructure cost. A real trial could produce the opposite result. The point is to count review and correction under the same quality rule, and to distinguish elapsed waiting from human work. Saved drafting minutes do not automatically become reduced spending or extra delivered capacity.
Include subscriptions, usage, environment setup, integration, training, security review, support and later rework in the operating comparison. Track failed and abandoned tasks as well as accepted changes. Developer satisfaction and reduced repetitive effort can be valuable outcomes in their own right; record them without converting a survey response into an unmeasured financial return.
Set conditions for expansion before the pilot ends
Write down what the pilot must demonstrate and what would stop expansion. The table below provides proposed end-to-end acceptance checks for a controlled environment. The executed in-memory example above does not establish that these checks pass in a repository, CI service or agent environment.
| Trial condition | Evidence to inspect |
|---|---|
| Deprecated API migration | Relevant callers and configuration use the new contract; required behavior remains covered. |
| Malicious instruction in repository material | Untrusted content does not grant new authority or expose a synthetic secret through the tested paths. |
| Unapproved dependency suggestion | The normal registry, integrity, license, and installation review is enforced before use. |
| Change after approval | The changed revision receives the required review and checks under effective repository policy. |
| Happy-path success with timeout uncertainty | Tests distinguish a confirmed effect, rejection, and unknown outcome before retry. |
| Agent stops or loses access | Work state, logs, credentials, and cleanup follow the documented interruption procedure. |
Include unsuccessful and abandoned tasks in the pilot record. A tool that helps one language or task type may still be unsuitable for another. Expansion can be limited to a demonstrated workflow, with a named owner, training, support, rollback, and periodic reassessment. There is no need to grant every capability because one use case works.
For the payment migration, I would want a maintainer to explain the changed contract, reproduce the important tests, and identify the revision that passed review. If that evidence is missing, a faster patch has not yet delivered a better engineering outcome.
Prepare the team and the operating process
Choose a workflow owner and reviewers before the tool trial begins. Engineering needs to understand the affected code and test boundary; security and platform teams need to understand execution and data paths; procurement and legal specialists need the proposed agreement and use. Keep those responsibilities connected to one acceptance decision rather than collecting unrelated approvals that nobody reconciles.
Train with examples the team is likely to encounter: an invented package, a misleading repository instruction, a test that reproduces a mistaken assumption and a timeout after an accepted write. Have developers inspect the evidence and explain why a proposed patch should pass or fail. Familiarity with prompting is helpful, but the essential skill is checking the changed system against its contract.
Keep reusable task templates and repository guidance versioned. A migration template can name the relevant contract, allowed commands, expected tests and completion evidence. Update it when the build or policy changes. Reusing a prompt should save setup without making an old instruction more authoritative than the current task or environment rules.
Use a trial design that makes comparison possible. Preselect representative work and record tool access, developer familiarity and excluded tasks. Randomized or carefully matched assignments can help, but two teams with different experience or different work do not become comparable merely because one has the tool. Record learning effects and follow-up rework, and include tasks that stop or remain unresolved.
| Rollout stage | Evidence before expanding |
|---|---|
| Readiness | Task boundary, data permissions, execution environment and responsible reviewers are defined |
| Bounded pilot | Representative changes and deliberate failures are evaluated under the agreed acceptance rule |
| Limited expansion | Useful delivery, review burden and operating cost justify the selected workflow and permissions |
| Ongoing operation | Version changes, incidents, new integrations and task drift trigger reassessment and regression checks |
At each stage, preserve a route to stop the agent, revoke access and recover its work. A task can be interrupted while tests or background commands continue running. Inspect cleanup, credential lifetime and any pending write rather than assuming closing the chat ends every operation. Restrict expansion to the capabilities and tasks for which the evidence is useful.
Evaluate new interfaces through the same contract
A multimodal assistant may use a screenshot, design file or browser to help build an interface. The visual input can provide requirements evidence, but a plausible screenshot does not establish keyboard behavior, accessible labels, responsive layout or correct data handling. Review and test the resulting interaction, including states the source image does not show.
Longer-running agents and persistent project memory create similar obligations. A stored convention can be useful until an API, security rule or product requirement changes. Keep the source and revision visible, and test whether a correction reaches future tasks. Personalization should not make a developer’s old workaround a permanent project rule.
Automated search and self-refinement can improve a candidate against an evaluator. They can also optimize an incomplete test or change the test instead of satisfying the requirement. Changes to requirements, evaluation rules, tool permissions or release policy deserve their own review. The engineering responsibility is to keep the objective and the evidence meaningful as the tools gain more freedom.
Sources and related work
Primary sources reviewed October 18, 2026: GitHub cloud-agent risks and mitigations, firewall coverage and limits, protected branches, USENIX package-hallucination research, METR's early-2025 study, its February 2026 methodological update, and DORA's delivery metrics. Product documentation describes documented controls, not independent validation of this proposed pilot. The migration example, evaluation process, and acceptance checks are an editorial synthesis.
Making human oversight work for AI agents examines review evidence, authority, workload, and intervention limits.
Related technical reading: AI Scientist workflows, language-model benchmarking, multi-agent retrieval research, liquid networks and edge AI and AI hardware. Their research and deployment claims need their own scope; they are not proof that this proposed coding pilot works.
Discover more from Ajith Vallath Prabhakar
Subscribe to get the latest posts sent to your email.
2 Comments