Quick brief
Choose benchmarks for the capability you need, then test the complete workflow against acceptance rules drawn from your own tasks. Preserve the dataset, prompt, sampling, tool, and scoring conditions behind every result because the same benchmark name can conceal materially different experiments.
Full analysis
Revised October 18, 2026.
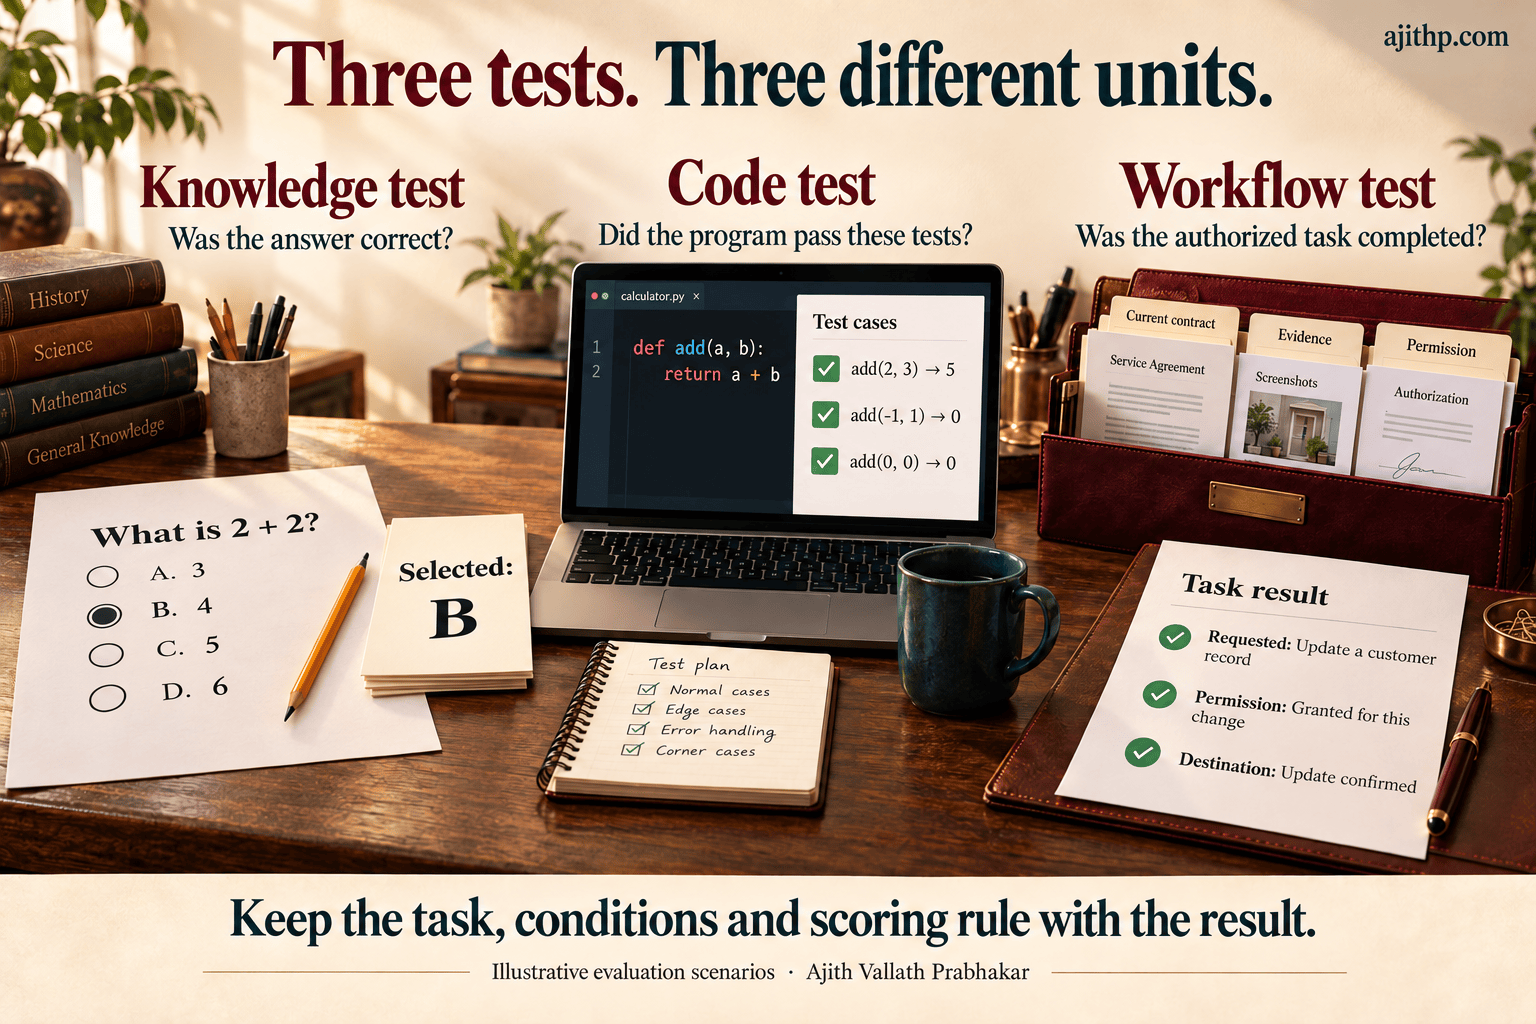
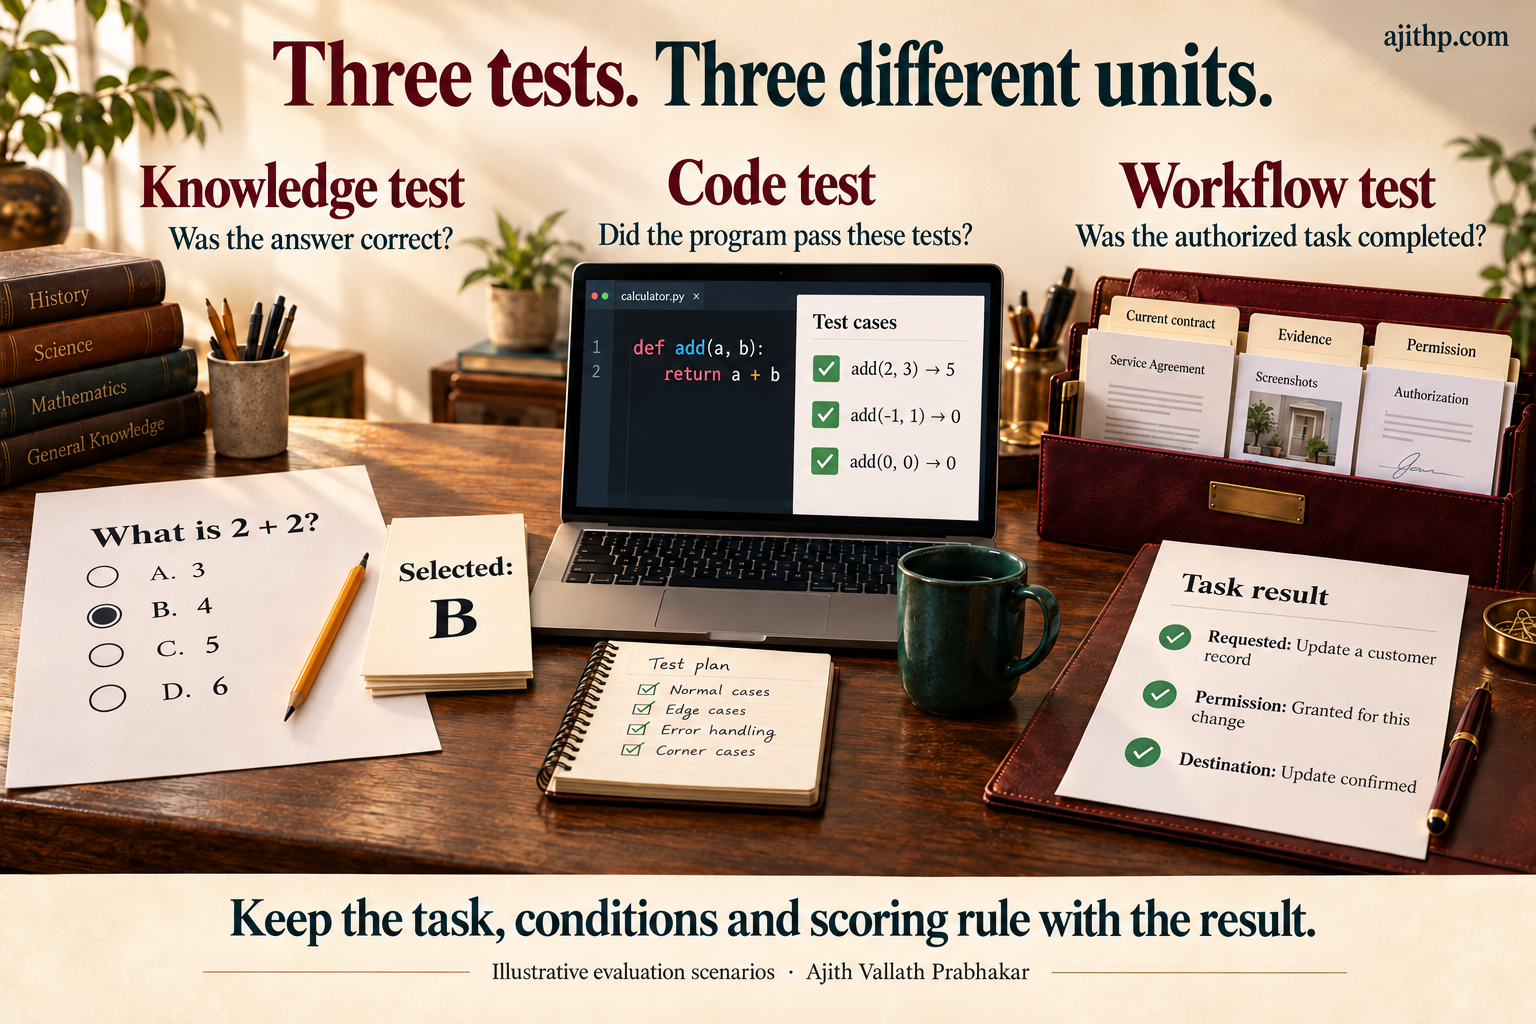
A model comparison can put MMLU accuracy, HumanEval pass@1 and a customer-support success rate in adjacent columns. All three are useful measurements. They count different things, and none supplies the missing definition of a successful support interaction.
That definition is where I would start. If the proposed system answers a question about a customer’s contract, it needs the current contract, a supported answer and a way to stop when the evidence is missing. If it can also change the account, the evaluation must cover permission and the consequences of that change. A strong multiple-choice score does not test those conditions.
Public benchmarks still earn their place. They offer shared tasks, repeatable comparisons and a way to identify weaknesses before spending time on integration. Building every test from scratch would waste useful work. The mistake is carrying a public score into a deployment decision without carrying its task boundaries and experimental conditions with it.
This guide retains the 20-entry benchmark directory first published in July 2024. It is a historically bounded directory, not a current inventory of agentic or tool-use benchmarks. The descriptions below distinguish the original research task from the wider conclusions people sometimes attach to it. Dates identify the benchmark’s origin, rather than implying that its original model rankings describe today’s systems.
Choose the task before the benchmark
For a customer-support assistant, separate retrieving the right policy, interpreting the customer’s request, composing a supported response and performing any authorized action. These are related capabilities, but a single question-answering dataset will not measure the entire sequence.
SQuAD can help assess extracting an answer from a supplied passage. It does not directly measure sentiment classification, intent routing or successful resolution across a customer’s account history. A conversational QA task can examine answers in dialogue context, but that still leaves business rules, tool failures and escalation outside the score unless the evaluation includes them.
An illustrative contract-support evaluation might contain ordinary questions, conflicting document versions, missing amendments, requests outside the user’s authority and cases requiring a human decision. Specify the expected evidence and acceptable behavior before generating answers. An answer that correctly declines an unsupported request can pass; a fluent answer built from an obsolete clause should fail.
Use a public benchmark to investigate a relevant component, then test that component within the actual workflow. Preserve separate results for answer quality, evidence support, abstention, authorized actions, latency and cost. Combining them into an overall acceptance rate is useful only after the acceptance rule is explicit.
Adapt a private evaluation without changing the public score’s meaning
A medical translation task needs examples containing the terminology, ambiguity and error consequences that matter in that setting. That is a sound reason to create a domain evaluation. It is not a reason to change a public benchmark’s examples or scoring and continue reporting the result as though it were the original benchmark.
Keep the named public result and the private domain result separate. Record which translation directions, document types and reviewers the private set covers. Have the relevant domain expertise define serious errors; lexical overlap alone may miss a mistranslated dose or negation. A convenient automatic metric can support triage without becoming the only acceptance criterion.
Separate training material, prompt-development examples and the final holdout. Few-shot demonstrations and fine-tuning can improve the system, but repeatedly adapting them against the final test set consumes that test’s independence. When a test case becomes a development example, retain it as a regression case and reserve other cases for the next independent comparison.
A reference table for the original 20 entries
The table separates datasets and benchmark suites from an evaluation framework. It is a navigation aid; the scoring details and limitations follow it.
| Benchmark or framework | Main task | What the result counts |
|---|---|---|
| MMLU | Multiple-choice knowledge across 57 subjects | Answer accuracy under a stated aggregation and prompt protocol |
| GLUE | Nine English language-understanding tasks | A composite of task-specific metrics |
| SuperGLUE | Eight English understanding tasks | A composite including accuracy, F1 and exact match as specified per task |
| HumanEval | Python function completion | Functional test success, commonly reported as pass@k |
| GSM8K | Grade-school arithmetic word problems | Correct extracted final answers |
| SQuAD | Passage-based question answering | Normalized exact match and token-level F1; version 2 adds unanswerable questions |
| MATH | Competition mathematics problems | Final-answer accuracy with specified normalization/equivalence rules |
| ARC | Grade-school science questions | Multiple-choice accuracy on Easy and Challenge subsets |
| WinoGrande | Two-choice contextual commonsense problems | Correct option selection |
| LAMBADA | Final-word prediction using discourse context | Correct target-word prediction under the evaluation protocol |
| CommonsenseQA | Commonsense multiple-choice questions | Correct choice among five options |
| HellaSwag | Plausible continuation of an activity description | Correct choice among four endings |
| C-Eval | Chinese exam questions across 52 disciplines | Multiple-choice accuracy, including subject/level breakdowns |
| MBPP | Basic Python programming | Generated programs passing the specified tests |
| MGSM | Multilingual arithmetic word problems | Final-answer accuracy by language and prompting condition |
| PlanBench | Formal planning and reasoning about actions/change | Task-specific correctness, including plan validation |
| Mementos | Reasoning over image sequences | Object/behavior description metrics in the published evaluation |
| FELM | Detecting factual errors in model-generated text | Evaluator precision, recall, F1 and balanced accuracy |
| OpenAI Evals | Framework and registry for custom evaluations | Whatever the selected evaluation and grader define |
| TruthfulQA | Questions targeting common misconceptions | Truthfulness/informativeness or specified multiple-choice measures |
MMLU: broad subject coverage needs an explicit aggregate
MMLU, introduced in 2020 and published at ICLR 2021, tests multiple-choice knowledge across 57 subjects. Its coverage includes STEM, humanities, social sciences and professional topics. That breadth makes it useful when a model must handle varied questions rather than a single narrow domain.
The basic observation is whether the selected answer is correct. The original repository’s evaluator concatenates question-level correctness across subjects for its overall accuracy; an unweighted mean of subject accuracies is a different aggregate when subjects contain different numbers of questions. A comparison should identify which it uses.
Record the number and selection of demonstrations, answer-extraction method and whether the model selects from option probabilities or generates an answer. A subject breakdown can reveal weaknesses hidden by an overall result. Even strong performance does not establish general intelligence, current professional competence or reliability on a firm’s documents.
GLUE: preserve each task’s metric
GLUE, introduced in 2018, brings together nine English language-understanding tasks: CoLA, SST-2, MRPC, STS-B, QQP, MNLI, QNLI, RTE and WNLI. The tasks cover grammatical acceptability, sentiment, paraphrase, similarity and inference-related judgments.
Accuracy is not the universal unit. CoLA uses Matthews correlation, STS-B uses correlation measures, and paraphrase tasks include F1 alongside accuracy. The composite combines task results using the benchmark’s rules, including how tasks with multiple metrics are summarized.
Keep the individual results. A model that is useful for sentiment classification may remain weak at textual entailment. GLUE also provides a historical comparison point for representation learning; its original difficulty should not be described as the current limit of language systems. It supplies little direct evidence about tool use, long document workflows or action permissions.
SuperGLUE: a harder successor with a defined task mix
SuperGLUE, introduced in 2019, contains BoolQ, CB, COPA, MultiRC, ReCoRD, RTE, WiC and WSC. These tasks include question answering, entailment, word-sense comparison and coreference. COPA asks about plausible causes or effects, within a specific multiple-choice format.
The suite combines task-specific metrics. For example, CB includes accuracy and F1, MultiRC includes answer-level F1 and exact match, and ReCoRD includes F1 and exact match. Reproduce the aggregation rather than averaging every number printed in a result table.
The original purpose was to provide a more demanding successor to GLUE. That is useful historical context, not a promise that the suite continues to differentiate every current model. Its compact task mix can expose particular failures while leaving many deployment requirements untested.
HumanEval: state the sampling budget behind pass@k
HumanEval, released with the 2021 Codex paper, presents Python function-completion problems with signatures and docstrings. Generated functions are executed against tests. The benchmark examines functional behavior rather than merely whether the code looks plausible.
Pass@k estimates the chance that at least one of k sampled completions passes the tests. With n samples and c correct completions for a problem, the standard estimator is one minus the ratio of the number of ways to choose k failures to the number of ways to choose any k samples. The repository requires sufficient samples for the reported k.
Pass@1 and pass@100 describe different opportunities to succeed. Also record temperature, execution limits and the sampling procedure. Passing this finite test suite does not establish security, maintainability or correctness across a real repository. Generated code needs an isolated evaluation environment; the benchmark is not permission to execute arbitrary completions on a developer’s machine.
GSM8K: worked solutions do not make the score a reasoning audit
GSM8K, released in 2021, contains approximately 8.5 thousand grade-school arithmetic word problems. The supplied solutions use multiple steps, typically involving elementary arithmetic, so it is useful for checking more than isolated calculation.
The repository’s reference answer-extraction code parses the final numeric answer after the #### delimiter and compares it with the reference. The dataset’s worked solutions and calculation annotations are valuable training and analysis material. They do not mean that final-answer accuracy independently validates every intermediate statement in a generated rationale.
If your application needs a verifiable calculation trail, assess that trail separately. A correct final number can coexist with a faulty explanation, and a formatting failure can make an otherwise correct solution unscorable. Keep the answer parser fixed across comparisons and report any additional tool or calculator access.
SQuAD: answer extraction and abstention are distinct requirements
SQuAD began in 2016 as questions over Wikipedia passages. In SQuAD 1.1, the answer is a span in the supplied passage. SQuAD 2.0, introduced in 2018, adds questions that cannot be answered from that passage.
Evaluation uses normalized exact match and token-overlap F1 against reference answers. Version 2 additionally requires deciding when to return no answer, so threshold choices and answerability handling matter. Comparing a version 1 score with a version 2 score as if they were one experiment loses that distinction.
This is a useful test of extracting supported information from a given context. Retrieval quality, document access control and whether the passage is the current authorized source are separate questions. A contract assistant can extract a clause perfectly and still fail the business task by retrieving an obsolete agreement.
MATH: use the final-answer protocol and inspect errors by subject
MATH, introduced in 2021, contains 12,500 competition mathematics problems. Its seven subjects are prealgebra, algebra, number theory, counting and probability, geometry, intermediate algebra and precalculus. Problems carry difficulty labels and worked solutions.
The original evaluation extracts the final boxed answer and compares it with the reference using specified formatting and equivalence handling. This supports automated final-answer accuracy. It does not turn the standard score into a proof checker for the complete generated solution.
Subject and difficulty breakdowns can be more informative than a single number. Also identify the actual dataset: the complete original MATH test set and a later subset are different evaluations. If a workflow needs a proof or a defensible derivation, introduce an appropriate verification method instead of treating final-answer accuracy as sufficient.
ARC: identify the science benchmark and its split
AI2 ARC, introduced in 2018, is a grade-school science question set divided into Easy and Challenge subsets. The Challenge construction selected questions that particular retrieval and word-co-occurrence methods failed to answer. That construction matters when interpreting what made it difficult.
Models select an answer from the provided choices, and accuracy is reported separately for each split. Preserve the actual option set rather than assuming every example has four choices. Also distinguish AI2’s AI2 Reasoning Challenge from the unrelated Abstraction and Reasoning Corpus, which shares the abbreviation ARC.
The science questions can expose failures to combine knowledge and question context. They do not establish that the model can conduct scientific work, retrieve current evidence or safely advise on a technical incident. Those require their own tasks and evidence standards.
WinoGrande: contextual choice does not reveal how the answer was obtained
WinoGrande, first released in 2019, scales up the Winograd-style commonsense task using two-option fill-in-the-blank questions and adversarial filtering. Models must choose which candidate makes sense in the sentence’s context.
Accuracy gives a clear answer-selection measure. Training-set size and evaluation setup still matter, particularly when comparing systems adapted to the benchmark with systems used without such adaptation. Do not assume that a two-choice format makes the underlying reasoning trivial.
The practical use is to probe sensitivity to contextual relationships that simpler lexical associations can miss. The limit is equally clear: a correct answer alone cannot distinguish reasoning from memorization, contamination or another successful shortcut. Treat a score as observed behavior on these items.
LAMBADA: broader discourse is a specific kind of context test
LAMBADA, published in 2016, asks a model to predict the final word of a passage. Its construction emphasizes cases where broader discourse helps human readers identify that word, rather than relying only on the immediately preceding sentence.
The main task is target-word prediction. Tokenization, output restrictions and preprocessing can affect how a modern model’s output is converted into a word-level result. Preserve those conditions when reproducing a score.
LAMBADA remains a useful historical example of moving beyond very local context. It should not be stretched into a test of every long-context capability. Finding an amendment in a large document collection, maintaining an account state over time and predicting a final word are different operations, even though all involve context.
CommonsenseQA: retain the five-choice task boundary
CommonsenseQA, introduced in 2018 and published in 2019, contains five-option questions designed around commonsense relationships. Choosing the correct option can require distinguishing plausible alternatives rather than merely completing familiar wording.
The basic metric is answer accuracy on the specified split. Record whether the system has been trained on the benchmark and whether extra retrieval or explanations are used at inference time. Those choices change the comparison.
The dataset provides a way to investigate everyday knowledge questions. High accuracy does not prove that the model avoided memorization or that it will make sound decisions in unfamiliar physical or social situations. For a practical assistant, use it as one diagnostic alongside scenarios drawn from the assistant’s actual responsibilities.
HellaSwag: plausible continuation under adversarial construction
HellaSwag, published in 2019, presents an activity context with four possible continuations. Its adversarial filtering process was designed to select machine-generated wrong endings that were difficult for contemporary models to reject.
Evaluation measures whether the model selects the correct ending. Choice likelihood scoring and free-form answer generation can introduce different extraction and length effects, so the procedure belongs in the result record.
The original study’s model results describe its period and setup. The continuing lesson is about benchmark construction: plausible-looking alternatives can expose weaknesses that an easier dataset hides. Success on these continuations does not independently establish a causal model of the world or dependable physical planning.
C-Eval: inspect subjects and language requirements
C-Eval, introduced in May 2023, evaluates Chinese-language exam questions across 52 disciplines and four difficulty levels: middle school, high school, college and professional. It also provides a harder subject subset.
Scores are based on multiple-choice answer accuracy. Subject coverage, prompts and demonstration choices matter; report the overall measure together with relevant breakdowns. A result on Chinese professional exam questions is evidence about that task distribution, not all Chinese-language communication.
This makes C-Eval useful when an English-only comparison would omit a major requirement. It does not establish suitability for every dialect, local institution or business process. A multilingual deployment still needs its own terminology, document and user-interaction tests.
MBPP: name the dataset variant and test budget
Mostly Basic Python Problems, released in 2021, contains 974 crowd-sourced Python tasks. Each includes a description, reference solution and tests; a sanitized version is also provided.
Generated programs are checked against the selected tests. Record the dataset variant, train/development/test split and whether several completions were sampled. A result on the sanitized subset cannot be compared casually with a result over a different collection of tasks.
MBPP is useful for examining small programming tasks before attempting repository-scale work. Its compact programs leave dependency management, architecture, integration, permissions and production review outside the evaluation. Those omissions are reasons to add engineering tests, not reasons to discard a useful programming benchmark.
MGSM: keep language and final-answer results separate
MGSM, introduced in 2022, takes 250 GSM8K problems and translates them into ten additional languages. The English originals provide another comparison condition; the work does not translate the complete GSM8K dataset.
The paper compares prompting approaches, including different languages for the generated reasoning, while evaluating final-answer correctness. A rationale can help obtain an answer without itself becoming an independently graded proof. Results should identify the question language, demonstrations, reasoning condition and answer extraction.
Report languages separately before computing an aggregate. A strong average can conceal poor performance in one language, and translated arithmetic does not cover every local language requirement. It is a useful controlled comparison of mathematical tasks across languages rather than a certificate of universal multilingual competence.
PlanBench: validate plans against the formal task
PlanBench, first posted in 2022 and presented at NeurIPS in 2023, uses automated-planning domains to test planning and reasoning about actions and change. Its formal task structure allows generated plans to be checked against relevant preconditions and goals with a plan validator such as VAL.
The research repository supplies task-generation and evaluation material. Report the particular task, domain and validator. Plan generation, checking a plan and answering questions about state changes are related but different measurements.
A model can write a convincing plan that is invalid under the domain rules. This is precisely why formal validation is valuable. The benchmark should not be described as a general score for project management, organizational strategy or adaptation to any unexpected event; those claims exceed the specified planning environment.
Mementos: image-sequence reasoning, not conversational memory
Mementos, introduced in January 2024, evaluates multimodal models on sequences of images. It asks whether a generated description correctly represents objects and their changing behaviors across the sequence.
The published collection contains 4,761 image sequences. Its evaluation extracts object and behavior keywords from generated and reference descriptions with GPT-4 assistance, normalizes relevant synonyms and computes object/behavior measures including precision, recall and F1. The evaluator configuration is therefore part of the experiment.
This probes temporal visual description and associated hallucinations. It does not test whether a conversational assistant remembers a user’s preferences or maintains entity facts across a dialogue. The distinction matters when choosing evidence for a persistent-memory system: sharing a memory-related name does not make the tasks interchangeable.
FELM: evaluate the factuality evaluator
FELM, introduced in October 2023, contains model-generated responses annotated for factual errors at the text-segment level. Its five domains are world knowledge, science and technology, mathematics, writing and recommendation, and reasoning; annotations include error information and supporting or contradicting references where provided.
The evaluated system is a factual-error detector. The paper reports detection F1 with precision and recall, and balanced accuracy, at segment and response levels. This differs from reporting the fraction of facts in a new generation that are supported.
For an enterprise evaluation, the distinction is useful. A judge used to score an assistant can itself miss errors or flag correct statements. FELM provides evidence about such evaluators, while a production grading procedure still needs calibration against the task’s own human-labelled cases and evidence sources.
OpenAI Evals: a framework needs a specified evaluation
OpenAI Evals is an open-source framework and registry, rather than one benchmark with a universal score. It supports constructing and running evaluations for language models and systems built around them.
An eval still needs examples, a task definition, a grader and a result interpretation. A deterministic exact-match grader and a model-based rubric answer different questions. Version the grader as well as the model, and test whether the grader accepts known correct behavior and rejects known failures.
The repository can support custom evaluations and reproducibility. Its existence does not make every contributed test equally appropriate, and this description does not imply that the repository and every current hosted evaluation product have identical behavior. Specify the implementation you actually used.
TruthfulQA: misconception resistance has a defined distribution
TruthfulQA, introduced in 2021, asks questions designed to elicit false answers associated with common misconceptions. It provides a useful way to investigate whether a model repeats plausible falsehoods.
The work includes free-form evaluation of truthfulness and informativeness and multiple-choice evaluation with its own definitions. In January 2025, the authors introduced a binary-choice variant and recommended it for new comparisons; label it separately from the original MC1/MC2 results. Report the task variant and grader. A truthful but uninformative response is different from a useful correct answer, and the metric should preserve that difference.
The result concerns these questions and their evaluation. It does not establish honesty as an internal property, complete factual reliability or sound uncertainty calibration across domains. A system answering current contractual or medical questions needs evidence checks on those tasks, even if it does well on misconception-focused questions.
Make the result reproducible enough to challenge
Keep a run record containing the exact model identifier, relevant system/prompt text, dataset version and split, sampling settings, tool access, retry policy, parser, grader and scoring aggregate. Record failures to produce a scorable answer as well as successful outputs. Otherwise, two nominally identical benchmark runs can count different populations.
Suppose two illustrative support configurations each receive 100 cases. One closes 80 cases, five of which rely on a superseded policy; the other closes 77 using current evidence. If current evidence is part of acceptance, the first has 75 acceptable results and the second 77. A fluency score would miss the difference. Compare the cost and time of all attempts against those accepted outcomes, including failures and review effort.
Do not let that overall rate conceal a critical action error. If the system changed an account without permission, record the failure separately even if the average looks favorable. Keep task categories and severity visible so the evaluation supports an actual release decision.
Public datasets may overlap training or prompt-development material. When that history is unavailable, say so and use new, held-out task evidence alongside public results. This does not require claiming that every good score is contaminated; it requires leaving open explanations the experiment cannot distinguish. Small test sets and nondeterministic outputs also make tiny rank differences a weak basis for a large procurement decision.
Broaden coverage when the workflow requires it
The original guide identified multimodal evaluation, fairness, interactive tasks, adversarial robustness, domain work, collaboration and long-horizon planning as important directions. Those remain useful dimensions for selecting tests. They are not all future capabilities waiting for a benchmark: Mementos already demonstrates how one multimodal dimension can be specified.
An interactive task should record state transitions and tool outcomes. A fairness evaluation needs relevant populations, error definitions and consequences. An adversarial test needs a stated threat model and enforceable boundaries. A collaboration study needs a human task and a way to tell whether assistance improved the outcome, rather than only increased confidence.
For longer tasks, inspect intermediate evidence and recovery as well as the final answer. A successful result reached after an unauthorized action remains a failure of the workflow. A system that safely stops at missing information may be doing exactly what its owner intended.
The directory gives a starting set of instruments. Choose the ones that fit the capability, preserve their protocols and add the evidence the deployment requires. The final decision should be explainable in terms of a task the organization needs completed and the observed conditions under which the system completed it.
Discover more from Ajith Vallath Prabhakar
Subscribe to get the latest posts sent to your email.
One Comment