Quick brief
AI hardware is a system choice: model, memory, interconnect, precision, software, and operating conditions determine whether a chip is useful for a workload. GPUs and specialized accelerators serve different needs, while neuromorphic, optical, and quantum systems remain distinct in maturity and purpose.
Listen to the AI-generated overview · about 2 minutes
Read the audio transcript
Timestamps are approximate.
0:00
This is an AI-generated overview of Ajith Vallath Prabhakar’s article on AI hardware. The translation app example is fictional.
0:09
A phone app needs to translate a conversation without a reliable connection. A processor’s impressive arithmetic rating does not settle the choice. The model must fit in memory, run through a supported runtime, and produce a useful translation within the device’s heat and battery limits.
0:28
The article starts there, with the work around the chip. A GPU can perform many operations in parallel. A TPU targets supported tensor workloads. An NPU may run eligible neural network operations locally. None of those labels establishes which complete application will be faster or use less energy.
0:49
For the translation app, compare the actual model, language, precision, response time, output quality, and whole device power. Integration in a system on a chip can reduce some transfers, while constraining cooling and upgrades. A configurable FPGA offers a different tradeoff: custom data paths, with substantial implementation and testing work.
1:12
The historical examples also need dates. A product announcement, a shipping system, and a research result are different evidence. Manufacturer comparisons remain manufacturer comparisons, unless independently reproduced under matched conditions.
1:27
The same care matters with newer architectures. Neuromorphic systems explore event-driven computation; that does not mean every chip learns continuously. Photonics can connect processors, perform certain optical calculations, or form part of a quantum system. These are distinct uses of light, not interchangeable promises of faster AI.
1:49
For the app, the decision comes back to supported software, acceptable translations, sustained operation, and the complete cost. The article’s diagrams keep those system boundaries visible, without declaring a universal winning chip.
Full analysis
Revised October 18, 2026.
This article first appeared on 1 January 2025. The hardware examples and company table preserve that historical point of view. Dated October 2026 product and company context is added throughout; this is not a current market ranking. Product specifications and efficiency claims attributed to manufacturers are vendor claims, not independent comparisons.
Artificial intelligence depends on more than a processor. The model, memory system, interconnect, precision, software stack, and deployment environment all shape performance. Graphics processing units (GPUs) made large-scale parallel computation broadly available. Google’s tensor processing units (TPUs), neural processing units (NPUs), and other accelerators target particular operations or deployment settings. Field-programmable gate arrays (FPGAs) trade fixed-function efficiency for reconfigurability. System-on-chip designs combine several processing elements in one package. Neuromorphic and photonic systems explore different ways to compute or move information.
Those categories overlap. A phone SoC may include a CPU, GPU, and NPU. A TPU is an application-specific integrated circuit (ASIC), as are many NPUs. The right comparison begins with the work a system must perform, the quality it must reach, and the power, latency, cost, and software constraints around it.
Deloitte’s December 2024 Tech Trends discussion put sales of chips used only for generative AI above $50 billion in 2024. It forecast AI-chip sales of up to $400 billion by 2027, with a more conservative estimate of $110 billion. Those figures describe different scopes and years, and the 2027 figures are forecasts. A market estimate only helps a hardware decision when it is clear what the estimate includes. Deloitte, “Hardware is eating the world”
A historical perspective on AI hardware evolution
For much of computing, the CPU was the standard engine for general-purpose tasks. Deep learning increased demand for parallel operations over large matrices and tensors. Reinforcement learning also broadened the range of model-training workloads, although it did not define a separate chip category. GPUs were built for graphics workloads that also require many operations to run at once. Researchers learned to use that parallel capacity for neural-network training and inference.
The 2012 AlexNet paper is one visible milestone. It described a convolutional neural network trained with a GPU implementation, and its ImageNet results helped establish deep learning’s practical potential at scale. It did not make GPUs the only useful architecture; it showed what large datasets, network design, and parallel compute could achieve together. Krizhevsky, Sutskever, and Hinton, “ImageNet Classification with Deep Convolutional Neural Networks”
Specialized accelerators followed. Google’s first-generation TPU had been running inference workloads in its datacenters since 2015; Google publicly described the chip in 2016, and a 2017 paper analyzed its production performance. That chronology matters: internal deployment, public announcement, and publication are different dates. The original TPU study concerned a particular inference workload mix and a contemporary CPU/GPU baseline. Its results should not be generalized to every later model or accelerator. Google’s TPU paper
By the late 2010s and early 2020s, mobile and edge processors increasingly included dedicated blocks for neural-network operations. These blocks can run supported models on-device, but they work alongside CPUs, GPUs, memory, and software runtimes. A manufacturer’s TOPS figure describes a peak arithmetic rate at a specified precision. It does not, by itself, show the speed or energy use of a real application.
In 2020, Qualcomm’s Snapdragon 865 brought the Hexagon 698 processor and fifth-generation Qualcomm AI Engine to flagship smartphones. Qualcomm described on-device uses in photography, voice interactions, gaming, and real-time translation. Its launch claims and TOPS ratings are vendor specifications for that mobile platform, not general NPU measurements. Snapdragon 865 product page · Qualcomm’s 2020 device announcement
A 2024 research thread explored “MatMul-free” language models. The term describes an algorithmic/model design that reduces or removes matrix multiplication in selected models; it is not a new hardware family. The paper evaluated models up to 2.7 billion parameters and an FPGA implementation, and reported specific experimental results. Those findings motivate hardware co-design, but do not establish that matrix multiplication has disappeared from production LLMs or that a general-purpose FPGA is now more efficient than a GPU. “Scalable MatMul-free Language Modeling”
Foundational pillars of modern AI hardware
The sections below describe the role each architecture can play. Performance claims depend on the model, input shape, precision, batch size, memory capacity and bandwidth, software kernels, utilization, and the full system around the chip. A useful benchmark reports those conditions alongside latency, throughput, output quality, power, and cost.
GPUs: the backbone of AI training
How they work
GPUs contain many processing elements designed to perform work in parallel. Neural-network training uses this parallelism for matrix multiplication, convolution, and other tensor operations. Specialized units such as NVIDIA Tensor Cores accelerate supported operations at selected numeric precisions. High-bandwidth memory can reduce data bottlenecks, though the benefits depend on model size, access patterns, and how well the workload uses the device.
Features and system behavior
A GPU is not simply a collection of interchangeable cores. The memory hierarchy, kernel implementation, interconnect, compiler, and batch shape can matter as much as a peak arithmetic number. Distributed training adds communication overhead between devices. Inference introduces a different balance: batch size and memory traffic may dominate, while latency requirements can limit batching.
Applications
Common GPU roles include training large language and vision models, serving models in data centers, scientific computing, image processing, simulation, and specialized inference. Finance is another long-standing use area: GPUs can run parts of market simulation and fraud-detection workflows, but the result depends on the model, data pipeline, validation, and decision process around the accelerator. In medical imaging or financial analysis, a GPU may execute part of a larger workflow; that does not establish clinical accuracy, regulatory suitability, or a financial outcome. Those depend on the entire application and validation process.
Example: A100, H100, and GPT-4
NVIDIA announced its Hopper architecture and H100 in March 2022. The company’s H100 and DGX materials describe hardware specifications and vendor benchmarks, including performance figures tied to precision and system configuration. They are useful product references, not evidence that H100 is “unmatched” for every AI workload. NVIDIA Hopper announcement · DGX H100 datasheet
The January 2025 article attributed GPT-4 training to A100 GPUs, described petabytes of data across thousands of devices, and claimed an energy reduction. Those details are not public in OpenAI’s GPT-4 technical report. OpenAI explicitly says it does not provide further detail about the model’s hardware, training compute, dataset construction, or similar information. The A100, data-volume, cluster-size, and energy claims therefore cannot be presented as known facts. OpenAI, GPT-4 Technical Report, “Scope and Limitations”
H100 remains a useful historical example of a GPU generation. As of October 2026, NVIDIA’s product family has moved beyond Hopper. Any current-generation comparison should name the exact chip and system, the workload and precision, and whether the result comes from the vendor or an independent test.
IPUs and graph workloads
Graphcore’s Intelligence Processing Unit (IPU) is a highly parallel machine-learning processor with substantial on-chip memory and a software stack designed around its architecture. This can be relevant for models with irregular data access, including some graph neural networks. Graphcore has published a temporal graph network example for recommendation-style data and compared a single IPU with an NVIDIA A100. That is a vendor-authored result for the described experiment, not proof that IPUs generally outperform GPUs in bioinformatics, recommendation, or other graph workloads. Graphcore IPU architecture · Temporal graph network example
TPUs: specialized tensor accelerators
Architecture and software
Google designs TPUs for machine-learning operations such as matrix multiplication and tensor processing. The original TPU was an inference accelerator. Later generations support training and inference at datacenter scale. TPUs run within a system that includes host processors, high-bandwidth memory, inter-chip links, network fabrics, cooling, and Google’s compiler and framework integrations.
A specialized accelerator can offer strong performance for supported operations and model shapes. That does not make it automatically more efficient than a GPU. The answer changes with workload, precision, compiler, utilization, system configuration, and cost basis. Google’s published comparisons should be read as Google’s measurements on the named workloads and systems.
PaLM, PaLM 2, and TPU generations
The January 2025 article combined details from two models when it described PaLM 2 as a 540-billion-parameter model trained on TPU v4. The 540B model was PaLM, announced in 2022; Google’s PaLM paper describes training with 6,144 TPU v4 chips. PaLM 2 was reported separately in 2023, with multiple model sizes and no public 540B parameter count. PaLM paper · PaLM 2 Technical Report
Applications
TPU workloads have included language-model training and inference, computer vision, and recommendation models. Recommendation systems often combine large embedding tables with dense neural-network operations, so available memory, sharding, network traffic, and software support matter alongside matrix throughput. TensorFlow remains part of Google’s TPU stack; XLA and JAX are also relevant framework/compiler paths. These are workload examples, not a claim that every recommendation or vision task benefits from a TPU. Google Cloud TPU workload guidance · Cloud TPU JAX/XLA stack
“Upcoming TPUv5” is also obsolete language. TPU v5e entered preview in 2023 and became generally available in November 2023. Trillium, or v6e, became generally available in December 2024. Google Cloud announced TPU7x, part of the Ironwood generation, as generally available on 31 March 2026. Google reports generation-to-generation performance, price-performance, and energy-efficiency comparisons for specified tests. Those numbers should be quoted with their model, baseline, precision, and vendor attribution. TPU v5e GA announcement · Cloud TPU release notes
Neural processing units: optimizing supported workloads at the edge
How they work and where they fit
An NPU is a processor or accelerator designed to run neural-network operations efficiently. The term covers a range of architectures, instructions, memory arrangements, and software interfaces. NPUs do not generally “replicate the computational efficiency of biological neural networks.” Many accelerate familiar operations such as matrix multiplication and convolution, and support sparse or quantized models. Neuromorphic chips, discussed later, are a separate design direction.
A mobile or PC NPU may be useful when a supported model can run locally at an acceptable quality, speed, and battery cost. Local execution can reduce network dependence and avoid sending some data to a remote service. It does not guarantee privacy, low latency, low power, or model compatibility: applications still depend on operating-system APIs, model formats, memory, thermal limits, and vendor runtimes.
Qualcomm’s Hexagon NPU is integrated into specific Snapdragon platforms. For example, the Snapdragon X Elite product page lists a 45 TOPS Hexagon NPU. That is a product specification at the vendor’s stated conditions, not an application benchmark or a direct comparison with an NPU from another vendor. Qualcomm Snapdragon X Elite specifications
Potential NPU use cases include image classification, object detection, speech processing, translation, camera effects, augmented-reality features, and on-device assistants. A translation workflow can transcribe speech, run translation, and synthesize audio locally when the application, language model, and runtime are supported. Mobile games may offload an eligible inference step to an NPU while leaving rendering to the GPU. Neither example guarantees a battery or latency improvement; measure the complete device and application. Some NPUs accelerate sparse or low-precision computation, but whether the chip benefits from a sparse model depends on its supported formats, kernels, and data layout. Autonomous systems, drones, industrial monitoring, and smart cameras may also use edge inference. Whether an NPU is a good fit depends on the model and the response the application needs. A deployed system must still account for sensor quality, failure modes, updates, connectivity, and safety controls.
Systems on a chip: compact integration
Integration and applications
A system-on-chip (SoC) places several components on one integrated circuit or package. Depending on the design, it may combine CPU cores, graphics, neural acceleration, image processing, memory controllers, and communications interfaces. Apple’s M1 and M2 are examples of SoCs that include CPU, GPU, and Neural Engine components; Intel’s Meteor Lake Core Ultra combined CPU, graphics, and an NPU in a chiplet-based package. Apple M1 announcement · Apple M2 announcement · Intel Meteor Lake and NPU overview
Integration can reduce board space and some transfers between separate components. It can also constrain cooling, memory capacity, upgrade paths, and sustained performance. “Smaller,” “lower-power,” and “lower-cost” are design goals that must be measured for a particular device and workload, not guaranteed consequences of putting components together.
Automotive systems illustrate why the whole product matters. The January 2025 article used Tesla’s FSD computer as an example of a system combining neural-network accelerators with CPU and GPU components. Tesla’s current customer-vehicle support documentation says FSD (Supervised) requires active driver supervision and does not make a vehicle autonomous. Tesla describes Robotaxi as a separate driverless ride service; that service claim does not change the scope of FSD (Supervised) in customer vehicles. A chip’s ability to process sensor data does not establish that a vehicle can safely navigate without a driver. Tesla AI Computer Installations · FSD (Supervised) · Robotaxi
Field-programmable gate arrays: adaptable hardware
An FPGA contains configurable logic blocks connected through programmable routing. Engineers configure those resources after manufacturing to implement a digital circuit. That makes an FPGA useful when a design needs low-level control, custom data paths, or field updates without committing to a new application-specific chip.
The tradeoff is development effort. The system must be described, synthesized, placed, routed, timed, tested, and integrated with its software and I/O. Performance and energy use depend on the particular bitstream, memory access, clock rate, board, and workload. An FPGA can implement a custom data path for inference, pre- and post-processing, or signal-processing tasks in telecommunications. Its reconfigurability is valuable, but does not make it inherently faster or more energy-efficient than a GPU or ASIC.
Microsoft’s Project Brainwave demonstrated FPGA-based deep-learning acceleration for Bing intelligent search and in Azure. That is a historical deployment example, not a current Azure service promise. Microsoft’s Azure NP-series FPGA virtual machines are scheduled to retire on 31 May 2027; this specific retirement should not be generalized to all FPGA use or every FPGA product. Check the service and region before relying on it. Microsoft Research: Project Brainwave and Bing · Azure NP-series retirement
Comparing the whole system

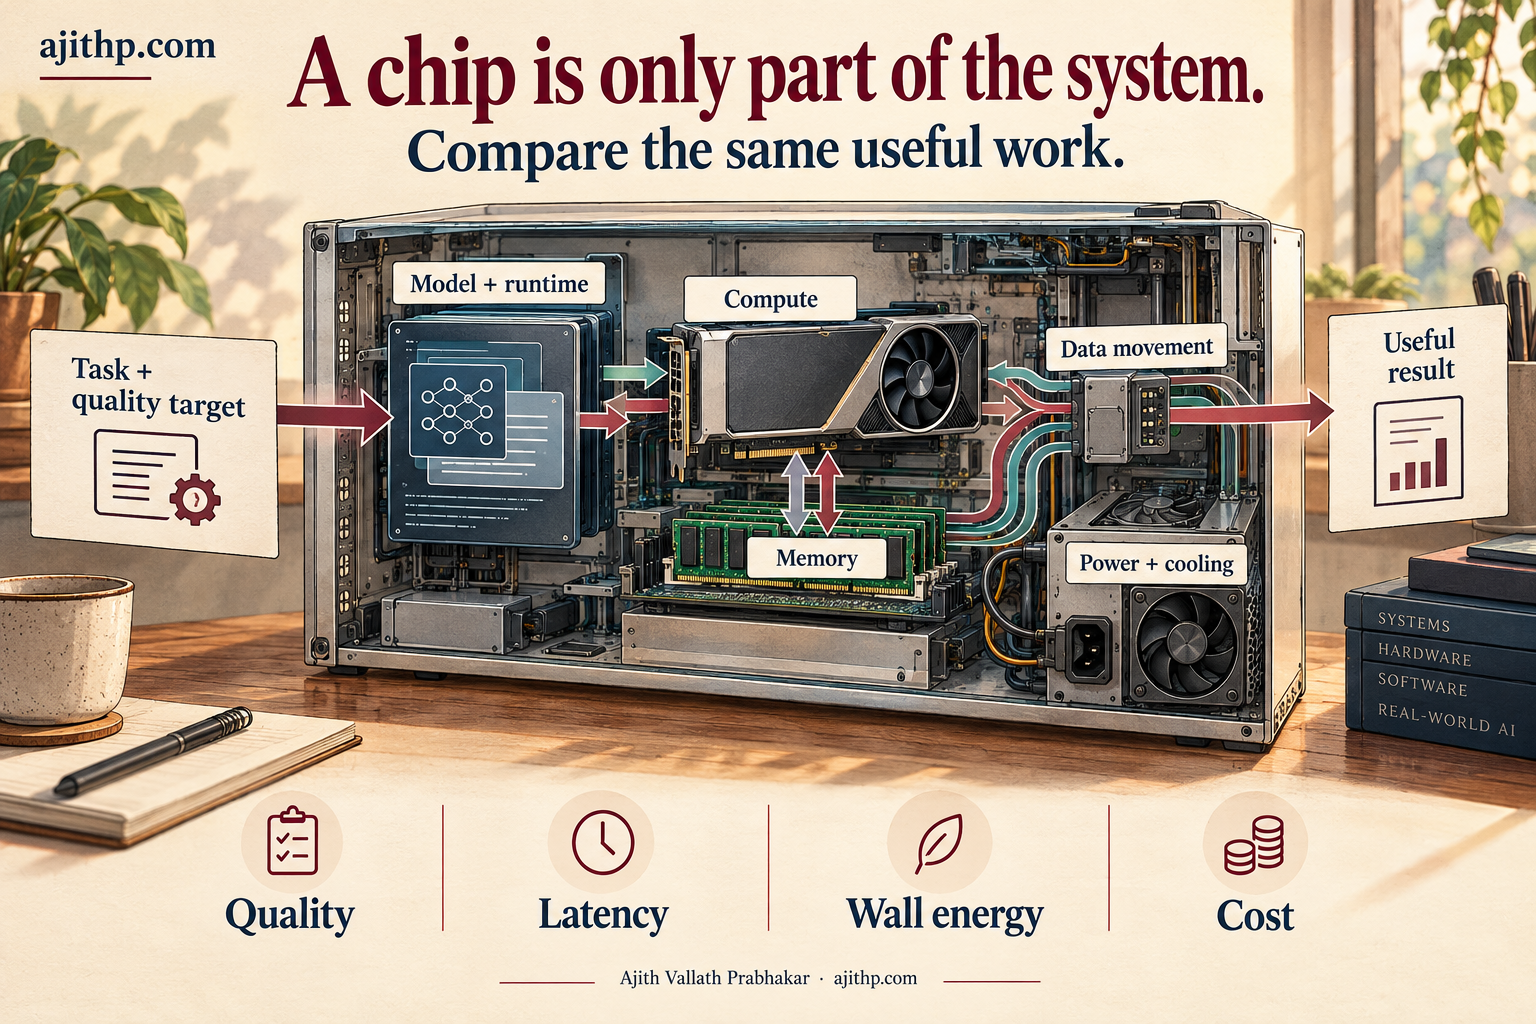
A chip-level result is useful only when the workload and measurement boundary are clear. For a GPU, TPU, or another accelerator, record throughput, time to first result, end-to-end latency, model fit, memory capacity and bandwidth, precision, batch and sequence length, software versions, utilization, measured wall power, and the full device configuration. Include output quality and the cost basis when the comparison is meant to guide a deployment.
The bottleneck changes by task. A model that does not fit in accelerator memory can be limited by capacity and communication. Small-batch inference can be dominated by latency and software overhead. Distributed training can spend time moving data between devices. At the edge, heat, battery, sensors, update paths, and intermittent connectivity constrain what can run. Vendor tests help explain a product when they disclose these conditions; they remain vendor tests. Independent comparisons matter when a broad performance or energy advantage is claimed.
Companies and dated product examples
The table covers 17 companies, with architecture, product and application examples from the January 2025 snapshot. Its final column adds later corporate or product context. These examples are not rankings. Application areas describe plausible or historically reported workloads, not proof that each vendor’s product is currently available or best suited to them.
Established vendors
| Company | Summary | Key innovations and dated examples | Application areas | October 2026 status and context |
|---|---|---|---|---|
| NVIDIA | Provides GPUs and AI software platforms. | CUDA software ecosystem; A100 and H100 Tensor Core GPUs; DGX systems; Hopper architecture; Omniverse. | High-performance computing; AI training and inference; data-center AI; gaming; simulation and graphics. | A100 and H100/Hopper are dated examples, not the latest generation. The 2022 H100/DGX announcements document their product launch and vendor specifications. “Leading” is omitted because no market metric or period was defined. Hopper / H100 · DGX H100 |
| Develops AI hardware and software, including custom tensor accelerators. | Tensor Processing Units (TPUs), including TPU v5e (a 2023 generation). | Deep learning; large-scale machine learning; cloud AI; recommendation and computer-vision workloads. | v5e was available in 2023; v6e/Trillium followed in 2024 and TPU7x/Ironwood reached GA in 2026. The date is attached to each generation rather than described as “upcoming.” v5e · release history | |
| Intel | Provides CPUs, AI accelerators, and graphics; Altera develops programmable-logic products, with Intel retaining a minority stake. | Stratix 10 (Altera FPGA); Gaudi accelerators; Loihi neuromorphic research chips; Meteor Lake client processor with integrated NPU/VPU. | AI training and inference; client and edge AI; programmable logic; neuromorphic research. | These are not one product class or maturity level. Stratix 10 is a dated FPGA family. Intel announced a 51% sale to Silver Lake in April 2025; the transaction closed on 15 September 2025, making Altera operationally independent while Intel retained 49%. Intel’s Core Ultra/Meteor Lake release described its first integrated client NPU; Gaudi is a deep-learning accelerator family; Loihi is part of Intel Labs’ neuromorphic research program. This ownership change makes current FPGA sourcing and company attribution distinct from the historical table. Intel’s April 2025 announcement · Altera transaction close · Stratix 10 · Gaudi 2 white paper · Meteor Lake · Loihi research |
| AMD | Provides CPUs and GPUs for computing, data-center, and accelerator workloads. | Instinct MI200 accelerators; Ryzen AI processors; heterogeneous computing platforms. | High-performance computing; AI training and inference; gaming; data-center computing. | MI200 is a 2021 generation and remains a documented product family. It should not stand in for AMD’s later accelerator generations. “Ryzen AI” refers to specific processor generations and NPU capability; identify the model before giving a TOPS figure. MI200 launch · MI350 |
| Qualcomm | Develops mobile and edge platforms with integrated AI processors. | Snapdragon SoCs with integrated NPUs; Hexagon AI processor. | Mobile AI; edge computing; on-device inference; 5G and wireless platforms. | Both names cover multiple generations. The X Elite, for example, lists a Hexagon NPU rated at 45 TOPS; this is a vendor specification and does not compare application performance across platforms. X Elite product page |
| Apple | Designs consumer devices with integrated CPU, GPU, and Neural Engine components. | Neural Engine; M1 and M2 M-series SoCs with integrated CPU and GPU (not A-series chips). | Mobile and consumer devices; on-device AI inference. | M1 and M2 remain historical examples of Apple silicon integration. Apple’s M-series releases specify each generation’s Neural Engine and measured claims; do not treat M1/M2 figures as current family specifications. The original table mislabeled M1 and M2 as A-series chips; this entry corrects the family name. M1 · M2 |
| Amazon | Develops custom AI accelerators and CPUs for AWS cloud workloads. | Trainium2 AI training accelerator (2024 generation). | Cloud AI; AI training and inference; energy and cost evaluation on named AWS configurations. | Trainium2 entered general availability in EC2 Trn2 instances in December 2024. Trainium3 later became available, so Trainium2 should be labeled as a dated generation. AWS’s price-performance and energy comparisons are vendor-reported for named EC2 configurations. Trainium2 GA · Trainium3 announcement |
| Microsoft | Develops cloud AI software and custom infrastructure accelerators. | Azure Maia AI accelerator; Azure Cobalt CPU. | Cloud AI; AI training and inference; data-center and platform services. | Microsoft announced Maia and Cobalt in 2023. Maia 200 is a later inference accelerator; Microsoft says it is deployed in US Central and gives performance specifications and comparisons that should remain attributed. Maia is Microsoft’s own infrastructure silicon, not a generally orderable standalone chip. Maia and Cobalt announcement · Maia 200 |
Smaller and specialized companies
| Company | Summary | Key innovations and dated examples | Application areas | October 2026 status and context |
|---|---|---|---|---|
| Graphcore | Developed the Intelligence Processing Unit (IPU) architecture; Graphcore joined SoftBank in 2024. | IPU architecture; Colossus MK2 GC200 IPU (historical product generation). | Parallel machine learning; graph-oriented and other irregular-data workloads; high-dimensional data analysis. | Graphcore was acquired by SoftBank in July 2024 and continued to operate under the Graphcore name as a wholly owned subsidiary. IPUs are a distinct product architecture; the ownership change does not prove any particular workload advantage. Acquisition announcement |
| SambaNova | Builds integrated AI systems using its reconfigurable dataflow architecture. | Reconfigurable Dataflow Architecture (RDA). | Large-scale model training and inference; enterprise AI systems; data analytics. | The company’s 2025 product material describes the SN40L RDU and SambaCloud, SambaStack, and SambaManaged offerings. Its efficiency and “award-winning” language is company positioning; a workload-specific comparison is needed before treating it as measured fact. SambaNova 2.0 · SN40L paper |
| SiMa.ai | Develops machine-learning system-on-chip products for edge AI. | MLSoC platform; Modalix MLSoC generation. | Edge inference; computer vision; machine learning on edge devices. | SiMa.ai is separate from ThinCI/Blaize. It announced its Modalix MLSoC in 2024 and reported production availability in August 2025. Its own efficiency and “Physical AI” positioning should be attributed to the company. Modalix engineering overview · Modalix in production · MLSoC specifications |
| Groq | Develops Language Processing Units (LPUs) and inference software; licensed inference technology non-exclusively to NVIDIA in 2025. | Tensor Streaming Processor (TSP); Language Processing Unit (LPU). | Large language model inference; low-latency serving; deterministic execution as a design objective. | Groq’s company announced in December 2025 that it licensed inference technology non-exclusively to NVIDIA; Groq said it would remain independent under Simon Edwards, while founder Jonathan Ross, president Sunny Madra, and other team members would join NVIDIA; GroqCloud would continue. The company later joined NVIDIA’s Cloud Partner program in 2026. This changes the business context but does not erase the origin of the LPU/TSP entry. License announcement · Cloud Partner announcement |
| Cerebras Systems | Develops wafer-scale AI processors and systems. | Wafer-Scale Engine 2 (WSE-2; historical generation). | Large-scale AI model training; high-performance computing. | WSE-2 is a historical generation. Cerebras introduced WSE-3 in 2024; in August 2026 it announced CS-4 using WSE-3 Turbo. All performance comparisons in those announcements are Cerebras claims and are specific to its chosen model and GPU baseline. WSE-3 announcement · CS-4 announcement |
| Mythic | Develops analog compute-in-memory processors for edge inference. | Analog compute engine; M1 product line. | Edge inference; sensor processing; power-constrained applications (performance and energy remain product-specific). | Mythic’s current product page presents M1 as an available evaluation product and reports vendor power and performance claims. Its site describes Mead as in development and Vanguard as planned for 2027; neither roadmap claim is an independently measured result. Mythic’s homepage says it acquired Videantis in January 2026. Its May 19, 2026 newsroom release is the public announcement date; the transaction closing date is not independently established here. Mythic announcement. M1 · Mead, in development · company update |
| Tenstorrent | Develops AI processors and systems for model training and inference. | Grayskull and Wormhole processor generations. | AI training and inference; model parallelism; graph-based machine-learning workloads. | Those names remain useful lineage, but Tenstorrent’s support page says Grayskull software support is discontinued while Wormhole hardware remains supported and available; Blackhole is a later generation. “Energy efficiency” is not a universal result without a matched benchmark. Tenstorrent support and product status · cards and specifications |
| Blaize (formerly ThinCI) | ThinCI changed its legal name to Blaize in 2019; the original entry refers to the company’s earlier name and product lineage. | Graph Streaming Processor (GSP) architecture, associated with ThinCI’s historical product lineage and later Blaize company. | Edge inference; computer vision; real-time processing as an application target. | ThinCI, founded in 2010, changed its legal name to Blaize in 2019; this was a rename, not an acquisition. Blaize completed its business combination with BurTech and became publicly traded in January 2025. The row preserves the original company/product lineage and does not imply that “ThinCI” remains a separate current company or that the GSP product is currently available under that old name. SEC filing on name change · FY2024 results, reported March 2025 · Blaize company overview |
| Koniku | Develops biological-neuron-based sensing technology and the Koniku Kore concept. | Koniku Kore bio-sensing/olfaction concept; not characterized here as a conventional silicon NPU. | Bio-sensing and olfactory/sensory processing; not a verified general-purpose neuromorphic-computing use case. | This was described as a bio-sensing and olfactory direction, not a conventional silicon NPU or a general-purpose neuromorphic processor. Koniku’s product page has described Kore as “coming soon”; that statement does not establish commercial availability in October 2026. The row is retained as an example of a different research/product direction, not as a verified shipping chip. Koniku Kore page · Koniku technology overview |
The future trajectory of AI hardware
Edge computing: inference near the data
Edge computing places some processing near the device or data source. It can reduce the need to transmit every input to a cloud service and may help when connectivity is unreliable or latency matters. It also brings constraints: smaller memory, limited cooling, battery capacity, device cost, model update paths, and the software that must run on the target.
NVIDIA’s Jetson Thor is a robotics-focused edge computer for physical-AI and humanoid-robotics systems. The January 2025 article described it as planned for early 2025; it became generally available on 25 August 2025. NVIDIA reports up to 7.5 times the AI compute and 3.5 times the energy efficiency of Jetson AGX Orin. Those are NVIDIA’s vendor comparisons; they should not be read as a universal result for every model, power mode, or application. NVIDIA Jetson Thor availability announcement
An edge accelerator’s efficiency claim needs a comparison someone else can examine: the exact devices, model, precision, workload, output quality, and measurement boundary. A vendor’s result and an independently reproduced result are different evidence. Edge designs may reduce some communication and infrastructure demands; they still consume power and may shift where computation and storage occur.
Sustainability: measure the whole system
AI hardware has an energy footprint. The International Energy Agency’s 2025 Energy and AI report models how AI and data-center demand could affect electricity use and supply. That kind of system analysis is more useful than comparing a chip’s rated power in isolation. A practical evaluation should include accelerators, CPUs, memory, interconnects, storage, cooling, power conversion, utilization, and the amount of useful work produced. IEA, Energy and AI
Google’s and Microsoft’s electricity commitments measure different things. Google’s goal is to operate on 24/7 carbon-free energy by 2030. Microsoft’s goal is to become carbon negative by 2030. Microsoft also made a separate commitment to match 100 percent of its electricity consumption, every hour, with zero-carbon energy purchases by 2030; Microsoft calls this its 100/100/0 commitment and describes a broader 100/100/0 vision for the global grid. In February 2026, Microsoft reported matching its annual global electricity consumption with renewable-energy purchases for 2025. Annual matching, the hourly purchasing commitment, and carbon-negative operations describe different measures. A company-reported annual milestone does not establish that its hourly or carbon-negative goals have been achieved. Google 24/7 carbon-free energy goal · Microsoft’s 100/100/0 commitment · Microsoft 2026 sustainability update
Liquid cooling and immersion cooling can help manage heat in dense systems, but cooling equipment also uses resources and has to be evaluated at facility scale. A claim of lower operational energy needs a defined comparison, including power usage effectiveness or another stated system metric, climate, compute load, water use where relevant, and the baseline system. “More efficient cooling” alone does not establish lower total environmental impact.
Quantum computing: a separate research path
Quantum processors are not another form of GPU, TPU, or NPU. They use quantum states and gates for specific classes of computation, while conventional systems remain responsible for control and many surrounding tasks. The useful question is not whether a quantum chip is generally faster, but whether a particular algorithm has a demonstrated advantage for a practical problem at the required scale and error rate.
Google’s Willow announcement first reported below-threshold error correction in its surface-code experiment: as the code distance increased, the logical error rate decreased. It also compared a random-circuit-sampling computation completed in under five minutes with an estimated classical runtime of 10 septillion years. The task was random circuit sampling (RCS), a benchmark used to test quantum systems. Google states that RCS has no known real-world application. The result should therefore not be presented as an AI benchmark, a general computing speedup, or evidence that Willow accelerates machine learning. The classical runtime comparison also depends on modeling assumptions that Google describes in its post. Google’s Willow announcement and RCS caveats
Photonic quantum chips belong to this quantum section. Ephos describes a glass-based photonic quantum processor program, while Xanadu announced Aurora, a photonic quantum-computing system built from 35 photonic chips and fiber links. These are quantum systems and roadmaps, not classical optical AI accelerators. Claims about room-temperature components or systems must identify which components operate at that temperature; this does not establish that every full quantum-computing system needs no cooling or has a general AI use. European Commission project description for Ephos · Xanadu Aurora announcement
Neuromorphic and photonic chips: distinct architectures and evidence
These fields are active, but the products, prototypes, and experiments do not all solve the same problem. Their results should be compared with conventional accelerators only when the model, task, precision, system boundary, and output quality match.
Neuromorphic computing: event-driven systems
Neuromorphic systems take design ideas from neural activity, often including spiking neural networks, event-driven computation, sparse connectivity, or close coupling between memory and processing. Some systems process inputs only when events occur, which can help when the data and task are naturally sparse. This does not mean every neuromorphic processor learns continuously, adapts on the fly, or consumes less energy than a GPU on arbitrary workloads.
Intel describes Loihi 2 as a research processor and its neuromorphic work as a research effort involving its Intel Neuromorphic Research Community. Intel reports efficiency gains on selected small-scale edge workloads. Those results are evidence about the studied tasks and system, not a general product comparison. IBM’s TrueNorth was a separate 2014 research chip with event-driven cores; its reported energy figures came from specified vision and neural-simulation tasks. Neither chip should be presented as a current commercial accelerator without evidence of availability. Intel Loihi and neuromorphic research · IBM TrueNorth paper
SynSense develops neuromorphic products including Speck for event-driven vision and Xylo for bioelectrical signal processing. The company lists product specifications and application kits, including low-power sensing configurations. Those remain vendor specifications and product examples; actual power and accuracy depend on the sensor, model, event rate, and system configuration. SynSense Speck · SynSense Xylo
BrainChip’s Akida materials describe an event-based neural processor and state capacity figures of up to 1.2 million neurons and 10 billion synapses. Those are vendor-defined architecture figures. They do not specify how many useful model parameters or application tasks fit, nor do they establish a measured power reduction against a named alternative. Incremental learning and low-power operation should be described for a supported product configuration and task, not generalized to all neuromorphic systems. BrainChip Akida announcement · BrainChip developer documentation
Potential applications include event-camera perception, robotics, signal processing, and low-power sensor systems. Healthcare examples need particular care. A low-power research prototype that detects a signal is not evidence of a clinically validated diagnostic device. Any medical claim should identify the study, population, validation method, and regulatory status.
Photonic chips: distinguish computation from communication

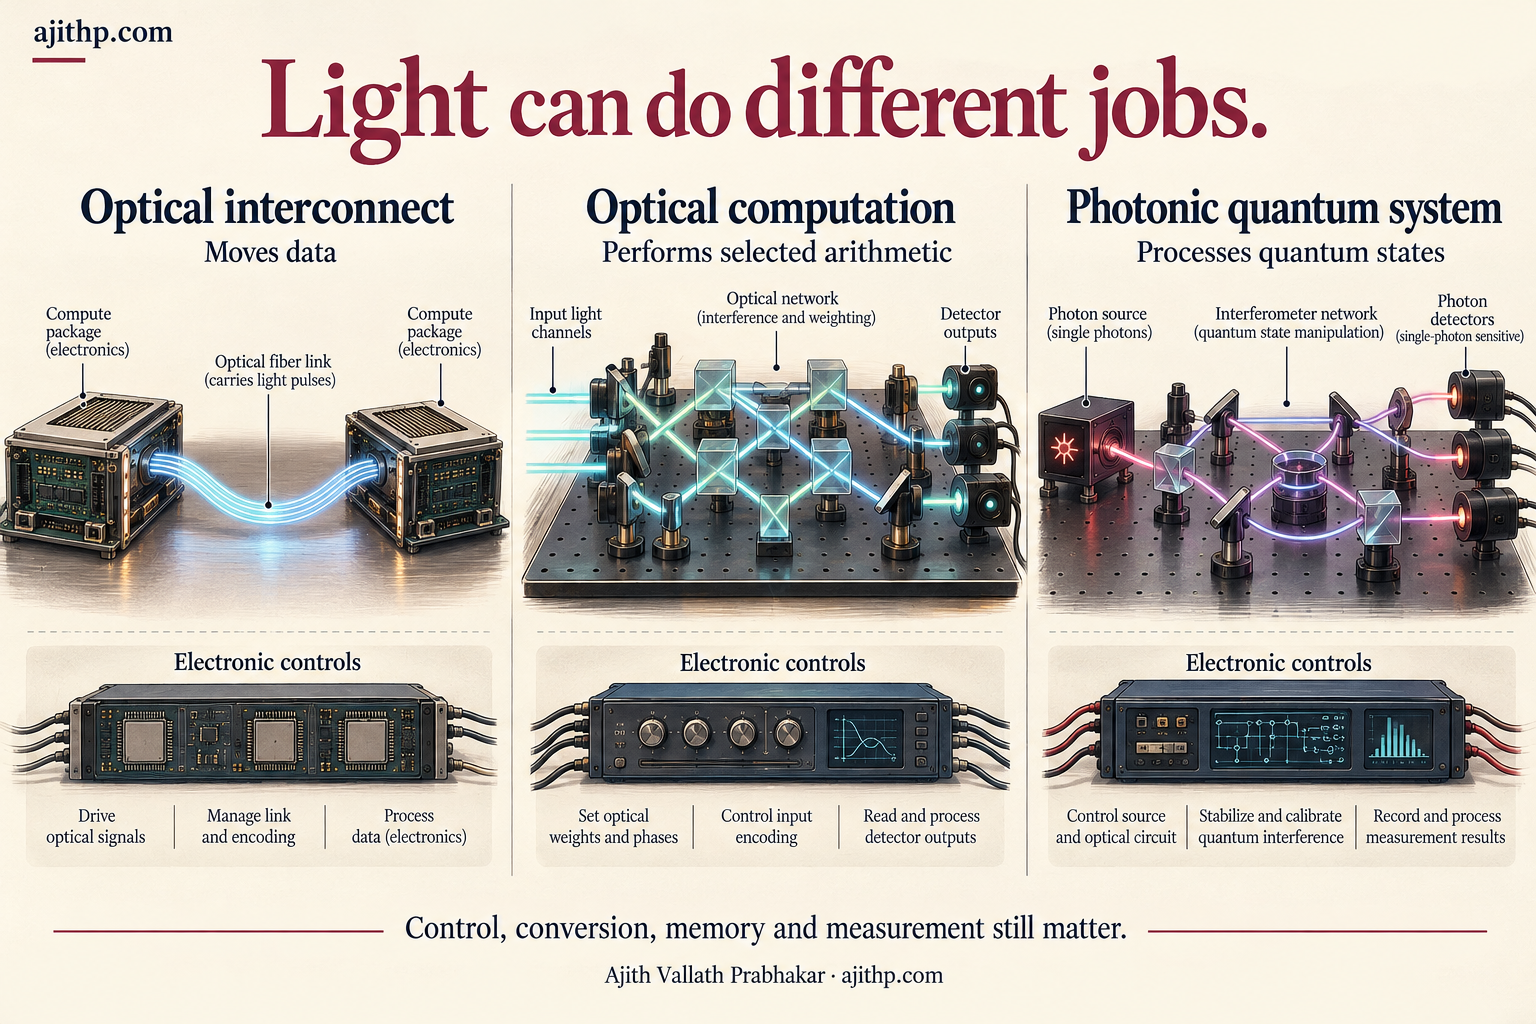
Photonic systems use light to transmit signals, and some experimental systems also use optical elements to perform computations. The phrase “light-speed AI” is too broad: optical propagation is fast, but a system’s end-to-end speed also depends on modulation, conversion, detectors, memory, electronic control, data movement, and the task’s precision and scale.
A 2024 Nature paper demonstrated fully forward-mode training in free-space and integrated optical neural networks. It reports experiments for defined network sizes and tasks, including image classification and imaging through scattering media. This is important experimental work. It is not a demonstration that a commercial photonic processor can replace a GPU for general LLM training or that optical systems universally use less total energy. Xue et al., “Fully forward mode training for optical neural networks”
Other products use photonics primarily to connect chips. Lightmatter’s Passage is a photonic interconnect platform for moving data between compute components. The company also describes Envise as a photonic AI compute platform and points to its April 2025 Nature publication. These are separate product and research lines: Passage moves data between compute components, while Envise is presented for optical matrix operations. The company description and paper do not establish general-purpose replacement of GPUs or broad commercial availability. Lightmatter Envise · Lightmatter’s April 2025 account. The distinction matters: faster or more efficient communication may help a system, but it is not the same as executing a neural network’s arithmetic optically. Lightmatter Passage · Passage L20 roadmap
Claims about photonic advantages depend on what is included. A fair system comparison accounts for laser sources, optical/electrical conversion, modulators, detection, memory, control, packaging, precision, manufacturing, and software. Optical communication may reduce a particular interconnect bottleneck; it does not automatically remove heat, energy, cost, or scaling constraints.
Conclusion
AI hardware spans general-purpose processors, workload-specific accelerators, configurable logic, integrated SoCs, and research architectures that change how computation or communication is represented. No single category wins across every model and deployment. The hardware that works best is the one whose memory, compute, software, latency, power, and cost fit the real workload.
The history also cautions against reading product announcements as a settled performance order. TPU and GPU results depend on named generations and tests. A model’s hardware may remain undisclosed, as with GPT-4. Edge, neuromorphic, photonic, and quantum examples require distinctions between shipping product, roadmap, research prototype, and task-specific result. That discipline makes comparison more useful and keeps promising ideas in view without claiming evidence they have not yet produced.
Primary sources and further reading
- AlexNet, NeurIPS 2012
- Google TPU paper, ISCA 2017
- Scalable MatMul-free Language Modeling, 2024
- OpenAI GPT-4 Technical Report
- PaLM paper and PaLM 2 Technical Report
- Google Cloud TPU release notes
- IEA, Energy and AI
- Intel neuromorphic research
- Nature, optical neural-network training
- Google Willow and random circuit sampling
Discover more from Ajith Vallath Prabhakar
Subscribe to get the latest posts sent to your email.