Quick brief
Useful AI memory preserves why a record matters, whether it still applies and who may use it, rather than simply recalling more history. Design its write, retrieval, correction and forgetting paths together, then test continuity against changed facts, revoked access and unsupported inferences.
Listen to the AI-generated overview · about 2 minutes
Read the audio transcript
Timestamps are approximate.
0:00
This is an AI-generated overview of the revised article on persistent AI memory. The briefing example is fictional.
0:08
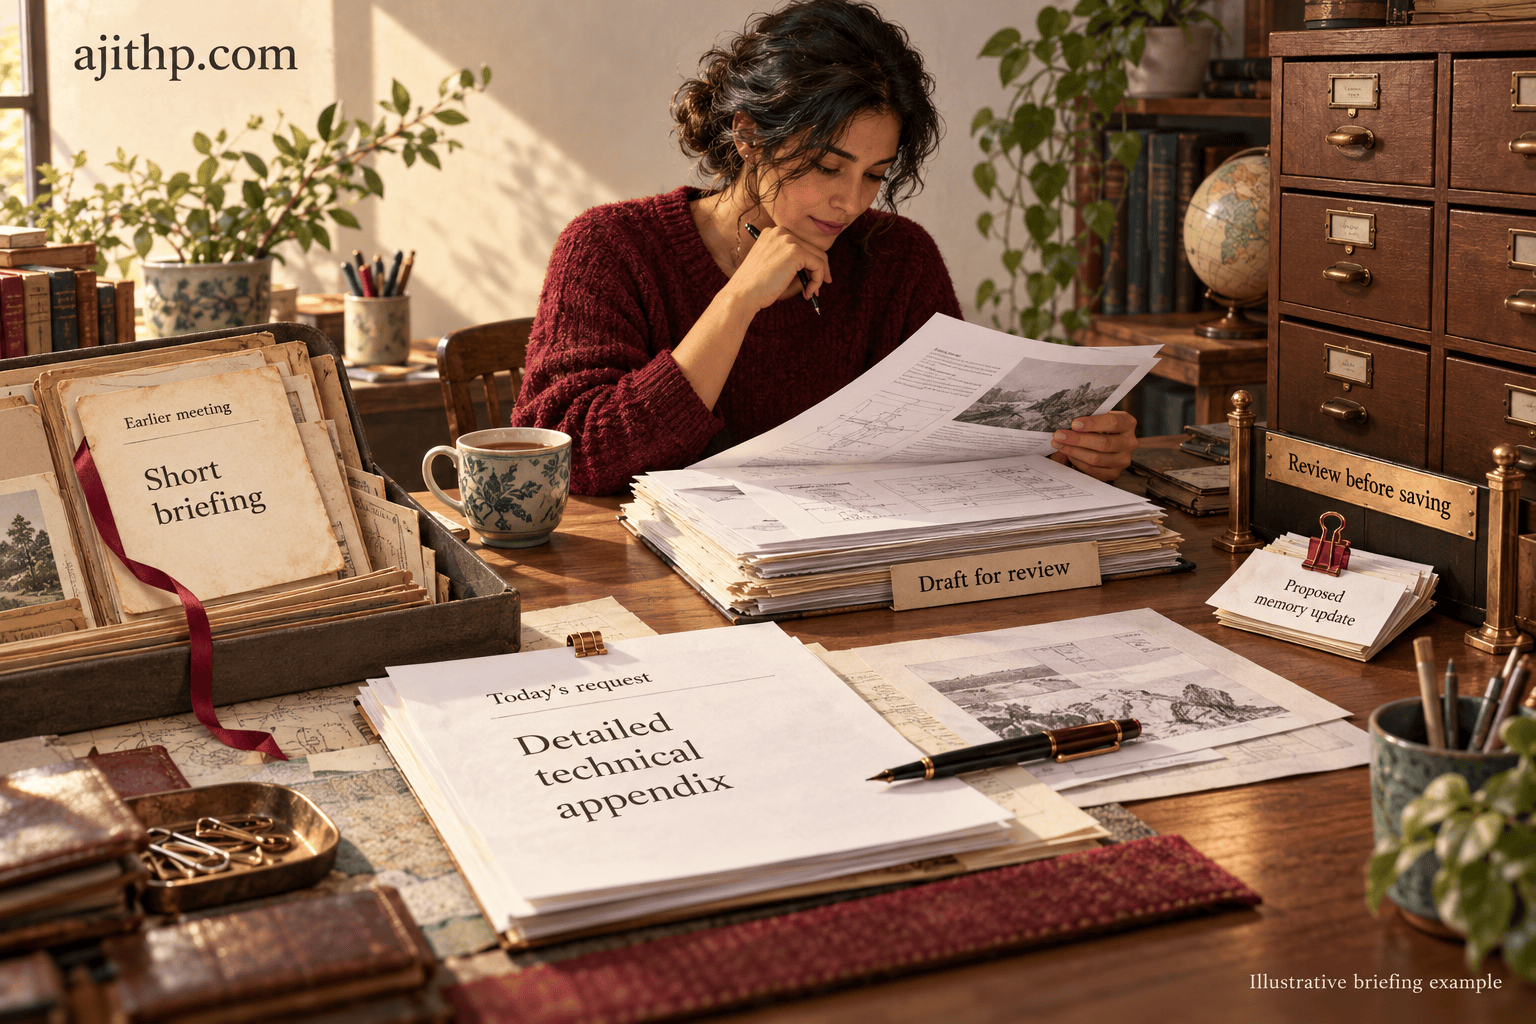
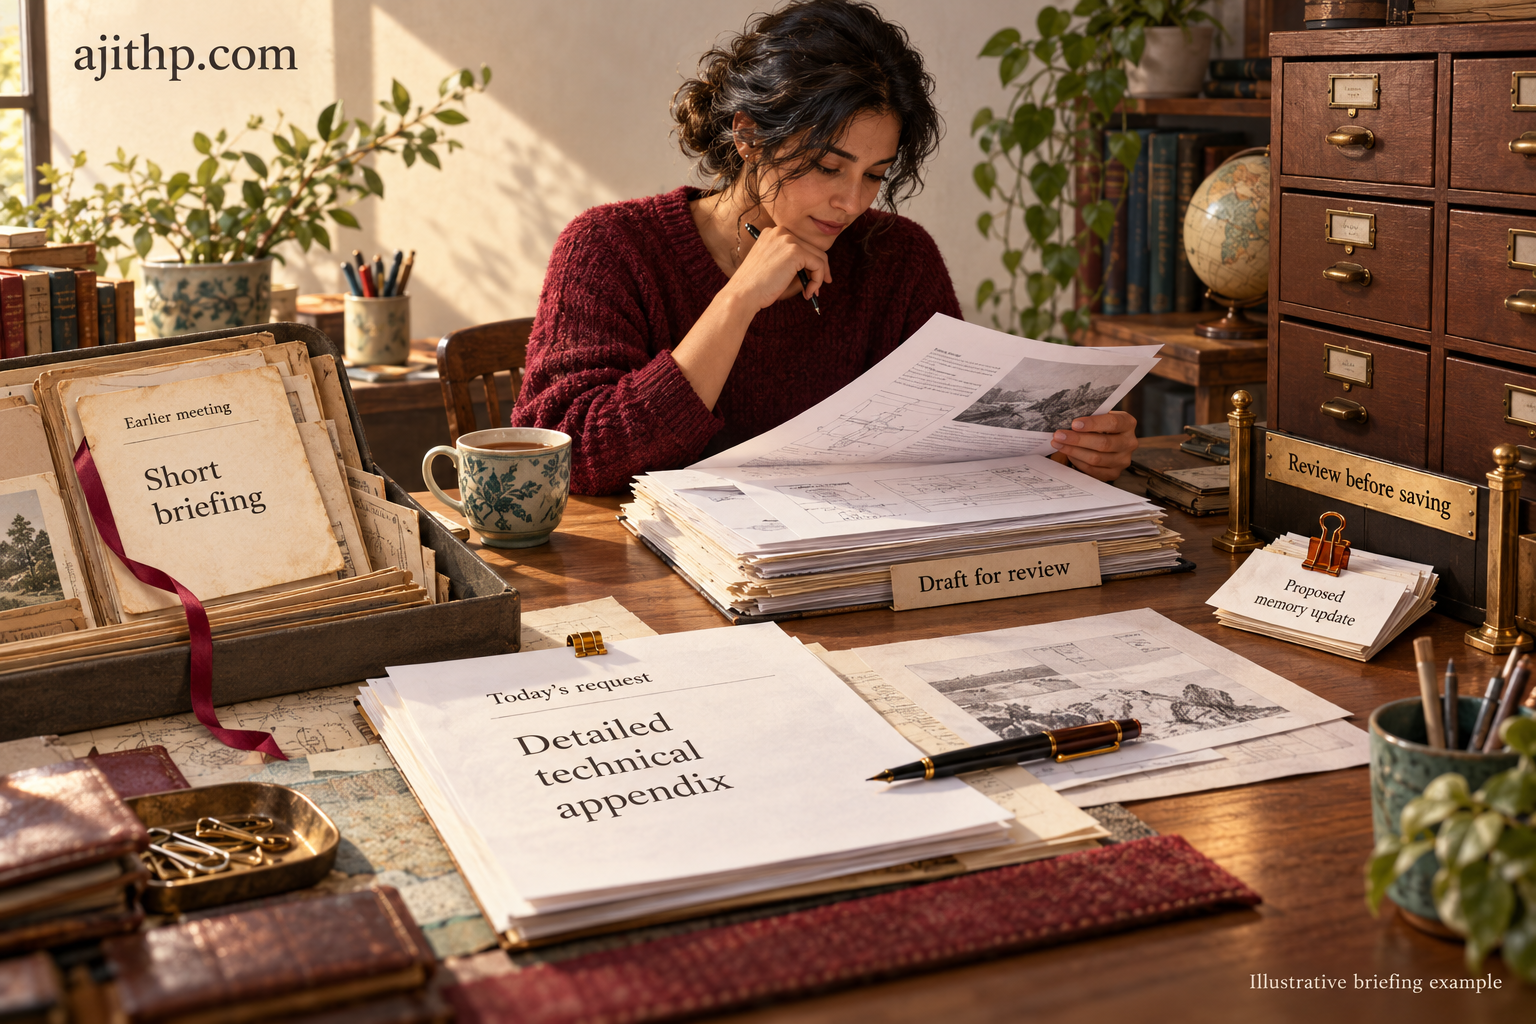
An assistant remembers that a colleague wanted a short note before one meeting. Months later, it applies that preference to another project, even though the person now wants a detailed technical appendix. The remembered statement may be accurate. Its use is wrong.
0:25
Useful memory needs more than recall. Keep the source, the person or project, when the information applies, and whether it was stated or inferred. A temporary request should not quietly become a permanent description of someone.
0:40
Reading a record is different from committing a persistent update. A model can propose a change that validation rejects, or storage can fail after a reply is generated. Saying “I will remember that” does not prove the record was saved. Updates need an authorized write path and a confirmed durable outcome.
0:59
If two agents propose incompatible preferences, neither should overwrite a shared profile simply because it finishes last. Keep a disputed merge pending for explicit human approval. Remembered context may help prepare a message, but sending still requires the appropriate separate authorization.
1:17
Correction and forgetting also have different meanings. Excluding a record from retrieval does not demonstrate deletion from summaries, caches, backups or model parameters. Check the documented scope and the paths through which it might return.
1:32
The practical test is whether the assistant notices changed circumstances, preserves uncertainty and supports today’s task. Memory should help someone resume their work without trapping them in an old version of it.
Full analysis
Originally published June 30, 2025. Revised October 18, 2026.
An assistant remembers that a colleague preferred a short briefing before a meeting. Months later, it applies that preference to a different project, retrieves an old decision, and drafts a reply as though the decision still stands. The recall may be accurate while the advice is wrong. A useful memory system needs to preserve the circumstances that made an earlier fact relevant.
I want a personal assistant to help me carry relationships, commitments, and knowledge across the interruptions of a working day. Repeating the same background at every interaction gets in the way. But continuity also means recognizing when a person changes their mind, a project ends, or access to a document is withdrawn.
The examples here are illustrative design cases. Research systems provide useful ideas, but their experiments do not establish that an assistant understands a person completely or can safely act with all of that person’s authority.
Separate the forms of memory
The current context is the information available to a model during an invocation. An application can also retain conversation history, summaries, structured records, and external documents across sessions. It decides what to bring into the next context. Keeping a record does not necessarily update the model’s parameters.
Model adaptation is a different mechanism. Training can change parameters using personal or organizational material, with different costs and implications for correction, deletion, and evaluation. These approaches can coexist. A long context window, a searchable history, and a personalized model are not interchangeable capabilities.
For the briefing example, I would first want the assistant to distinguish an explicit current preference from a one-off request or an inference. The following table is a practical design lens, not a universal memory taxonomy.
| Representation | Useful role | Question to test |
|---|---|---|
| Current context | Holds material selected for the immediate task. | What relevant information was omitted or truncated? |
| Source record | Preserves an authorized conversation, document, or event. | Can its origin, date, and access conditions be checked? |
| Summary or structured memory | Makes selected facts, relationships, and preferences easier to reuse. | Has compression removed a qualification or turned an inference into a fact? |
| Search index or relationship graph | Helps locate records and connections. | Does retrieval preserve identity, permissions, and temporal context? |
| Adapted model parameters | Can encode learned patterns from training material. | How will a changed fact be corrected and the behavior re-evaluated? |
Similarity search can find related passages, but similarity alone does not establish that a record is current or applicable. A graph can represent a relationship without proving that it is correct. Both need source evidence and rules for use.
An application can persist records while the model invocation itself remains stateless. Conversely, a long-running conversation can contain extensive context without offering durable, editable memory across sessions. The useful questions are what survives, how it is selected and what can change it. Calling memory “native” does not answer those questions.
The RAM-and-disk analogy is helpful only to a point. External storage can outlive a session, but a model still receives a finite selected context, and stored material may be omitted or misinterpreted. Persistence is a property of the surrounding storage and update design as well as any learned representation; it is not a guarantee of complete understanding.
Read Second Me as a specific research design
AI-native Memory 2.0: Second Me, by Jiale Wei and colleagues, is a March 2025 paper. Its Large Personal Model (LPM) design distinguishes raw data, natural-language memory, and parameter-based representations. Those layers describe the authors’ design, rather than a universal standard.
The paper examines memory questions, context enhancement, and context critique. Its authors acknowledge limited real-world feedback, evaluation length bias, and imprecise scoring. Those qualifications limit what its results establish.
In the authors’ terminology, LPM means Large Personal Model. L0 supplies raw records; L1 holds natural-language abstractions; L2 represents learned memory through parameters. Their hybrid design connects those layers rather than requiring every personal fact to be learned directly into weights. Parameter adaptation and retrieval remain different mechanisms even when the system uses both.
The proposed context-provider role is also worth separating from execution. Enriching a request with relevant personal information or critiquing an external response can help a user. It does not establish permission to disclose every remembered detail or make a commitment on that user’s behalf. Those are application decisions beyond a research score.
I would evaluate any such system through its behavior on relevant tasks, including failures. Local deployment still needs checks on the actual configuration and data flows.
Compare mechanisms before comparing products
MemGPT: Towards LLMs as Operating Systems takes an operating-system-inspired approach to managing a finite context and external memory through function calls. Its document-analysis and multi-session conversation experiments demonstrate particular retrieval and continuity tasks. They do not turn a finite model context into unlimited simultaneous attention or establish that every remembered statement is true.
LongMem, Augmenting Language Models with Long-Term Memory, is a separate 2023 research design with a frozen backbone memory encoder and an adaptive retriever/reader side-network. It is not the same mechanism as storing an editable personal preference. Its long-context research results should be interpreted within the paper’s tasks and setup.
When assessing a product, ask what persists, where it is stored, how it enters a response, and what the user can inspect or change. A product feature called memory may combine several mechanisms. Check the current edition, settings, model connections, retention, and export behavior instead of inferring them from the name of its base model.
For the briefing assistant, the useful comparison is whether a corrected preference is used next time and whether the old record remains distinguishable. A larger advertised context or a more personal tone cannot answer that question.
Compressive Transformers, first posted in 2019, investigate compressed past activations for longer-range sequence modeling. That is another mechanism again: compressed model state is different from an editable relationship record or a revocable source reference. It is useful to compare these designs without grouping them all under a promise of lifelong personal recall.
Inspect the product layer, not just the base model
Current product documentation illustrates several ways to reuse context. The following descriptions were checked for this revision; availability and behavior can differ by plan, region, rollout and organizational settings. They are not tests of the accounts or products in this article.
| Product documentation | Documented distinction | What a selection trial should establish |
|---|---|---|
| Memory in ChatGPT | Personalization can use several sources; a memory summary is not an exhaustive inventory | Which sources the intended account uses, what correction changes and which underlying records remain |
| Claude chat search and memory | Chat search, topic-based memory and project controls are application features; periodic memory synthesis belongs to the legacy experience | The applicable current or legacy experience, project/account boundaries and propagation of changes |
| Microsoft Copilot Memory | Saved memories become response context; turning saving off does not itself delete existing memories | Actual tenant/user controls, remembered records and the separate chat-history behavior |
| Google's notebook source guide | A notebook organizes sources for a project; the guide describes independent notebooks | Which source set grounds a response, rather than assuming a universal personal-memory store |
These features should not be attributed automatically to every model carrying the vendor’s name. A product can maintain a summary in application storage without retraining its base model for each user. A source-grounded notebook can preserve project material without learning a general behavioral profile. Test the promised capability at the layer where it is actually implemented.
Inspect correction, disabling, deletion and source removal separately. For example, OpenAI’s current documentation distinguishes changing personalization behavior from deleting underlying sources. The practical lesson is broader than one product: the visible summary and the records that can regenerate it may have different lifecycles. Read the current controls and verify the intended account’s behavior rather than inferring it from an old release announcement.
Build retrieval around identity, scope and source evidence
A memory retrieval path needs more than a similarity query. It should establish the requesting identity and task scope, locate candidate records, check their current eligibility, rank the relevant evidence and assemble a bounded context. Where access can change between those steps, the design needs an appropriate recheck before disclosure or action.
Vector search is useful for finding material expressed in different words. It may return a briefing note when the query asks about meeting preparation. Exact identifiers, filters and keyword search can be more reliable for a case number or a named policy revision. A hybrid retrieval design can use both. The index should retain a route to the authoritative record rather than making a vector the only surviving evidence.
A vector index and a database are also different components. FAISS is a similarity-search library, not by itself a complete memory service with identity, retention, transactions and user controls. Whatever storage or index is selected, those responsibilities still need an implementation and tests.
A relationship graph can represent people, projects, decisions and supporting records. Give entities stable identifiers so two people with the same name do not become one person through a string match. Attach source, time and uncertainty to an edge as well as to a node. “Recommended by” and “approved by” are different relationships, and neither should be inferred merely because a name appeared near a decision.
Graph traversal can expose useful connections, but a represented causal relationship is still a claim requiring evidence. A chain of inferred edges does not become a verified explanation because it can be drawn neatly. Access rules must cover derived relationships too: a graph can reveal restricted information through a connection even when the underlying document is withheld.
Keep working memory bounded and task-specific
Within a task, the assistant may need a scratchpad containing the open question, retrieved references, proposed steps and unresolved conflicts. That working state can help it resume after an interruption. It should not automatically become a permanent personal profile or an approved procedure for future work.
Define a promotion rule for moving something from working state to durable memory. An explicit recurring preference may be a candidate; a speculative explanation produced while solving a problem should remain provisional or be discarded. The application should preserve the distinction between what the user said, what a source states and what the model inferred.
Bound the material brought into the next context. More history can crowd out the current request or reintroduce irrelevant instructions. Measure whether retrieval improves the intended task and whether important evidence is omitted when the budget is exhausted. A useful system can retain a large archive while selecting very little for a particular answer.
Treat writes as a controlled pipeline
A conversation can contain a standing preference, a temporary request, a quote from someone else or a correction. Before storing a durable memory, classify what the candidate record represents and whether retention is appropriate. Preserve a reference to the input so an inferred preference can later be questioned.
Use stable record and source identifiers, an entity or project scope, the time the information applies, the time it was observed and a status such as provisional, current or superseded. Those are proposed design fields, not a universal standard. They give the update path enough information to avoid treating every new sentence as a global replacement.
Repeated ingestion should not create independent confirmation. If the same note arrives through an email export and a document archive, it may be two copies of one source. Deduplicate where the system can establish that relationship, and preserve uncertainty when it cannot. Frequency alone is weak evidence of truth when the assistant may be reading its own earlier summary.
Concurrent writers need an update policy. Two agents can derive incompatible preferences from different projects; neither should silently overwrite a shared profile just because it finishes last. Append findings, check revisions and assign ownership of material state changes. A proposed merge can remain pending until a person resolves it.
Record successful, rejected and failed updates with enough evidence to investigate them. A model can propose a write while validation rejects it, or storage can fail after generation succeeds. The application should report the durable outcome accurately. A sentence saying “I’ll remember that” is not evidence that the intended record was committed.
Keep the source, time, and uncertainty attached
A durable memory should retain enough context to evaluate its use. For a meeting preference, that could include who stated it, when it applied, whether it was explicit or inferred, and a restricted reference to the source. “Prefers a short briefing for this meeting” should not quietly become “always wants brief answers.”
Corrections need a visible path. If the person later asks for a detailed technical appendix, the assistant should be able to preserve that new request without erasing the history or applying it everywhere. Contradictory records may need a question or a scoped interpretation rather than a confident merge.
Relationships deserve the same care. Two people can share a name, change roles, or have different relationships across projects. A discussion of a colleague’s suggestion is not evidence that the colleague approved an action. An inferred relationship should not acquire the authority of a verified record through repeated summarization.
Avoid letting an assistant’s own earlier answer become independent confirmation of itself. A generated summary can be useful working material, but it should remain distinguishable from the underlying source. Test whether a factual correction reaches derived summaries, search results, caches, and later responses, rather than checking only the visible profile page.
The date a statement applies and the date the system learned it can differ. A person may report on Friday that a role changed on Monday. An answer about the current role needs the applicable date; an investigation of Wednesday’s response also needs to know what information was available then. Storing only an ingestion timestamp cannot answer both questions.
Do not assume the newest observation wins in every case. A new message may quote an old decision, or a personal preference may apply only to one project. Preserve supersession explicitly where a correction is authoritative, and keep genuine conflicts visible. The assistant can ask which interpretation applies instead of inventing a consistent biography.
A small executable eligibility example
The following standard-library Python example checks scope, source eligibility, supersession and a validity interval before returning candidate records. It requires timezone-aware timestamps, normalizes them to UTC before comparison and uses an exclusive end time. It does not perform retrieval ranking, authentication, durable writes or erasure; the readable-source and deleted-source sets must come from the application’s current authoritative state.
from dataclasses import dataclass
from datetime import datetime, timezone
from typing import Optional


def require_aware(value):
    if value.tzinfo is None or value.utcoffset() is None:
        raise ValueError("Use a timezone-aware timestamp")


@dataclass(frozen=True)
class Memory:
    record_id: str
    source_id: str
    scope: str
    content: str
    valid_from: datetime
    valid_until: Optional[datetime] = None
    superseded: bool = False

    def __post_init__(self):
        require_aware(self.valid_from)
        object.__setattr__(self, "valid_from", self.valid_from.astimezone(timezone.utc))
        if self.valid_until is not None:
            require_aware(self.valid_until)
            object.__setattr__(self, "valid_until", self.valid_until.astimezone(timezone.utc))
            if self.valid_until <= self.valid_from:
                raise ValueError("Validity interval must be positive")


def eligible_memories(records, scope, at, readable_sources, deleted_sources):
    require_aware(at)
    at = at.astimezone(timezone.utc)
    return [
        item for item in records
        if item.scope == scope
        and item.source_id in readable_sources
        and item.source_id not in deleted_sources
        and not item.superseded
        and item.valid_from <= at
        and (item.valid_until is None or at < item.valid_until)
    ]
For a temporary meeting preference valid from June 1 until June 8, a query on June 8 excludes it. Revoking its source removes it from the readable set; marking the source deleted also excludes a re-ingested candidate using the same source identity. Two eligible but contradictory records remain two records, leaving conflict resolution to a separate step.
The example was executed with synthetic cases for those boundaries, including repeated local times when clocks move back. It does not reconstruct historical knowledge from observation times, identify duplicate sources under different IDs or prevent a race after this check. A real service needs validated inputs, current permission checks at the relevant boundary, durable revision handling and tests of every disclosure path.
Compact memory without erasing its qualifications
Summaries help fit an archive into a limited context, but they change the representation. “Asked for a short pre-meeting note this Tuesday” can become “prefers short notes,” losing the time and purpose. Make compaction preserve the material scope, uncertainty and source references, and keep a route to the original evidence where retention permits it.
Treat a summary as a derived record with its own version and dependencies. When a source changes or access is revoked, identify the summaries, graph edges, caches and indexes that used it. Rebuilding the visible summary alone can leave an older derived record retrievable elsewhere.
Hierarchical summarization can reduce what must be read at once, while approximate search can reduce retrieval work. Both can omit detail that matters to a particular query. Test exception-heavy questions and compare the selected context with the source. A longer archive does not justify claiming that the assistant can attend to every record simultaneously.
Compression and verification also have operating costs. Count write-time extraction, embedding, summarization, index updates and later refreshes, as well as retrieval and generation. Decide what happens if compaction fails: retain the previous usable version, expose the gap and avoid presenting a partially updated profile as complete.
Treat remembered content as evidence, not permission
A saved email can contain an instruction to send a document somewhere. Storing that email does not make the instruction authorized. The same applies to an instruction hidden in a retrieved page or added to a long-lived summary. Persistence can make an untrusted instruction available repeatedly; it does not improve its authority.
Check access when information is used. A person who once had access to a project may no longer have it. A summary created from restricted material can reveal the same information as the original document. Test the derived records and caches as well as the source repository when a role changes or access is revoked.
An assistant can use a remembered communication preference to prepare a draft while still needing a separate authorization to send it. Identity, recipient, content, and the applicable action policy belong at execution. Familiarity with a person should not silently expand what the system may do for them.
This distinction also shapes my Maya vision: a connected personal OS that brings useful knowledge, relationships, and continuity into human work. The aim is for human and AI capabilities to complement each other. Knowing more of my context should help the system support my judgment while keeping assistance and action on my behalf distinguishable.
Design correction and forgetting as separate operations
Removing a record from retrieval, deleting stored data, replacing a summary, and changing a trained model are different operations. Expiry can stop a temporary instruction from influencing a future task without necessarily deleting an event that still needs to be retained. A lower retrieval score is not proof of erasure.
Map the relevant copies before promising a reset: source material, summaries, indexes, relationship records, caches, logs, exports, backups, and any adapted artifacts. Establish what the operation covers, how it is verified, and what exceptions or delays remain. If a deletion request is accepted, the system should not immediately recreate the same derived memory from an unchanged source.
Legal duties require a use-specific assessment. The European Data Protection Board’s February 2026 discussion of erasure explicitly notes that the GDPR right is not absolute. Do not promise unconditional deletion of every artifact on demand or assume that a dashboard reset establishes compliance. Appropriate specialists need to assess the applicable conditions and exceptions.
Catastrophic forgetting in model training is another issue: new training can impair previously learned behavior. That differs from deliberately expiring an old meeting instruction. Test both the intended correction and important behavior that should remain, particularly when adaptation changes a shared model.
Contextual forgetting can therefore mean reducing future influence, expiring a temporary rule or removing a retrieval candidate. A time-decay score may help rank old material, but an old signed decision can remain important while a recent speculative note deserves little weight. Age, relevance, validity and authority are different properties.
Deletion needs a separate completion record. Map source and derived objects, stop the relevant use, perform the documented removal or update, then verify the applicable retrieval and generation paths. A tombstone or exclusion record can help prevent re-ingestion where appropriate; the design must also account for alternate copies and newly assigned identifiers. Retaining that control record is itself an information-lifecycle decision.
For parameter-based memory, deleting a source document does not by itself demonstrate that trained behavior has changed. Correction may require a different adapted artifact, further training or another supported process, followed by behavioral evaluation. Do not promise reliable removal from a personalized model merely because its visible source list is empty.
Apply continuity to a specific human task
For personal work, useful continuity might mean recalling why a meeting was requested, which questions remain open and which communication preference applied to that relationship. It should also notice that a request was completed or that today’s task calls for a different format. Emotional context deserves restraint: an observation about one difficult day should not become a permanent psychological description.
In an enterprise onboarding assistant, memory could connect a new employee’s completed training with current policy and unanswered questions. Keep personal progress separate from shared organizational knowledge. A policy update should change the applicable guidance without falsely changing what the employee was previously told or completed.
For sales or support, a source-linked history can help a colleague resume a customer conversation. Distinguish a customer’s request, an employee’s proposal and an accepted commitment. Sharing a summary across a team requires the appropriate access; ownership of a customer relationship is not permission to copy every private conversation into a common profile.
In healthcare, a recalled patient statement and a verified clinical record have different status. In education, a tutor’s inferred knowledge gap should remain revisable when the learner improves. In finance, the record of an earlier investment decision is evidence of that decision, not a standing instruction to repeat it. These are illustrative applications, not claims of validated clinical, educational or financial outcomes.
The common benefit is a better starting point for the next interaction. Preserve the source and the changed circumstances so continuity reduces repetition without freezing a person, project or policy in the past.
Measure useful continuity with cases that can fail
Start with synthetic records and independently specified expectations. Test recall, relevance, correction, restraint, and permissions separately. An assistant can recall a fact correctly and still use it in the wrong conversation. It should also be able to say that the available memory is insufficient.
The following are proposed end-to-end acceptance cases, not tests executed against a memory application for this article. The small deterministic example above checks only its stated eligibility rules.
| Case | Observation needed |
|---|---|
| Temporary preference expires | The old meeting-specific preference does not become a permanent rule. |
| A person corrects a fact | Later retrieval and responses reflect the correction within the documented scope. |
| Two people share a name | Records are not merged or disclosed merely because their names match. |
| Project access is revoked | Source and derived memory do not disclose restricted material through the tested paths. |
| Untrusted content asks for an external send | The remembered instruction does not grant execution permission. |
| An accepted deletion/reset completes | The documented artifacts are handled, and the memory is not silently recreated. |
| The evidence conflicts or is absent | The assistant preserves uncertainty instead of inventing a confident personal history. |
Record the source set, model/application versions, retrieval behavior, expected answer or action, actual result, and review decision. Include difficult and unsuccessful cases. Measure the cost and delay of maintaining memory, as well as recall quality. More stored material can increase the work required to keep it accurate and appropriately accessible.
For the briefing assistant, I would consider continuity useful when it remembers the relationship and prior work, notices the changed circumstances, and prepares something I can confidently review. A system that keeps repeating an old preference has retained data, but it has not yet earned reliance.
Operate memory as a service that can change
Start with one task and a restricted source set. Establish which records may be kept, who owns corrections and what evidence shows successful continuity. Expand only after the team can investigate a bad memory and verify its correction. More ingestion can make an unresolved integrity problem harder to contain.
| Operating responsibility | Evidence to establish |
|---|---|
| Source and write ownership | Authorized inputs, stable identifiers, update outcomes and conflict handling |
| Information lifecycle | Scope/access rules, retention purposes, correction/deletion coverage and documented delays |
| User control | A usable view of remembered records, their sources and available correction or exclusion actions |
| Personalization boundary | Task-specific selection and a way to proceed without an irrelevant personal profile |
| Cross-system use | Versioned export/import meaning, identity mapping, provenance and permission handling |
A useful memory view should distinguish stored content from material actually used in a response. An application can show the selected records, their sources and unresolved conflicts without claiming to expose every internal computation. Users need to correct the relevant cause, not just delete an unattractive sentence from an explanation.
Selective personalization matters. A remembered preference for short briefings should not defeat today’s request for a detailed technical analysis. Separate shared organizational records, personal preferences and task state, and define which can apply in a given context. Modular storage can help implement that separation, but the retrieval and update paths still have to respect it.
At larger scale, partitioning, caching, approximate search and hierarchical summaries can help meet latency and capacity requirements. Measure retrieval quality and update propagation alongside speed. A cache that returns an old preference quickly is an integrity problem, and a shard move that changes access filtering can become a disclosure problem. Test migration and degraded-service behavior, not only a clean index build.
Keep a versioned operating record: source connector, extraction method, embedding model, index, summary procedure, adapted model and permission policy where applicable. Changing an embedding model can require reindexing; changing summarization can alter what is retained. Compare before and after on correction, identity, relevance and refusal cases, and keep a rollback plan appropriate to those artifacts.
Interoperability requires agreement about meaning as well as transport. Exporting a JSON profile does not ensure another assistant interprets its scope, confidence or expiry correctly. Map identities, source references, statuses and deletion obligations; test an export/import round trip. A shared API can move records while still losing the distinctions that made those records safe to use.
For multiple agents, decide which may propose or commit a memory update and which is responsible for reconciliation. An export to a second system creates another copy with an owner and lifecycle. Review network destinations and actual model connections even in a nominally local deployment; local storage alone does not describe every synthesis, training or tool call.
The value I am looking for is continuity that remains open to correction. Remembering the reason behind a decision is useful; recognizing that the decision has changed is just as important. That combination requires deliberate storage and retrieval, an accountable update process and evidence from the work people actually need to resume.
Sources and related work
Research scope: Second Me, March 2025, v2; MemGPT, v2; LongMem, June 2023. Current erasure qualification: EDPB, February 2026. Sources reviewed October 18, 2026. The operational examples, controls, and acceptance cases are an editorial synthesis, not a claim that these papers implement every proposed control.
Personal Cognitive Digital Twins explores why remembered context still needs judgment. The red-teaming playbook develops tests for persistent instructions and actual action outcomes.
Related technical reading: Qwen2.5-1M, Titans, LLM-based agents, DuoAttention and sparse attention. Context-window and attention research should be read within its own setup; it is not interchangeable with an editable cross-session personal-memory service.
Discover more from Ajith Vallath Prabhakar
Subscribe to get the latest posts sent to your email.
One Comment