Quick brief
US enterprises with European exposure need to classify each AI use, establish their provider and deployer responsibilities, and follow the applicable timetable in the amended EU AI Act. This guide connects those legal distinctions to banking, insurance and healthcare examples, then develops the oversight, evidence, change control and engineering work needed to make a compliance decision defensible.
Full analysis
Originally published: 9 March 2026. Revised: 18 October 2026.
A bank can host an AI system in Virginia and still have a European regulatory question to answer. The server address is easy to find. The harder work is following the output: who uses it, which decision it influences, and who is affected when that decision is wrong.
Consider a hypothetical US bank expanding its European business. Its shared AI platform summarizes corporate financial statements, scores individual borrowers and raises fraud alerts. Those applications may share a model gateway, identity service and data pipeline. They do not necessarily share an EU AI Act classification. Treating them as one item called “credit AI” conceals the distinctions that matter for both legal assessment and engineering.
I would begin by following a case through each workflow: a financial statement summary into an analyst’s report, a credit score into a consumer-loan decision and a fraud alert into the service that can suspend a transaction. At each handoff, identify the organization making the decision and the evidence it receives. The resulting trace gives counsel something specific to assess and gives engineers a control boundary they can build.
The legal assessment and the implementation have to stay connected throughout the system’s life. A classification memorandum may describe the intended use correctly when it is written, yet six releases later the application may use a different model, consult another data source or execute an action that originally required approval. The memorandum cannot notice those changes by itself.
This discussion uses the law and official guidance available on 18 October 2026. The July 2026 amendments changed important dates and provisions; the original August 2026 high-risk deadline is no longer an adequate planning assumption. The examples below are illustrative engineering proposals, not accounts of client work. A particular organization still needs a legal assessment of its activities and applicable sector rules.
A short orientation before the full analysis
There are four decisions to keep separate. First establish whether the relevant actor and use fall within scope. Then determine the intended purpose and classification of the system. Identify whether the organization is a provider, deployer or another operator, and which model-provider responsibilities sit upstream. Finally, map the resulting requirements to the actual release and workflow.
Some obligations already apply, including AI literacy measures and specified transparency duties. The main high-risk requirements have different dates for Annex III uses and the product-safety route. A later date is implementation time, not evidence that a running service has no present obligations.
For a reader beginning an inventory, the scope and sector sections come first. For a team already building a consequential application, the documentation, oversight, logging and agent sections explain what I would test. The six-decision roadmap brings those strands together. This orientation is additive; the analysis below carries the qualifications and practical detail needed to use it.
How an AI system in Virginia can trigger European obligations
The Act does not use hosting location as a universal jurisdiction test. Article 2 covers several actors and situations: providers placing systems or general-purpose models on the EU market, deployers established in the Union, and third-country providers or deployers where the system’s output is used in the Union. The provision concerning affected persons should be read within that scope structure, rather than turned into a slogan that any output reaching any European automatically settles every legal question.
The practical distinction is between a technical connection and an assessed use. A public webpage being accessible in Europe, a report being emailed to a European colleague and a score being used to determine a European borrower’s access to credit are descriptions requiring different examination. An inventory that records only “EU traffic: yes” loses the decision, organization and intended purpose behind the output.
For the hypothetical bank, I would create an exposure record with the business process, entities involved, output destination, affected people and action taken. If the corporate-credit team sends a summary to an EU subsidiary, record whether that subsidiary uses it as background research or as an input to a decision. If an individual’s score is used in a lending process, record the lending entity and the score’s practical influence. A system can be advisory in its documentation and decisive in routine use.
Internal development is not a general exemption. The definitions in Article 3 include putting a system into service for own use under the specified conditions. The relevant question is what the organization develops and puts into service, under whose name and for which purpose. Buying a model through a US contract does not answer that question either.
My working record would include an explicit unresolved category. If the team cannot establish where an output is used, or which entity owns the resulting decision, that is a fact to investigate. It should not become a confident “out of scope” entry because the infrastructure happens to be domestic. Equally, a cautious engineering posture should not be presented as a legal conclusion that everything in the inventory is high-risk.
One application can involve several responsibility holders
A foundation model, an application built around it and an organization using the application are different objects in the value chain. The bank might buy a hosted model, build a lending assistant under its own name and use that assistant in its operations. Depending on the facts, it may hold more than one role. The model supplier’s work does not automatically satisfy the bank’s system-level responsibilities.
The Commission’s GPAI guidance and its detailed questions and answers distinguish general-purpose model-provider duties from those of downstream system providers. Model duties include documentation, information for downstream providers, copyright-policy measures and a training-content summary, subject to the applicable provisions and exemptions. Systemic-risk model providers have additional responsibilities. This is not a requirement for every application customer to recreate the upstream training process.
For the application, provider status depends on the definition and circumstances, not merely on whether an API appears in its architecture. The organization needs to examine development under its own name, placing on the market or putting into service, and the intended use. A deployer using a supplied system under its authority has its own obligations; it does not become a model provider simply by sending prompts.
| Layer in the illustrative bank workflow | Responsibility question | Evidence I would request |
|---|---|---|
| General-purpose model supplier | What model obligations apply to this supplier and version? | Available downstream documentation, limitations, change notices and contractual access to relevant evidence |
| Lending application provider | Who owns the intended purpose, system design and applicable conformity route? | System description, classification reasoning, risk assessment, technical documentation and release evidence |
| Bank or subsidiary deploying the application | Who controls use, review, monitoring and the resulting action? | Operating instructions, reviewer authority, local workflow tests, monitoring and incident arrangements |
| Tool or infrastructure supplier | What dependency can change behavior or impede investigation? | Version identifiers, service commitments, access boundaries and incident cooperation |
This table is an engineering aid for exposing gaps such as a supplier promising documentation that the application team cannot retrieve, or a provider assigning monitoring to a deployer that receives no useful telemetry. There is also a statutory requirement: amended Article 25(4) requires the high-risk system provider and relevant third-party suppliers to specify the necessary information, capabilities, technical access and assistance by written agreement. Its exception for publicly accessible free and open-source tools, services, processes or components excludes general-purpose AI models from that exception. The particular supplier and dependency therefore matter.
Article 25 also matters after launch. Rebranding a high-risk system, substantially modifying one or changing a system’s intended purpose so it becomes high-risk can shift provider responsibilities under the specified conditions. The “one-third of original training compute” criterion discussed in GPAI guidance concerns significant modification of a general-purpose model. It is not the Article 25 test for changing a high-risk application’s purpose or behavior.
Where Article 25(2) applies, the initial provider must cooperate with the new provider through necessary information and reasonably expected technical access and assistance. The amended provision names relevant technical documentation, known limitations and failure modes, and targeted testing access. Its exception where the initial provider clearly specified that the system was not to be changed into a high-risk system deserves attention before the bank repurposes a supplied application.
I would therefore have two change questions in the release review. Has the model been modified in a way relevant to model-provider guidance? Has the system’s intended purpose, responsibility allocation or conformity basis changed? Combining them into one checkbox called “fine-tuning” makes it too easy to miss a system change that used almost no training compute.
The timetable has changed, but work has not disappeared
The Commission’s current implementation page confirms that the AI Omnibus entered into force on 27 July 2026. The consolidated text incorporates Regulation (EU) 2026/1744, the authentic amending act. Consolidation is a documentation tool; the Official Journal acts are the authoritative publications.
The main dates relevant to the workflows discussed here are:
| Provision or route | Applicability point | Planning consequence |
|---|---|---|
| Initial prohibited practices and AI literacy provisions | 2 February 2025 | Assess current use and staff measures now; check later amendments separately |
| GPAI obligations and governance provisions | 2 August 2025, with specified transitions | Check the model’s placement date and applicable duties rather than treating all models identically |
| Specified transparency obligations | 2 August 2026 | Review live interactions and content workflows; the high-risk extension does not suspend these duties |
| Article 50(2), covered systems already on the market before 2 August 2026 | Transition to 2 December 2026 | Identify whether this particular provider transition applies |
| Newly added prohibitions in Article 5(1)(ba), (bb), 5(1a) and 5(1b) | 2 December 2026 | Assess relevant content-generation uses against the actual prohibited-practice provisions |
| Chapter III Sections 1–3, except Article 6(5), for Article 6(2)/Annex III systems, including provider/deployer duties and Articles 26–27 | 2 December 2027 | Plan classification, controls, oversight and impact-assessment readiness against the revised route |
| Chapter III Sections 1–3, except Article 6(5), for Article 6(1)/Annex I high-risk product systems | 2 August 2028 | Coordinate product and AI assessment work rather than substituting the Annex III date |
The exact provisions are Articles 111 and 113. Existing systems have specific transitional rules; public-authority high-risk systems and certain large-scale IT systems have further provisions. Those exceptions need an entry in the assessment, not a generic “legacy system” label. The July amendments also add prohibitions with their own December 2026 application date. A plan should identify the actual provision it tracks.
I would separate the legal date from the internal readiness date. The latter needs room for failed tests, changes to supplier evidence and corrections discovered by reviewers. A schedule ending with “compliant by December” is too coarse to manage. Classification approved, oversight demonstrated, documentation reconciled and operational ownership accepted are distinct milestones.
For the bank, a missed supplier-documentation milestone should be visible before it blocks the final assessment. A failed rejection test should remain open even when the policy document is signed. That is the benefit of treating readiness as a set of demonstrated conditions rather than a single declaration.
Classification starts with the decision, not the industry label
There are two main high-risk routes. Article 6 addresses covered products or safety components under the conditions in paragraph 1, and the use cases listed in Annex III through paragraph 2. An application’s sector is context; it is not a substitute for either route.
Banking: individual credit, corporate analysis and fraud are different uses
Annex III lists systems intended to evaluate the creditworthiness of natural persons or establish their credit score, with an exception for systems used to detect financial fraud. A corporate counterparty is not a natural person. A corporate-financial-statement assistant should therefore not be declared high-risk under this provision merely because the bank uses the word “credit.” Other applicable routes and laws still require examination.
The fraud exception is equally specific. It does not mean every activity labeled fraud detection is exempt from every AI Act obligation or banking requirement. Nor does the absence of a standalone algorithmic-trading category create a general statutory immunity for trading systems. Assess the intended use and other potentially applicable provisions instead of treating “not listed here” as “unregulated.”
The EBA’s November 2025 mapping examines interaction with financial-sector requirements. The useful starting point is to map existing model-risk, governance and operational-resilience controls to the AI use. It is not to presume that the bank must build a second organization from scratch, or that banking supervision automatically closes every AI Act gap.
In the hypothetical shared platform, I would separate three release records. The corporate analyst’s assistant needs evidence that its citations and summaries are reliable for that use. The individual-credit application needs its assessed classification and controls tied to the lending workflow. The fraud-alert path needs its own thresholds, escalation and service-impact tests. Shared infrastructure can implement common identity and logging controls while preserving these differences.
An acceptance test could deliberately send a consumer-credit case to the corporate-research endpoint. The application should reject the unsupported use or route it through the assessed process. A model gateway that accepts both requests successfully has demonstrated connectivity, not correct governance. Classification needs a practical boundary somewhere in the running service.
Insurance: outside one high-risk category does not mean outside governance
Annex III’s insurance category concerns risk assessment and pricing in relation to natural persons for life and health insurance. It does not list all underwriting, all claims management or all property-and-casualty pricing as high-risk merely because they occur in insurance. Another use within an insurer, such as employment screening, may require a different Annex III analysis.
The EIOPA Opinion of 6 August 2025 is particularly useful for understanding the remaining systems. It addresses national supervisors and explains a proportionate application of existing insurance-sector governance and risk-management principles. It explicitly does not extend the AI Act’s high-risk requirements to every insurance system or create a new set of obligations by itself.
That leaves substantial engineering work worth doing. Consider a hypothetical property-claims assistant that sorts documents, proposes a repair category and drafts a response. I would distinguish clerical sorting from a recommendation that effectively determines whether a claim is paid. The team should know which evidence the handler sees, whether a disputed classification can be corrected and whether the correction reaches downstream services.
Suppose the assistant reads a photograph incorrectly and proposes exclusion from coverage. A handler corrects it, but a separate letter-generation service still uses the earlier category. The oversight failure occurs in the handoff, even if the classification memorandum correctly concluded that this use was not in the life-and-health pricing category. Keeping the legal distinction does not require ignoring the operational consequence.
For a life-insurance pricing system, I would retain a more detailed decision record: intended population, relevant data, performance limitations, review arrangements and the pricing action produced. Evaluate group-level performance using an approved, lawful data strategy. A claim that “bias mitigation saves regulatory capital” needs its own evidence and assumptions; it should not replace an examination of the model, data and decision process.
Healthcare: the product route, emergency triage and research need separate assessments
For medical-device AI, the Article 6(1) route depends on the product or safety-component conditions and the required third-party conformity assessment. Not every piece of hospital software or every use of machine learning is automatically a high-risk medical device. Annex III point 5(d) separately lists emergency healthcare patient-triage systems. Where a system is covered by Annex I Section A legislation and also falls within Annex III, amended Article 43(3) directs the provider to the sectoral conformity-assessment procedure. The combined classification and applicable timetable need examination for that system. Routine scheduling and emergency prioritization should not be grouped together under the broad label “patient triage.”
MDCG 2025-6/AIB 2025-1 explains the interplay of the AI Act with MDR/IVDR. It supports integrating appropriate testing, documentation and procedures with existing device processes while satisfying all applicable requirements. It is non-binding guidance, published before the July 2026 amendments, so its older timetable must not override the current law. Integration is useful; a claim that it halves the burden would require measured evidence that the guidance does not provide.
For an illustrative imaging device, I would map the AI evaluation to the device’s intended clinical use, software configuration, user interface and post-market process. An accurate model result in a laboratory does not establish safe integration into a clinician’s workflow. Test the relevant input quality, display behavior, unavailable-service path and the information needed for a clinician to interpret the output. A model update should trigger the appropriate change assessment across both regulatory and engineering records.
Drug discovery needs a different discussion. EMA’s 2024 reflection paper addresses AI across the medicines lifecycle. An early exploratory prediction and evidence used to support a regulatory decision do not have the same consequences. I would avoid the blanket assurance that no patient can be affected by a bad research prediction. The model’s context of use, downstream reliance and evidence pathway matter.
The January 2026 FDA/EMA announcement establishes a common set of ten guiding principles for AI in drug development. That cooperation is a reason to look for reusable evidence and compatible methods. It is not mutual recognition of every submission or proof that one compliance architecture automatically satisfies both jurisdictions.
The profiling rule is important, but it is not universal
Article 6(3) provides a constrained exception for certain Annex III systems that do not pose the specified significant risk, including through not materially influencing the decision outcome, where one of the stated conditions applies. The conditions concern narrow procedural work, improving completed human activity, specified pattern review with proper human review, or preparatory tasks. A provider relying on the exception must document its assessment and meet the applicable registration requirement.
The profiling sentence prevents an Annex III system performing profiling of natural persons from using that exception. It does not make any AI system anywhere high-risk simply because it profiles a person. Cross-selling therefore needs its actual Annex III and other-law analysis; it cannot be classified solely by repeating “profiling override.”
I would also avoid deciding that building every uncertain system to high-risk standards is always cheaper than explaining its classification. Extra controls can be sensible. They do not remove the need to identify the intended use and responsibilities, and the economics depend on the application. A low-consequence preparatory tool and a loan-pricing system should not inherit the same review queue just to avoid an uncomfortable classification discussion.
The useful output is a reasoned, versioned assessment with an owner and a trigger for reconsideration. State the facts that support the conclusion. If the tool later starts ranking people or executing decisions, that change should reopen the assessment rather than disappear inside a routine feature release.
Literacy and transparency need to reach the actual user
AI literacy is a current responsibility, not an item to postpone until the high-risk timetable arrives. The Commission’s updated Article 4 questions and answers explain the July amendment: providers and deployers must take measures supporting literacy development in context, without guaranteeing a specified individual level. The Act does not prescribe one training certificate or one course for every employee.
For the bank, I would give a lending reviewer a different learning exercise from a customer-service writer. The reviewer should practice identifying unsupported recommendations, interpreting limitations and escalating a case outside the permitted use. The writer should practice checking facts, protecting sensitive information and recognizing when a draft needs specialist review. An engineer maintaining the model gateway needs to understand a third set of responsibilities, including what a supplier change can alter.
The record of those measures should be useful after the workshop. Keep the scenario, the roles addressed, the guidance provided and the date. If the application gains a new action capability, update the exercise. This is my operational recommendation for making the effort examinable; it should not be misrepresented as a statutory requirement to buy a particular learning platform or collect a certificate from every user. Separately, Article 26(2) requires high-risk deployers to assign oversight to people with the necessary competence, training, authority and support; the Article 4 amendment does not remove that responsibility.
Transparency has another set of boundaries. Article 50 addresses specified situations, including direct AI interaction, covered synthetic-content marking, emotion-recognition or biometric-categorization disclosures, deepfakes and certain public-interest text publication. It assigns different duties to providers and deployers and contains exceptions. It does not impose an identical watermark on every internal AI-assisted sentence.
The Commission’s July 2026 transparency guidance gives teams a current implementation reference. The user-facing question is straightforward: can the person understand what they are interacting with at the point when it matters? A disclosure that disappears when chat becomes voice, or is visible only on an inaccessible policy page, deserves a real experience test.
For a hypothetical claims chatbot, I would inspect the opening interaction, a return visit and an embedded version on a partner’s site. If the system hands a case to an employee, the interface should make that transition understandable. The disclosure and escalation path should survive translation, a narrow phone screen and a change of channel. These are tests of the proposed design, not assurances that a particular phrase satisfies every legal situation.
Documentation must describe the system that is running
A risk assessment for one system version becomes less useful when the deployed application changes without an associated review. Connecting compliance with engineering means keeping that evidence aligned with the release; choosing a document format cannot guarantee the connection.
Article 11 addresses technical documentation, with Annex IV specifying its contents. Article 17 addresses the quality management system. These are related to, but distinct from, the risk-management, data-governance, transparency, oversight, accuracy and security requirements in Articles 9–15. An organization needs an account of how the controls work together.
For the illustrative lending application, I would maintain a release evidence package containing the intended use and exclusions; model, prompt and retrieval configuration; approved data sources; evaluation cases and results; oversight design; known limitations; incident arrangements; and the decision authorizing the release. A component inventory can help locate dependencies, but an “AI bill of materials” is not a complete conformity assessment. It cannot tell a reviewer whether the workflow respects a rejected recommendation.
The seven requirement areas deserve separate evidence without becoming seven disconnected workstreams. The legal references below identify their purpose; the proposed artifacts and tests are my implementation choices.
| Requirement area | Evidence I would maintain | A concrete review question |
|---|---|---|
| Article 9: risk management | Hazards, foreseeable misuse, mitigations, residual risks and predefined evaluation criteria | Did testing cover a plausible misuse, or only the workflow the team hoped users would follow? |
| Article 10: data governance | Data origin, preparation, assumptions, suitability, gaps and relevant bias analysis | Does the evidence support the intended population and setting, rather than a convenient training sample? |
| Article 11: technical documentation | A reconciled system description and evidence package for the assessed release | Can a reviewer identify which deployed configuration the assessment actually describes? |
| Article 12: record-keeping | Traceable events and controlled evidence references | Can the team reconstruct a disputed recommendation and the action that followed it? |
| Article 13: information to deployers | Usable instructions, performance limitations, input requirements and relevant interpretation guidance | Can the operating team recognize a case for which the system was not evaluated? |
| Article 14: human oversight | Authority, interface, support and tested intervention arrangements | Does a reviewer’s correction or rejection reach the executing service? |
| Article 15: accuracy, robustness and cybersecurity | Intended-use metrics, failure tests, security assessment and mitigation evidence | What happens under degraded inputs, service faults, poisoning or an adversarial request relevant to this system? |
For example, an evaluation may look strong overall while a relevant borrower group is poorly represented in the test data. That is a data-governance issue, a performance limitation to communicate and a risk-management question about deployment. Adding a warning to the interface does not necessarily resolve the underlying gap. Conversely, a model improvement can still fail to improve the decision if the reviewer receives evidence too late to act.
Sensitive-data processing for bias detection needs a current, specific legal analysis. The July text’s Article 4a supplies exceptional, conditional bases: paragraph 1 addresses high-risk providers, while paragraph 2 addresses other providers and deployers, including high-risk deployers. Its safeguards include strict necessity, lack of an effective alternative using other data, access and reuse limits, and deletion conditions. Paragraph 2 expressly creates no obligation to conduct bias detection or correction. Article 10 now refers to Article 4a; the former Article 10(5) should not be used as the current provision. Decide the applicable basis, purpose and safeguards before collecting sensitive attributes.
The deployer’s impact assessment also needs attention. Article 27 covers public-law bodies and private entities providing public services using covered Annex III systems other than point 2, as well as deployers of the creditworthiness and life-and-health insurance systems in points 5(b) and (c). It concerns the first use, with updates when relevant information changes and notification of results under the prescribed arrangements and exceptions. Its fundamental-rights assessment addresses the actual processes, affected groups, risks, oversight and response arrangements. The amended provision permits relevant cross-references or material from a data-protection impact assessment; the assessments still have distinct purposes.
For the bank, I would connect that assessment to the complaint and correction path. Article 26(11) requires deployers of Annex III systems making or assisting decisions about natural persons to inform those people that the system is used. If a borrower disputes a decision, which team can retrieve the evidence, identify whether the system was used within its assessed purpose and correct an error? A model evaluation completed by the provider does not by itself answer how a deploying subsidiary handles that person’s case.
Where Article 86’s conditions apply to an adversely affecting decision based on covered Annex III output, the affected person has a right to a clear, meaningful explanation of the AI system’s role and the main elements of the decision. Its scope and exceptions matter. A technical trace should help the responsible team explain the decision rather than substitute a model-generated narrative for the evidence.
Documentation-as-code is one way to maintain parts of that package. Generate version identifiers and dependency lists from the actual release, require a change description and link it to the relevant tests. Keep legal reasoning and human judgments under review as well. Automatically changing a model identifier in a document does not establish that the new model’s performance or intended use has been assessed.
I would make the mismatch visible in the delivery process. A release that changes the retrieval collection but points to an evaluation run against the old collection should fail the evidence check. A release that adds a tool for sending a customer letter should reopen the authority and oversight assessment. A corrected spelling mistake in help text need not trigger the same work. The review needs enough discrimination to remain usable.
Version Drift can change the authority behind an answer
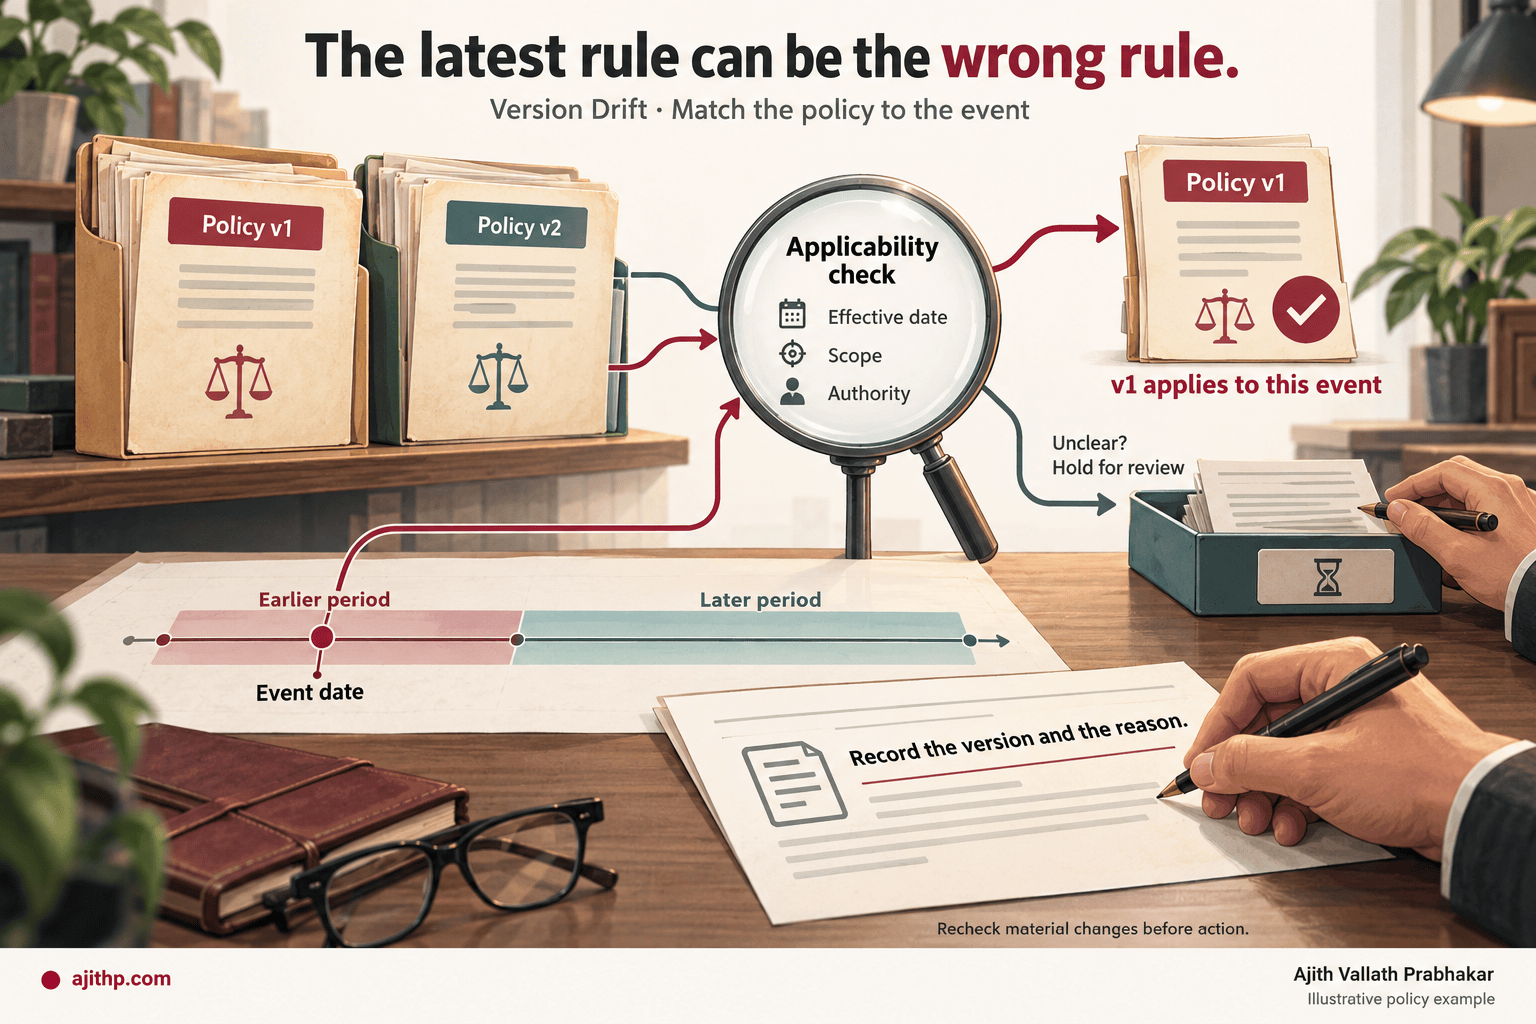


Download the Version Drift discussion map (PDF) · No signup required.
Consider a hypothetical loan recommendation generated under policy version 12. Before the reviewer approves it, policy version 13 changes the applicable eligibility condition. Both policy documents exist in the repository, but the application still displays the earlier recommendation as ready for action.
The problem is not simply missing version history. The case needs a rule for deciding whether a recommendation remains applicable when authority changes. I would bind the recommendation to the policy version, case state and evidence used, then check those conditions again before execution. If they no longer match, the workflow should hold the case and explain what requires reassessment.
The acceptance test follows naturally. Generate the recommendation under version 12, change the applicable policy and attempt approval. Then repeat with a case whose facts change rather than its policy. Finally, replay an old approval after both changes. The team should be able to show which condition prevented an outdated action and what the reviewer saw. There is a separate legal change-control question: Article 111(2) makes significant design changes after the relevant application date a trigger for covered pre-existing high-risk systems, subject to its specific transitions. A changed policy and a significant system-design change therefore need separate assessment rather than one generic version flag.
This is the concern I explore in Version Drift. It is an engineering lens for connecting authority, evidence and execution over time. It does not replace the legal assessment, but it makes a class of failures testable that a static policy document can easily miss.
Conformity routes and existing controls deserve a proper gap analysis
The assessment route is not identical for every high-risk system. Article 43 specifies internal control under Annex VI for Annex III points 2–8. That route is not made conditional on complete application of harmonized standards. Biometrics under point 1 and covered products have different provisions, including conditions concerning notified bodies and sectoral assessment routes.
Internal control is still an assessment, not permission to dispense with evidence. I would identify who reviews the technical package, how disagreements are resolved and what blocks release. Where a notified body is involved, the project plan needs its scope, dependencies and capacity. A team should establish that route early rather than discover at final review that its assurance plan assumed the wrong assessor.
Financial institutions can reuse relevant sectoral processes where the Act provides for that integration. For qualifying institutions, Article 26(5) deems its first-subparagraph monitoring duty fulfilled through compliance with the relevant financial-services internal-governance rules. Articles 19(2) and 26(6) place controlled logs within the documentation maintained under financial-services law, while Article 18(3) addresses technical documentation. Each provision has its scope; this is not a general banking exemption. A gap analysis should name the existing control, the AI requirement it addresses, the evidence available and the remaining limitation.
The Commission’s standardisation page explains another distinction: publication of a standard and its citation in the Official Journal are separate steps. Presumption of conformity attaches to the requirements covered by the relevant cited harmonized standard. ISO/IEC 42001 provides a management-system framework; a certificate is not automatic conformity for a particular AI system. A draft European standard should not be treated as if it had already completed every recognition step.
Logging is an evidence and data-design problem
Article 12 requires high-risk systems to have automatic event-recording capabilities supporting traceability appropriate to their intended purpose. It is not a universal instruction to store every raw input, output and hidden reasoning step indefinitely. The logging design needs to support the relevant risks and monitoring while respecting other applicable obligations.
I would begin by asking what an investigator must reconstruct. In the loan example, that could include the case identifier, system configuration, evidence references, applicable policy version, proposed amount, reviewer disposition, authorization and action result. A correlation identifier connects the recommendation to the queue worker that later acts. Without it, the interface record and execution record may each look plausible while telling different stories.
The content of each field needs its own justification. A stable reference to an approved source may be preferable to duplicating a full document in several services. A redacted summary may support operational investigation, while access to original evidence is restricted elsewhere. A hash can identify a document version, but it cannot replace readable evidence when an authorized reviewer needs to examine its meaning.
Retention also has several layers. Article 18 specifies a ten-year period for particular provider documentation. Article 19 and the deployer provisions in Article 26 address controlled logs, with periods appropriate to purpose and generally at least six months unless other applicable law provides otherwise. These are not a single ten-year command to retain every prompt.
For implementation, I would separate operational logs, decision evidence, security telemetry and retained conformity documentation. Give each category a purpose, access policy, retention rule and deletion or preservation process. Ask which financial, employment, medical or privacy rules apply to the actual data. SOC 2 is an assurance framework, and SOX does not establish one universal retention window for every AI event. Neither should be used as shorthand for “keep everything.”
Encryption and key separation may be useful. Cryptographic erasure can make encrypted data inaccessible when keys are destroyed, but that does not automatically settle a GDPR erasure request. Copies, backups, recoverable keys, other identifying information and legal-retention grounds matter. I would test the proposed mechanism with the organization’s privacy and security specialists rather than claim that an endorsement of crypto-shredding resolves all conflicts.
The operational test should include failure. What happens if the audit sink is unavailable? Which actions must stop, which can continue with bounded buffering, and how is the gap detected? Can someone change a reviewer’s disposition without an attributable record? Can a privileged operator read sensitive evidence outside the authorized investigation? Logging should help answer these questions without becoming an uncontrolled store of personal data.
Human oversight needs a demonstrated effect
Article 14 requires effective human oversight proportionate to risk, autonomy and context. It addresses understanding capabilities and limitations, automation bias, interpretation, overriding or reversing outputs and intervention or interruption where appropriate. It does not certify an application merely because its diagram contains a human icon.
Human-in-the-loop, human-on-the-loop and human-over-the-loop are useful design terms. They are not three statutory compliance badges. I use them to ask where judgment sits and how it can affect the action. The right design may combine individual review, live supervision, boundary setting and retrospective examination, subject to the applicable use and rules.
| Oversight arrangement | Where the human acts | What I would test | Main design risk |
|---|---|---|---|
| Review before action, often called HITL | A reviewer examines a proposed case before authorization | Rejection, correction, missing evidence and stale approval prevent the wrong action | Review becomes hurried or ceremonial under queue pressure |
| Supervision during operation, often called HOTL | An operator monitors permitted operation and can intervene | Alerts arrive in time, intervention reaches execution and unattended periods are handled | A monitoring screen exists, but intervention is too late |
| Boundary setting with exception review, sometimes called HOVL | Responsible people define limits and revisit exceptions and outcomes | Out-of-bound cases stop, changed limits propagate and drift reopens review | Boundaries omit an important case or persist after assumptions change |
There is no defensible universal latency percentage for these patterns. Measure the workflow. An individual-review design may consume little processing time and still create a long queue. A fast autonomous path may create costly rework when a mistake escapes. The useful measure includes time to a correct, accepted decision, reviewer effort, escalation and the consequences of failures.
In the bank example, a reviewer should see the evidence needed to disagree with a recommendation. That does not mean adding friction for its own sake. A single-click rejection can be effective if it changes the workflow; a lengthy approval form can be ineffective if the downstream service ignores it. Authority, usable information, competence and time matter more than the number of clicks.
I would run three tests before trusting the design. Reject a proposed loan approval and let the queued job retry: no approval should execute. Correct the amount and confirm that execution uses the reviewed amount. Change the case after approval and confirm that the old authorization cannot be replayed unchanged. These are concrete engineering tests, not a declaration that passing three scenarios establishes Article 14 compliance.
For fraud alerts, supervision may need much faster intervention than a committee can provide. For a clinical use, the person interpreting the output needs information appropriate to that setting. For bounded insurance automation, define which changes require a new boundary review. A shared platform can support all these arrangements, but it must preserve their different authority and timing requirements.
An agent’s stop control must reach its side effects
The interruption provision in Article 14(4)(e) is relevant to agentic designs, but the word “agent” does not make every application high-risk. Begin with the assessed system and intended use. Then translate the relevant oversight requirement into the orchestration and execution paths.
Consider an illustrative assistant that gathers loan evidence, drafts a recommendation and prepares an instruction for another service. Stopping the language-model loop is insufficient if an instruction is already waiting in a queue. The stop state needs to reach the component that can execute the action. A worker retry should check the current authorization and case state, not assume that an earlier successful model call is permission to proceed.
I would record external actions and state transitions: who or what requested the action, which permission was evaluated, which evidence and policy versions applied, what was approved and what actually happened. This supports reconstruction without treating generated reasoning text as a complete or authoritative account of execution. Hidden chain-of-thought is not a substitute for observable events, and Article 12 does not impose a general requirement to record it.
The interruption test should stop the workflow at several points: before a tool request, after submission but before acknowledgment, during a retry and after a partial result. Check whether the action already occurred, whether it can be reversed and how the operator learns the outcome. “Stopped” is not an accurate status if a service may still complete the action later.
Multi-agent coordination adds another question. If one component is stopped, which other components may continue, and under what authority? A research agent may safely finish collecting public evidence while an execution agent is disabled. A second agent should not recreate a canceled action because it interprets the incomplete work as a task to finish. The permissions and state model must make that distinction explicit.
These controls belong in supplier discussions as well. Ask whether the service exposes stable version identifiers, cancellation status, execution receipts and incident evidence. Confirm what happens when access is revoked or the supplier updates a tool. A successful connector test demonstrates that the service can be called. It says little about whether the resulting action can be stopped or attributed.
Liability and insurance are separate questions from classification
Financial exposure deserves its own analysis, but it loses usefulness when every violation is illustrated with the highest possible fine. Article 99 distinguishes prohibited-practice infringements, specified operator or transparency failures and incorrect information supplied to authorities or notified bodies. The ceilings include €35 million or 7%, €15 million or 3%, and €7.5 million or 1% of worldwide annual turnover, respectively, generally using the higher amount for undertakings. The current text has lower-ceiling rules for SMEs and specified SMC cases. The applicable tier, circumstances and procedure matter.
Model providers also need to examine the separate Article 101 Commission-fine regime for specified intentional or negligent GPAI infringements. The text provides a ceiling of 3% of preceding-year worldwide turnover or €15 million, whichever is higher; Article 113 leaves Article 101 to the default 2 August 2026 application date. This is a separate basis from Article 99’s operator tiers, not a reason to assign every application the model supplier’s penalty regime.
This is not a reason to discount risk. It is a reason to identify the actual failure. A prohibited use, an inadequate high-risk control and a misleading response to an authority should not be collapsed into one generic exposure estimate. I would have counsel assess the relevant undertaking, enforcement basis and interaction with other proceedings before putting a turnover calculation in a board paper.
Product liability requires another set of conditions. Directive (EU) 2024/2853 includes software and addresses damage caused by defective products. Member States must transpose it by 9 December 2026; its scope covers products placed on the market or put into service after that date. Its presumptions and evidentiary rules do not mean every AI Act breach automatically creates an actionable defect causing compensable harm. Natural persons can claim for the covered categories of personal injury, property damage and destruction or corruption of non-professional data, subject to the Directive’s exclusions and conditions. Pure economic loss from a mistaken financial recommendation does not by itself establish a claim under this Directive; other applicable liability routes need their own assessment.
The Council’s explanation describes the extension to software and changes intended to address evidentiary difficulties. For an engineering team, the useful response is to preserve the configuration, relevant evidence, corrections and action history needed to investigate what happened. Good records cannot eliminate liability, but missing records make responsible investigation harder.
Insurance coverage has to be read in the policy
I would not assume that existing cyber, professional-liability, product-liability or directors-and-officers cover responds to every AI-related loss. Equally, it is too broad to declare that insurers have universally excluded AI or that an enterprise without one governance framework cannot obtain coverage at any price. Coverage depends on wording, exclusions, endorsements, limits, applicable law and the facts of the claim.
There are actual products to examine. QBE’s July 2025 announcement describes AI regulatory-compliance and LLMjacking coverages, while expressly stating that issued policy terms govern. It demonstrates an insurer’s product offering, not universal availability, insurability of every fine or a promise that a particular bank’s loss is covered.
For a hypothetical bank, I would ask the broker to walk through three different events: an unsupported customer recommendation, an unauthorized transaction caused by an agent and a regulatory investigation into a prohibited use. Identify the potentially responding policy, defense-cost treatment, exclusions, sublimits, notice conditions and any gap between supplier indemnity and insurance. Have the relevant specialists examine the actual documents.
Engineering can make that discussion concrete. Show who can execute the action, how the case is reviewed and what evidence survives a supplier change. Ask which representations the application owner is being asked to make about controls. A promise of continuous human review should match the operating design; an annual review of aggregate metrics is a different arrangement.
US requirements need their own map
Reusable controls can support work across jurisdictions, but US state laws and the EU do not share one compliance calendar. Scope, covered actors, decision categories, exemptions, remedies and effective dates differ and can change independently.
The variation is visible in primary sources. California’s SB 53 announcement concerns frontier developer transparency and related measures. Texas HB 149 establishes a different framework. Illinois HB 3773 addresses AI use in employment through its human-rights legislation. Colorado’s Attorney General explains that SB 26-189 repealed and re-enacted the earlier provisions as an automated decision-making technology framework, with the new requirements effective 1 January 2027 and rulemaking underway in October 2026. These are starting points for separate applicability reviews, not interchangeable versions of Annex III.
I would keep a control library and a jurisdiction map. A versioned decision record, tested intervention path or documented risk assessment may support several obligations. Each mapping still needs the rule, covered use, required evidence, owner and date. A control can be reused while its legal significance differs.
NIST AI RMF is a voluntary risk-management foundation. ISO/IEC 42001 addresses an organizational AI management system. Both can help organize the work. Neither should be sold as a universal safe harbor or a substitute for the specific legal analysis. Building to the “strictest rule” is also insufficient when rules address different actors or require different procedures rather than simply different thresholds.
The business case for reuse should be measured. Track duplicated assessments avoided, evidence-maintenance effort, reviewer time and change lead time. Compare those savings with the cost of maintaining the shared control library. A claim of a guaranteed lower three-year cost would need an actual baseline and assumptions.
Six engineering decisions for the readiness plan
The following sequence is how I would turn the analysis into delivery work. It is not a statutory checklist, and engineering does not replace counsel or accountable business owners. It makes their decisions observable in the system.
1. Map exposure at the decision boundary
Choose one consequential use and trace an output into action. Record the entities, geography of use, affected people and intended purpose. Link the record to a named system owner and release. Include upstream models and downstream tools without treating every dependency as a separate business decision.
The acceptance condition is a trace someone else can follow. For the bank, a reviewer should be able to locate the lending entity, identify the score’s role and find the service that issues the decision. An architecture diagram containing only “LLM → business value” does not meet that condition.
2. Classify the use and record what would change the conclusion
Assess the product route and the relevant Annex III categories. Where an Article 6(3) exception is used, retain its reasoning and required supporting record. Apply the profiling provision within its actual scope. Keep current legal dates and transitions attached to the assessment.
Then specify a change trigger. A summary assistant that begins ranking applicants, a new population or a new execution capability should not inherit an old conclusion without review. Test the product boundary as well: can a user silently use the low-consequence endpoint for a consequential decision it was not assessed to support?
3. Choose oversight before fixing the execution path
Decide who can approve, reject, correct or stop an action, and what they need to do so effectively. Estimate workload using representative cases and realistic review time. An approval queue without enough competent reviewers is an operating problem, not a future training detail.
Demonstrate rejection under retry, corrected values at execution and stale-approval rejection. Include an unavailable reviewer or monitoring service. Measure total time to a sound decision, including escalations and corrections, rather than optimizing only model response time. This is where Decision Velocity needs to include authority and quality alongside speed.
4. Tie the evidence package to the release
Version the actual model configuration, sources, prompts, policy and evaluation results. Generate what can be generated reliably, then review the judgments automation cannot establish. Assign an owner to reconcile the package when a supplier changes behavior or evidence becomes unavailable.
An acceptance check should deliberately introduce a mismatch: deploy a new configuration while the documentation references the previous evaluation. The mismatch should be detected. Restoring an older release should restore its relevant records without pretending an old assessment authorizes a new purpose.
5. Design traceability, retention and privacy together
Define the events needed to investigate the workflow. Connect recommendation, human disposition, authorization and execution with stable identifiers. Minimize unnecessary content duplication and document access, retention, deletion and preservation rules by data category.
Test missing logs, delayed delivery, tampering, privileged access and erasure or retention scenarios. If encryption-key destruction is proposed, examine all copies and recovery paths. The objective is usable, appropriately controlled evidence, not the largest possible log archive.
6. Fund continuing ownership, not only launch documentation
Name the people responsible for monitoring, incident escalation, supplier changes and reassessment. Map reusable controls to each applicable jurisdiction and sector obligation. Plan legal, business, privacy, security and engineering review together, with explicit unresolved items.
The first funded deliverable could be one complete case trace with a tested failure path and reconciled evidence package. That is more informative than a green readiness dashboard supported only by policy documents. Extend the pattern to other uses after learning where the first one fails.
Questions that recur during implementation
Does using a US data center keep the application outside the Act?
No general exemption follows from that fact. Assess the actor, market or service activity and use of the output under Article 2. Record the actual workflow rather than treating either a US server or an EU customer as a complete legal opinion.
Is every system used by a bank, insurer or hospital high-risk?
No. The intended use and applicable route matter. Natural-person creditworthiness, specified life-and-health pricing and emergency healthcare triage have particular listings; corporate analysis, property-claims support and routine scheduling require their own assessment. Other laws and operational risks can remain important even when a particular Annex III listing does not apply.
Does an upstream model supplier’s documentation cover the application?
It can supply essential information, but the application adds data, instructions, interfaces, tools and an intended purpose. Assess the model and system roles separately. Ask what evidence the downstream organization can actually obtain and keep when the supplier updates the service.
Does human review need to precede every output?
Article 14 does not create one identical review sequence for every use. The arrangement must be effective and proportionate to the relevant risks, autonomy and context, with other applicable rules considered. Describe the intervention that can change the action and demonstrate it; a label such as HITL cannot do that work.
Must we preserve every prompt and the model’s full reasoning?
The general logging provision does not impose that blanket requirement. Identify the relevant events, evidence and retention obligations, then design a trace that supports investigation without unnecessary sensitive-data collection. An explanation generated by a model should not be confused with a record of the actions the system actually executed.
Does ISO/IEC 42001 certification settle conformity?
It provides evidence about the assessed management system, within its scope. System-specific requirements and the applicable conformity route remain. For a presumption based on harmonized standards, verify the actual Official Journal reference and requirements covered rather than relying on a draft’s name.
Does an AI Act violation automatically mean a 7% fine and uninsured product liability?
No. The penalty tier, facts and procedure matter. Product liability has its own scope and conditions, and insurance depends on the policy and applicable law. Keep these analyses connected to the same incident evidence while assessing them separately.
What should the first review session produce?
Take one consequential case through the proposed workflow, then repeat it after a rejected recommendation or changed policy. Leave with a clear use description, responsibility map, observed control failures, missing evidence, owners and dates. That is an actionable readiness record. It also gives the next review a way to establish whether anything improved.
Sources for continuing the work
The current consolidated Act, its linked authentic Official Journal acts and the Commission’s implementation page anchor the legal reading. The Commission’s AI Act Service Desk makes individual provisions easier to navigate; its summaries are explanatory and should be distinguished from the legislative text.
For sector work, start with the EBA banking analysis, EIOPA’s insurance Opinion, MDCG/AIB medical-device guidance and EMA’s medicines-lifecycle materials linked in the relevant sections. Read the dates and status of each: guidance is not the statute, and a 2025 document may describe a timetable subsequently amended in 2026.
The related discussions on Version Drift, Decision Velocity and enterprise AI governance develop the architectural argument. The practical test remains the same: the organization should be able to explain which system supported a decision, under which authority, with what evidence, and whether the human responsible could change what happened.
Discover more from Ajith Vallath Prabhakar
Subscribe to get the latest posts sent to your email.
One Comment