Quick brief
Agentive AI describes a human-centered way to think about systems that support people; it is related to, but different from, the model-directed systems now often called agentic. The value depends on the task, evidence, data access, authority granted to the system, and the people responsible for its decisions and actions.
Full analysis
Originally published February 18, 2024. Updated October 18, 2026.
What is Agentive AI?
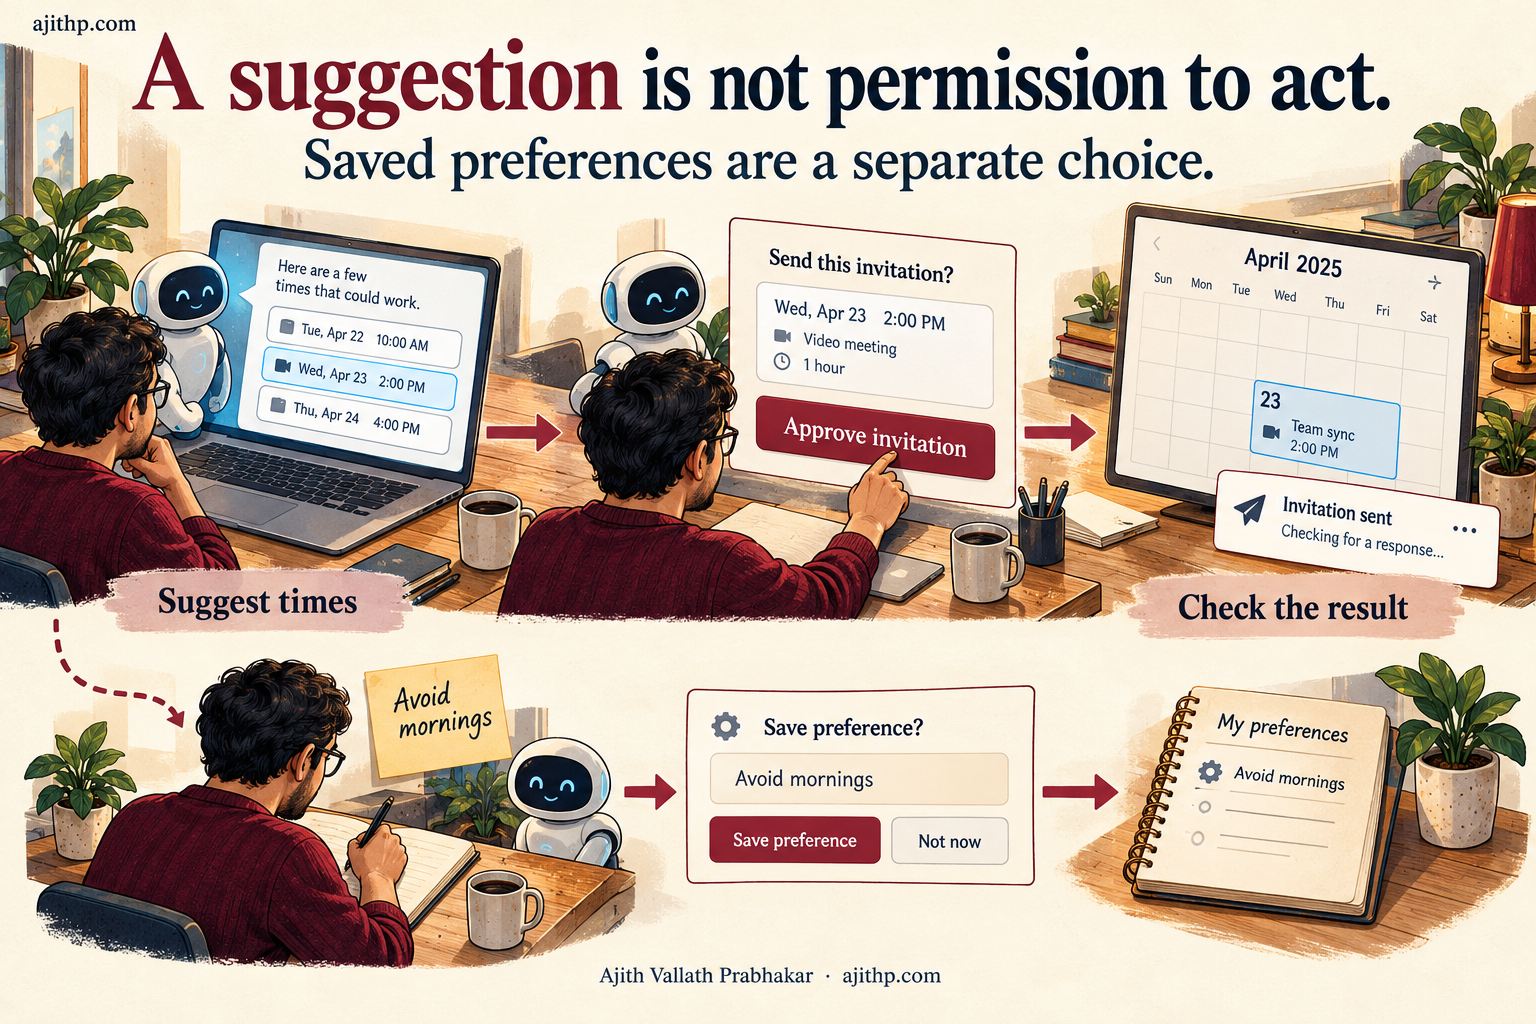
A calendar assistant can suggest three times for a meeting. Give the same software permission to book one, send invitations, and move an existing appointment, and the design question changes: what may it do without asking, and how will a person notice or reverse a mistake?
I use agentive AI in this article for AI designed to work in relation to a person, supporting a goal while leaving room for human direction. That is broader than Christopher Noessel’s 2017 framing in Designing Agentive Technology, which describes systems that do things directly for their users. In his 2026 Designing Assistant Technology FAQ, Noessel asks readers to distinguish assistants from agents and describes agentic backends and agentive front ends as related but different. Contemporary usage still varies; neither account supplies a universal taxonomy (Rosenfeld Media, Designing Agentive Technology; Noessel’s 2026 FAQ).
Collaboration, personalization, and human oversight remain useful ways to frame the interaction. A friendly interface does not tell us how a system works behind it. A tool may answer a question, suggest a next step, follow a fixed sequence, or let a model choose tools and actions as it goes. The distinction becomes important when an AI moves from producing information to changing a calendar, sending a message, modifying a record, or affecting a decision.
A practical comparison should therefore describe what a system is allowed to do in a particular setting. The table keeps the six dimensions from the 2024 version while replacing a fixed “agentive versus autonomous” split with a range of design choices. Many real systems combine the patterns in different rows.
| Design dimension | Human-directed pattern | More autonomous pattern | Question to settle for the use case |
|---|---|---|---|
| Human involvement | A person provides direction and reviews suggestions or actions. | The system may proceed through several steps with limited intervention. | Which steps need review, and what events must stop the system for a person? |
| Decision-making | The system presents options or a recommendation; a person makes the consequential choice. | The system selects among options within a defined task and policy. | What decision authority is delegated, and which decisions remain with an accountable person? |
| Control | The person can change instructions, deny an action, or stop the system. | The system has temporary authority to act within a bounded set of tools and permissions. | What can it read or change, and how can a person intervene or reverse an action? |
| Learning or adaptation | The product may use a current request or explicit preferences without retaining them. | The product may preserve state, update a profile, or change model weights when deliberately configured to do so. | At either autonomy level, what changes after feedback, where is it stored, and how can it be inspected or removed? |
| Examples | A support assistant drafts a response for an employee to review; a clinical reference tool summarizes evidence for a clinician. | A system schedules a routine appointment under preapproved conditions or executes a bounded workflow. | Is this example a recommendation, a fixed workflow, or model-directed action? |
| Interaction | The person stays in the loop throughout the task. | The system may handle routine steps and return at a checkpoint or when it reaches a limit. | What does the person see before, during, and after the system acts? |
This is a design aid, not a standard taxonomy. Anthropic’s discussion of agentic systems distinguishes workflows, where code directs the path, from agents, where the model directs its process and tool use. OpenAI’s guide similarly describes agents in terms of a model working with instructions and tools under guardrails. Those are current architectural descriptions; neither defines every system that might be called an agent (Anthropic, “Building Effective Agents”; OpenAI, “A Practical Guide to Building AI Agents”).
Historical Context and Technical Foundations
AI systems have been built using different methods across different periods: rule-based programs were prominent in early work; expert systems later encoded specialist knowledge as rules; statistical machine learning became more widely used as data and computing improved; and deep learning expanded the range of tasks neural networks could handle. This is a simplified history, not a clean handoff from one era to another. Today’s products may combine rules, conventional software, search, machine learning, and generative models.
The 2024 article described agentive systems as a combination of learning, language, and context. That remains a useful starting point for discussing some products, but it should not be read as a required recipe. A tool can respond to natural-language instructions without learning from a user, and it can adapt to a context without being allowed to take an action. The rest of the design matters as much as the underlying model.
The Evolution of AI
A compact timeline can orient the discussion: rule-based systems in the 1950s and 1960s; expert systems in the 1970s and 1980s; machine learning in the 1990s and 2000s; and deep learning from the 2010s onward. Each label covers a broad family of methods, and none replaced everything that came before it; current systems still rely on rules, databases, statistical models, and ordinary software alongside newer models.
The more useful question for a product team is what the system can sense, infer, remember, and change. Those capabilities vary by implementation. The name “agentive” does not guarantee that an application understands a request, has reliable context, learns from feedback, or can safely act.
Key Technologies Enabling Agentive AI
Several technologies can contribute to an AI system that supports people. They solve different problems and carry different limits.
Natural language processing and language models let a person express a request in ordinary language. A model can interpret the text and produce a response, but fluent wording does not prove that it understood the intended task or selected a safe action. Critical requests still need clear constraints, validation, and a way to ask for clarification.
Reinforcement learning and feedback can improve a policy through rewards or other signals; it is one specific learning approach, not what happens whenever a person accepts or rejects a suggestion. Feedback could change the current conversation, a saved preference, a recommendation model, or a later training set, and each mechanism needs explicit design. Personalization, persistent memory, and model-weight updates are different operations. For example, OpenAI describes ChatGPT memory as a personalization feature with controls separate from model training. For personal accounts, however, chats and remembered information may be used to improve models when “Improve the model for everyone” is on; OpenAI says content from Business, Enterprise, Edu, and ChatGPT for Healthcare workspaces is not used for training by default. Its fine-tuning API separately documents creating a training job using a dataset. Those product-specific examples illustrate why “the system learns from you” is too broad a description (Memory in ChatGPT; Create a fine-tuning job).
Context-aware computing may use information such as time, location, recent activity, or a person’s stated preferences. A home assistant might use the time of day to decide which lighting suggestion to make. That does not make every context appropriate to collect or retain. A team should identify the data it needs, explain its use, control access, and decide what happens when context is missing or stale.
Knowledge graphs represent entities and their relationships. They can help a system retrieve connected information when the graph is accurate and relevant to the task. A graph alone does not make the information complete or a recommendation correct; its coverage and sources still matter.
Multimodal models can process more than one kind of input, such as text, images, or audio. This can make some interactions more accessible or let a system work with material that text-only software cannot handle. Multimodal input is a model capability. Planning, tool access, persistent state, and authority to act are separate design choices.

How Agentive AI Works
The flow below is one simplified way a system might handle a task. Some applications use only a few of these steps; a model-directed agent may choose and repeat steps as it works. The diagram is an illustration, not a description of every system.
- Input reception. The system receives a request, command, or goal from a person or an authorized event.
- Context analysis. It considers the information available for this task, such as relevant records or stated preferences. Context should be limited to what the system is authorized to access and current enough for the decision.
- Task planning. For a multi-step task, the system or its surrounding software identifies subtasks and determines a path. A simple request may not need a separate planning stage.
- Action suggestion. The system returns information or proposes the next step. A recommendation is not the same as an action, and its uncertainty or missing evidence should be visible where that matters.
- Human review and feedback. The person can approve, modify, or reject a proposed step when review is required. The product should make clear which actions can proceed without approval and when a person must be asked.
- Execution. The system uses only the tools and permissions granted to it. Consequential actions may require confirmation; the workflow should record what happened and have a defined failure, stop, and recovery path.
- Feedback and adaptation. Feedback may change the current interaction. It changes later behavior only if the product is designed to store a preference, update another component, or train a model. Those mechanisms are different and should not be assumed from a single interaction.
A useful flow also needs boundaries that are not visible in a simple diagram. The team should limit the tools and records the system can access, define actions that require confirmation, log decisions and tool results, set a timeout and failure path, and provide a stop or rollback method. These controls help people understand what happened; they do not guarantee that the system will be correct.
Applications of Agentive AI
The examples below describe possible uses, not proof that an AI system has produced better outcomes. Some are recommendation tools; some might be fixed workflows; others could be model-directed systems. The word “agentive” does not settle which one is being described.
Business Automation
A customer relationship management system might identify accounts that need attention and draft a follow-up for an employee to review. In human resources, software could help schedule interviews or assemble onboarding materials. A supply-chain team might use a forecasting tool to surface demand changes or possible disruptions.
Each example depends on the quality and freshness of its inputs. Scheduling an interview is different from ranking candidates. A demand forecast is different from changing purchase orders. The more a system can alter records, contact people, or commit money, the more carefully its authority and exception handling should be defined.
Healthcare
AI can help clinicians locate information, summarize a patient record, or compare a case with relevant evidence. Those tasks need validation in the intended clinical context. A system that provides a recommendation for a clinician is also different from software that supplies a diagnosis or treatment directive. Under the FDA’s January 29, 2026 final Clinical Decision Support Software guidance, whether a software function is excluded from the medical-device definition or remains under device oversight depends on the function and applicable criteria; a general label such as “decision support” is not enough to decide the question (FDA Clinical Decision Support Software Guidance).
Personalized treatment discussions require particular care. A language model may summarize research, but it can omit relevant evidence or produce inaccurate statements. A clinician needs enough information about intended use, relevant performance, limitations, and the patient-specific context to decide what weight to give the output. The FDA, Health Canada, and MHRA’s transparency principles emphasize communication that helps the human-AI team understand a device’s intended use, performance and limitations (FDA, Transparency for Machine Learning-Enabled Medical Devices).
Predictive analytics may identify patterns for review, but a risk score is not a diagnosis and does not establish what will happen to an individual. Patient monitoring and treatment decisions also depend on data quality, population fit, clinical workflow, and applicable regulation. This article does not offer medical advice.
Finance
An investment platform can use a person’s stated goals and risk preferences to present portfolio options. A fraud system can flag unusual transaction patterns for an analyst. A planning tool can help someone compare how different assumptions affect a household budget.
These examples cover a wide range of authority. Presenting a forecast is not the same as placing a trade or transferring funds. Any system acting on accounts needs clear permission boundaries, records of what it did, a way to correct errors, and appropriate review. A recommendation also needs context about its assumptions and limits.
Retail and E-commerce
A shopping assistant may use browsing or purchase information to rank products. Inventory software can forecast demand and offer stock suggestions. A visual tool may let a customer see how an item could look in a room or on a person.
Personalized recommendations and virtual try-on are not automatically agentic. They may involve retrieval or image generation without a planning loop or action authority. If software changes prices, places orders, or modifies inventory, those actions should be considered separately from the quality of its suggestions.
Creative Industries
Designers may ask a model to produce variations on a layout. A musician may use a tool to suggest a chord progression. An author may ask for a first draft, alternate phrasing, or help reorganizing a piece.
These uses can give a person more material to consider. The value depends on the creative goal, the quality of the source material, and the person’s judgment about what to keep. Content generation by itself does not make a system an agent; the system’s access to tools and ability to pursue tasks are separate questions.
A hypothetical clinical decision-support workflow
The workflow below is hypothetical. It shows one way a clinician-support system might organize information for review; it reports no deployment or clinical outcome.
Background
Imagine a clinician reviewing a complex case and using software to gather relevant items from a patient’s record and trusted clinical references. The system could organize the information or show options for the clinician to examine. This is a design scenario, not an account of a hospital deployment.
Implementation
Before such a system could be used, its intended purpose, input sources, access permissions, data quality, evaluation method, and clinical workflow would need to be specified. “Anonymized” data should not be used as a blanket privacy assurance; privacy and security controls depend on what data is available, how it is processed, who can access it, and what can be inferred or linked.
The system would need evidence from the relevant population and setting. Evaluation should address omissions and errors as well as average performance, and should identify cases where the software is not suited to provide support. Regulatory status also needs to be assessed for the particular software function, intended use, and market.
Process
A possible workflow would begin with a clinician entering or reviewing the patient’s relevant information. The system could search approved references, summarize points that may apply, and present uncertainties or missing data. It might suggest questions or additional tests for the clinician to consider. The clinician would interpret those suggestions, consult the patient, and make the clinical decision. If the system cannot support its output with the required information, it should say so and leave the decision with the clinician.
What the example does not establish
This hypothetical says nothing about diagnostic accuracy, fewer tests, patient outcomes, administrative time, regulatory clearance, or clinical benefit. Those conclusions require a real study or product record with a defined population, comparison, method, and results. The clinician’s review is part of the proposed workflow; it is not a substitute for evidence that the software is fit for its intended use.
Benefits of Agentive AI
A system designed around human goals may help people handle information or routine steps while keeping consequential decisions visible. That is the strongest case for the approach. It depends on the work being delegated and on whether the person can inspect and correct the system’s contribution.
Five potential benefits follow from this human-directed design:
- Support for human capability. A system can surface information or options that help a person decide what to do next. Whether the assistance improves a decision must be evaluated in context.
- Routine-task assistance. Software may take over repetitive steps, leaving a person to focus elsewhere. That can reduce effort in one part of a workflow, but total value depends on review burden, corrections, integration, and support costs.
- Relevant context. A system can adapt an answer to a user’s stated preferences or current situation when it has appropriate context. The data should be visible and controllable.
- Use across different settings. Similar patterns can be applied in multiple sectors, but each deployment requires its own data, permissions, evaluation, and failure handling.
- Adaptation where designed. Some products preserve preferences or use feedback to adjust later behavior. Others do not. A team should say what is being stored or updated and how a person can inspect or change it.
These benefits are reasons to test a use case. They are not outcome claims. It is also possible for a human-reviewed workflow to be slower than a direct automated path. For a bounded, reversible task, asking a person to approve every small step may add friction without meaningful protection. The approval point should follow the stakes, the available controls, and the cost of an error.
Challenges and Ethical Considerations
The same system that acts on someone’s behalf may need access to sensitive information and permission to change things. That makes its data and authority part of the product design, not a secondary policy question.
Data Privacy and Security
Personalization and context can require sensitive information. That raises practical questions: who controls the data, how it is used, and what happens if the system is compromised? These questions remain central to the design.
A product team should identify which information is necessary for the task, who can access it, how long it is retained, and whether it may be sent to another service. A system should receive only the permissions it needs. Actions should be logged where appropriate, and users should be able to distinguish a proposed action from a completed one. These controls lower exposure; they do not remove all risk or establish legal compliance by themselves.
Bias and Fairness
A recommendation system can reproduce or amplify patterns in its data and design. In hiring, a tool might prioritize candidates according to traits that reflect historical decisions. In criminal justice or other public decisions, errors may affect people who have limited ability to challenge them.
Training on more varied data can help address gaps, but it is not enough by itself. Teams need to define the decision and affected groups, examine data coverage, evaluate outcomes for relevant populations, monitor use, and provide a way to contest or correct consequential results. A test should match the setting in which the system will be used. “Fairness” is not a single score that settles the question.
NIST’s AI Risk Management Framework offers a voluntary way to organize work across governance, mapping, measurement, and management. NIST describes trustworthiness characteristics such as validity, safety, security, transparency, explainability, privacy, and fairness as context-dependent considerations. The framework is not a law, certification, or guarantee (NIST AI RMF).
Transparency and Explainability
People need enough information to decide whether an output is useful and what to do if it is wrong. That may include what the system is intended to do, which data it used, what it could not access, how well it was evaluated, and the situations in which its output should not be relied on.
An explanation written in plain language does not prove that the system’s internal reasoning followed that explanation. In high-stakes settings, transparency must include observed performance and limits, not just a polished account of why a result sounds plausible. The person responsible for the final decision should know which parts came from the system and which were independently verified.
Over-Reliance on AI
People may give a confident answer too much weight, especially when a system performs well on routine work. The risk grows when users cannot see what information it considered or how it reached a recommendation.
Human oversight is useful when the person has enough time, authority, and information to make a different decision. A nominal approval step will not help if review is rushed or the user cannot inspect the evidence. Products should identify when to escalate, let users override or stop actions, and provide a fallback when the system is unavailable or uncertain.
Job Displacement
Automation can change tasks and the skills people need. Some work may shrink, while other work may shift toward setting goals, evaluating outputs, managing exceptions, or maintaining systems. The direction and scale of those changes depend on the job, organization, and adoption choices.
The available material in this article does not support a forecast about how many jobs will disappear or which new roles will appear. The practical question for an organization is how it will measure work that changes, involve employees in the redesign, and provide training where expectations shift. Reskilling is part of the response, not proof that job losses will be offset.
The Role of Generative AI and LLMs in Agentive AI Adoption
When this article was first published in February 2024, generative AI and large language models had brought natural-language interaction into many public discussions of AI. They made it easier to ask for a summary, a draft, or a sequence of steps without first learning a specialized interface. That helped make human-AI collaboration easier to imagine.
The connection should still be described carefully. An LLM can produce language or other outputs, but an application determines what context reaches the model, what tools it can use, what happens after an answer, and who can approve an action. An LLM may be part of an agentic system, but the model alone does not provide a workflow, safe permissions, reliable memory, or accountability.
Impact of Generative AI on Agentive Systems
Generative models can make some interactions more flexible because a user can describe a request in their own words. They may produce contextual responses or help a person explore alternatives. They can also misunderstand, omit important details, or return plausible but incorrect information. A natural interface needs verification and clarification paths, especially when a response leads to an external action.
The same flexibility can make the system useful across tasks, provided the application has appropriate tools and constraints. “Creative problem-solving” is a description of a possible use, not evidence that the model found a sound solution. A person still needs to evaluate what the system proposes, and a product must check that its actions match the request.
Large Language Models as one component
An LLM can synthesize information from text provided to it or found through connected tools. That is different from guaranteeing that the model’s learned information is current, complete, or appropriate for a particular decision. Retrieval can supply additional sources, but the system needs to identify them and handle conflicts or gaps.
Fine-tuning can shape a model using a dataset. Other products may personalize a response by retrieving a stored preference or including relevant conversation context. These approaches have different privacy, reliability, and update properties. Describing all of them as an AI that “learns your preferences” hides the difference.
An LLM can support decision-making by organizing information or proposing options. The person making the decision needs to know the limits of the system and should not mistake a fluent answer for independent validation. Multimodal models can extend which inputs and outputs are available; they do not automatically give the product permission to act on them.
Why adoption may accelerate
Pretrained models and hosted tools can lower the technical effort required to test an idea. Natural-language interaction can let more people try a workflow. A team can prototype a connection among documents, applications, and business steps without first building every component from scratch.
Those are plausible mechanisms, not evidence that organizations have adopted the systems at a particular rate or trust them more. A prototype shows that an idea can be demonstrated. It does not establish that the system is accurate, secure, maintainable, cost-effective, or suitable for production. The integration, review, and support work still has to be done.
An example of coding assistance: GitHub Copilot
GitHub Copilot offers a dated example of generative AI assisting a developer. In 2024, code suggestions illustrated how an AI tool could offer code while a person worked in an editor. Current GitHub documentation describes inline suggestions, repository-context Copilot Chat, and separate cloud-agent capabilities. These are not the same level of autonomy, and current functionality should not be projected backward onto the 2024 example (Copilot code suggestions; repository indexing; Copilot agent concepts).
The tool’s suggestions may help a developer move through a familiar task, but a suggestion may not fit the project or meet its security and quality requirements. Repository context may help produce more relevant responses; it does not replace code review, tests, or a developer’s responsibility for the change. Neither repository context nor code completion establishes that the 2024 product learned each developer’s style over time or produced a measured productivity gain. GitHub now separately documents Copilot Memory, a public-preview feature that can retain repository facts and user preferences for supported Copilot features. That current, stored context is distinct from the 2024 code-suggestion example; its presence does not by itself show that model weights are retrained on an individual developer’s work (Copilot Memory).
Future Implications
In 2024, I expected generative AI and large language models to deepen collaboration, extend creative support, improve decision support, and bring more attention to ethical use. Looking at those expectations now calls for a distinction between a capability that can be demonstrated and an outcome that has been established in a particular setting.
- More sophisticated collaboration. A model can now participate in workflows that involve several steps and tools. The design question is still which steps it may choose, what information it can use, and when a person must review or take over. More steps do not make collaboration better by themselves.
- Creativity support. A model can offer drafts, alternatives, or iterations in writing, design, and other creative work. That can help a person explore a direction, but the creator still decides what belongs in the finished work and must consider the provenance and rights of the material.
- Decision support. A system can summarize information or present options, but the quality of that help depends on the evidence, context, and decision being considered. Accuracy and usefulness need to be evaluated in the intended setting; fluent synthesis alone does not establish better decisions.
- Ethical use. As systems gain access to more data and tools, questions about privacy, fairness, transparency, and accountability become harder to separate from product design. Policies and frameworks can organize that work, but they do not replace evidence, oversight, or a clear owner for consequential decisions.
The connection among generative models, LLMs, and agentive systems is most useful when we describe what each contributes. A model can make language and other outputs more flexible; an application supplies context, workflow, tools, and permissions; people decide what authority to delegate and remain responsible for the results. That combination can make human-AI interaction more capable, but only the design and evaluation of a particular use can show whether it is more useful.
The Future of Agentive AI
The 2024 article also looked ahead to how systems might be used in daily life, collaboration, and governance. Those possibilities remain scenarios to evaluate, not outcomes guaranteed by the technology.
The important design variables are becoming clearer: what goal is the system pursuing, what data can it access, which tools can it call, what authority has been delegated, and how does a person intervene? Systems can differ on each of these points. Calling all of them “AI assistants” obscures the decisions that matter.
Deeper Integration into Daily Life
A smart-home system might adjust lighting or heating based on a person’s preferences. A health product might help someone record symptoms or prepare information for a clinician. Each scenario depends on dependable inputs and clear user controls. A home action should be easy to inspect or reverse; a health recommendation needs evidence and a defined clinical role.
The availability of data does not mean that a system should collect it. Location, activity, and health information deserve limits on use and retention. People should know what the system will do automatically and how to turn that behavior off.
Advanced Human-AI Collaboration
In research and development, AI may help organize literature, summarize large datasets, or generate hypotheses for human investigators to test. A generated hypothesis is a suggestion, not a scientific finding. Researchers still need to check data, methods, and reproducibility.
In creative work, models can provide options that help a person move past a blank page or explore directions they would not have tried. The artist, designer, or writer decides what belongs in the final work and must consider the provenance and rights of the material they use.
Ethical AI and Governance
Responsible use depends on the system, the people affected, the task, and the authority granted. A governance process should identify the owner, define acceptable use, record the evidence used for approval, monitor failures, and change or stop the system when assumptions no longer hold.
NIST’s AI Risk Management Framework is one voluntary US reference for organizing risk work. The EU AI Act became applicable on 2 August 2026, but some obligations have later dates: following the AI Omnibus, high-risk use cases under Annex III are scheduled for 2 December 2027 and high-risk systems embedded in regulated products under Annex I for 2 August 2028. Which requirements apply depends on the system’s purpose and legal classification; a general AI label cannot answer that question (European Commission, AI Act overview; EUR-Lex, consolidated AI Act text).
Conclusion
The useful promise in agentive AI is the chance to bring software closer to a person’s goals. That promise is easiest to see when the system can gather information, surface an option, or take a routine step within clear limits. The same system becomes harder to trust when its authority, sources, or failure behavior are unclear.
A person should not have to approve every trivial action. A system should not take consequential action simply because it can. The right boundary depends on what can go wrong, how quickly someone can notice it, and whether the action can be reversed. Those decisions belong in the design, the permissions, and the way the product is evaluated.
“Agentive” remains a useful lens for thinking about technology designed around people. Current agentic systems add questions about models that plan and use tools. Keeping those ideas distinct lets us discuss both the user’s experience and the system’s authority without treating a friendly interface as evidence that the system is safe.
Discover more from Ajith Vallath Prabhakar
Subscribe to get the latest posts sent to your email.