Quick brief
Choose an explanation method for a specific question and audience, then test whether its account is faithful, understandable and useful for that decision. Feature attribution, an actionable counterfactual, model validation and legal compliance answer different questions, so evidence for one cannot stand in for the others.
Full analysis
Revised October 18, 2026.
A loan applicant receives a rejection accompanied by a chart. Income appears as a red bar, credit history as a blue one, and a short paragraph explains the result. The chart might faithfully describe the model’s output. It still leaves several questions open: whether the input record was correct, whether the decision complied with policy and whether the applicant has a realistic way to challenge it.
That distinction is the starting point for explainable AI. An explanation can make a model easier to inspect, expose a suspicious dependency or help someone decide when to ask for review. A persuasive account can also make a weak decision easier to accept. I would evaluate explanation quality separately from the quality of the decision it accompanies.
The four principles in NISTIR 8312, published in 2021, provide a useful foundation: a system supplies an explanation, that explanation is meaningful to its audience, it accurately reflects the system’s process, and the system recognizes its knowledge limits. An understandable answer can fail the accuracy principle. A technically accurate attribution can fail to help the person who must act on it.
What explanations can contribute to a decision
Trust should follow evidence
In an illustrative medical-image workflow, a highlighted region can direct a clinician’s attention to something worth investigating. It does not establish that the model identified the right pathology or used clinically valid reasoning. Compare the highlight with independent clinical evidence and assess how the clinician uses it. A brighter heatmap is not evidence of a better diagnosis.
For a credit decision, the applicant may need accurate reasons and a route to correct data. The model developer needs a different account, perhaps showing an unstable feature dependency. A vehicle engineer investigating sudden braking may need perception outputs, sensor conditions and the control trace; a passenger needs an intelligible account of the event. One explanation interface cannot satisfy all of these distinct jobs.
The same problem reaches clients and partners in business-to-business work. If a supplier challenges an AI-assisted risk rating, the buyer needs to identify the records, criteria and version used, while giving the supplier a useful explanation without exposing another organization’s confidential information. A reassuring summary leaves that dispute unresolved unless it also gives the supplier a route to question the evidence.
There is a real cost to demanding more detail. A complete trace can overwhelm a reviewer, expose confidential information or arrive too late for the decision. The practical objective is enough faithful information for the intended task, with access to deeper evidence when it is needed. More disclosure is not automatically more useful.
Regulatory duties need their actual scope
The EU AI Act contains distinct obligations rather than a universal requirement to explain every AI system in the same way. Article 13 addresses transparency and information for deployers of high-risk systems; Article 14 addresses human oversight. Article 86 provides a specifically scoped right to explanations for certain significantly affecting decisions based on Annex III high-risk systems, with exceptions. Classification, operator role and applicable provisions matter before selecting an explanation artifact.
The dates matter too. Under the July 2026 Digital Omnibus amendment, Chapter III, Sections 1–3, apart from Article 6(5), apply from 2 December 2027 for Article 6(2)/Annex III systems and 2 August 2028 for Article 6(1)/Annex I systems. Those dates concern the specified high-risk rules; do not automatically apply them to Article 86 or treat the Act’s different duties as one implementation deadline.
Under the GDPR, meaningful information about the logic involved in relevant automated decision-making sits alongside other information and safeguards. In Dun & Bradstreet Austria, C-203/22, decided on 27 February 2025, the Court required an account of the procedure and principles actually applied that lets the person understand which data were used and how. Merely supplying an algorithm does not meet the intelligibility standard. When the controller claims protected third-party information or trade secrets, the supervisory authority or court must receive that information and balance the interests involved.
The FDA example also needs care. Its 29 January 2026 Clinical Decision Support guidance explains criteria for certain software functions excluded from the device definition. Enabling a health professional to independently review a recommendation’s basis is one criterion, not a universal rule that every medical AI must expose its internal reasoning. The FDA’s current FAQ also explains why failing an exclusion criterion does not by itself settle whether a function is a regulated device.
These examples show why an explanation tool belongs inside a wider evidence process. A SHAP plot is not proof that the relevant duty has been met. Identify the affected person, intended use, decision, applicable rule and required record, then determine which technical and organizational evidence is needed.
Bias, debugging and collaboration require follow-through
Feature attribution can suggest that a hiring model relies on a geographic variable. That is a reason to investigate proxy relationships and group outcomes; attribution alone cannot establish discrimination or demonstrate that removing the variable fixes it. A counterfactual can show a model boundary without proving that crossing it is fair, feasible or legally appropriate.
The same discipline helps debugging. A model that appears to depend on a patient identifier may have learned a shortcut. An explanation makes that hypothesis visible. Test it by examining the data pipeline, checking for leakage and evaluating an appropriate intervention on held-out data. Changing the feature because its bar looked large is an incomplete investigation.
Explanations can also support feature engineering and model selection. They can reveal which information deserves better collection, or why a seemingly stronger model behaves poorly on cases that matter. Compare these observations with predictive performance; neither a convenient explanation nor a good aggregate score should close the decision by itself.
In medical practice, scientific hypothesis development and education, the useful question is what the person can do better with the explanation. Can the clinician spot an error, the researcher design a discriminating experiment, or the teacher understand a mistaken assessment? Measure those outcomes. Making people more confident is a different result from improving their decisions.
Accountability remains organizational. Someone must own the data, the model’s permitted use and the decision process. An explanation can support public scrutiny and an incident investigation, but a technical attribution does not assign responsibility for a harmful deployment.
Model-agnostic explanations and counterfactuals
Model-agnostic methods use the relationship between inputs and outputs without requiring a particular internal architecture. In practice, they still need suitable model access, meaningful input transformations and enough evaluation budget. “Model-agnostic” describes the dependency on model internals; it does not remove assumptions about data or interpretation.
LIME: approximate the neighborhood of one prediction
LIME, introduced by Ribeiro, Singh and Guestrin in 2016, fits an interpretable surrogate around an instance. Its purpose is local explanation, so the neighborhood and the simpler representation are substantive choices.
The basic procedure is to select an instance; create perturbed examples in an interpretable representation; query the original model; weight examples by proximity to the instance; and fit a constrained, interpretable surrogate. Inspecting that surrogate gives an approximate account of the original model’s local behavior.
For text classification, the representation may indicate which words are present. For an image, perturbations can operate on superpixels. A symptom-based clinical example can illustrate the same procedure, but it does not validate a diagnostic system. Removing words or image regions may create inputs unlike the data the original model normally sees.
The attraction is a compact explanation that can be inspected across different classifiers. Its limits include sensitivity to sampling, representation and neighborhood settings, and lack of a global account. Check local fit and stability rather than assuming faithfulness because the method produced a chart.
SHAP: allocate a prediction difference under stated assumptions
SHAP, introduced by Lundberg and Lee in 2017, connects additive feature attribution to Shapley values. For a specified explanation setup, contributions allocate the difference between the explained output and a reference value.
Conceptually, consider feature coalitions, define the model output when a coalition is available, calculate each feature’s marginal contribution and combine those contributions with Shapley weighting. Exact enumeration is expensive; implementations exploit model structure or approximation. The reference distribution and treatment of missing or dependent features affect the question being answered.
The additive account must identify its output scale. Contributions that add up in a log-odds explanation cannot simply be presented as probability-point changes. Aggregating magnitudes over many instances can describe a population pattern, but it can hide opposing directions and subgroup differences.
Credit, customer-churn and patient-risk models are useful illustrative applications. A theoretically grounded allocation is still not a causal effect or a fairness finding. Interaction analyses require their own specification. Record the explainer, background data and output definition alongside the visualization so another analyst can reproduce the account.
Counterfactual explanations: a changed prediction needs a feasible change
Counterfactual methods search for alternative inputs that change a prediction while satisfying a defined notion of proximity and other constraints. They can be model-agnostic or exploit model structure. The counterfactual-explanation research by Wachter, Mittelstadt and Russell, first posted in 2017, is an important starting point for the distinction between an account of a decision and possible changes to an outcome.
A procedure starts with an instance and target outcome, specifies allowable changes and a distance or cost, then searches for a candidate that the model assigns to the target. Verify that candidate against the same model version and check feasibility before presenting it.
An illustrative statement such as “an additional $5,000 of annual income would cross this model’s threshold” concerns a conditional model calculation. It does not promise a future loan approval. Income may affect other variables, records may change and the policy may have additional conditions. Immutable attributes, unrealistic combinations and unaffordable changes make a mathematically close counterfactual poor advice.
The benefit is a concrete what-if question that a person may understand more readily than an attribution. Evaluate whether the proposed action is genuinely available and whether the system provides a way to contest incorrect data or an inappropriate decision.
Model structure provides other forms of evidence
Tree importance and permutation importance answer different questions
In a tree ensemble, mean decrease in impurity aggregates reductions associated with feature splits. It is inexpensive to inspect because the fitted structure already contains the relevant quantities. It can favor high-cardinality features and describe training-fit patterns rather than held-out usefulness.
Permutation importance instead measures the change in a chosen performance score after shuffling a feature on an evaluation set. It is model-agnostic, not confined to trees. The scikit-learn documentation also explains how correlated features can make individual permutation importances deceptively small because related information remains available elsewhere.
For an illustrative customer-segmentation model, first define the evaluation objective: a classifier’s accuracy and a clustering criterion are not interchangeable. Report the dataset and score used. Structural importance, predictive dependence under perturbation and causal importance remain different statements even when each is drawn as a ranked bar chart.
Attention weights need a fidelity test
Attention mechanisms compute weighted combinations of representations. Visualizing weights can help inspect how a sequence model distributes attention, including in translation or summarization. A weight chart does not automatically show which original input caused a prediction.
Jain and Wallace's 2019 study found settings where attention distributions diverged from other importance measures and different distributions produced similar predictions. Wiegreffe and Pinter's response challenged parts of the experimental argument and proposed more careful tests. The useful lesson is to define and evaluate the explanatory claim rather than decide it from the visualization alone.
In a sentiment example, highlighted words may be worth investigating. Validate whether the model’s behavior changes as the proposed explanation predicts, with transformations meaningful for the task. Neither a colorful attention map nor a universal dismissal of all attention analysis supplies that validation.
A language model’s own explanation needs independent checks
Asking a language model why it answered a question produces another model output. In Turpin and colleagues' 2023 experiments, biasing features in prompts influenced GPT-3.5 and Claude 1.0 answers without consistently appearing in their chain-of-thought explanations. The result concerns those tested models and tasks; it supports checking faithfulness rather than treating a fluent rationale as a reliable account of every influence on an answer.
Suppose an assistant says it used the current refund policy. Before accepting that account, compare it with the retrieved document version, the input actually supplied and any recorded tool result. Those records can test the specific claim about access and inputs; they do not reveal every internal cause of the model’s answer. A generated explanation can help a person understand a recommendation, but it should point them toward evidence they can inspect, especially when the answer affects an action.
Layer-wise relevance propagation: redistribute a chosen output
Layer-wise relevance propagation, described by Bach and colleagues in 2015, decomposes a classifier output back through the network. Start with the chosen output, redistribute relevance to the preceding layer according to a selected rule, and repeat until relevance reaches input features.
In an image-classification example, the result can show pixel-level relevance for a class. Different propagation rules and stabilization choices matter. Conservation is a design property under the chosen rules; stabilizers and bias handling can absorb or redistribute relevance, so it should not be stated without qualification.
LRP is not simply a reversed prediction or an ordinary gradient. Its value is a structured decomposition that can be examined for suspicious dependencies. The resulting heatmap still needs task-specific checks; it cannot by itself establish that a highlighted object is clinically meaningful or causally responsible in the world.
Integrated Gradients: the baseline defines the comparison
Integrated Gradients, introduced by Sundararajan, Taly and Yan in 2017, attributes a differentiable model output relative to a baseline input. Along the straight-line path from baseline to input, it integrates gradients and scales each by the feature difference.
The practical sequence is to select a meaningful baseline and output, choose integration points, compute gradients along the path and approximate the integral. Completeness relates the summed attributions to the output difference under the method’s conditions; numerical approximation introduces its own error.
A zero vector can be useful for a particular representation, but it is not a universal neutral input. Baseline choice can change the interpretation substantially. The method’s axiomatic motivation, including sensitivity and implementation invariance, helps distinguish approaches; it does not prove that an attribution is a causal account or that its user will interpret it correctly.
Intrinsic models make the decision function inspectable
Interpretable-by-design models allow inspection of their prediction rule without first fitting a post-hoc surrogate. This can remove one source of mismatch between the model and an explanation. Interpretability still depends on model size, feature meaning and the person doing the inspection.
It is tempting to assume that choosing an interpretable model necessarily sacrifices accuracy. Rudin's argument for interpretable models in high-stakes decisions challenges that presumption. Test the alternatives on the task. A complex model may earn its extra burden, but it should not receive that preference before comparison.
Decision trees
A decision tree applies feature tests along a path. Internal nodes contain tests, branches select outcomes of those tests and leaves provide predictions. A compact tree can make the path for a single case easy to inspect.
Its useful properties include visible thresholds and explicit branching. Trees can work with numerical features and appropriately supported or encoded categorical data; the exact treatment depends on implementation. Pruning and other complexity controls help address overfitting.
A tree with hundreds of branches can be difficult to understand, even though every split is accessible. Inspecting one path does not reveal all the other paths or establish that the training population remains representative. Use a tree’s actual size and stability in the interpretability assessment rather than the model-family label alone.
Linear models
Linear regression expresses a prediction as an intercept plus weighted input features. Binary logistic regression maps a linear score to a predicted probability through the logistic function, the inverse of the logit link. Linear discriminant analysis is another classification approach with its own statistical assumptions; these models should not be treated as one identical procedure.
Coefficients support a direct account of the fitted score when units, encoding and transformations are known. A coefficient on income measured in dollars is not comparable by magnitude with one on an indicator variable without considering scale. In logistic regression, a coefficient acts on the log-odds score, not directly as a probability change.
A general requirement that all predictor variables be statistically independent would be misleading. Collinearity can make coefficients unstable or non-identifiable, and inferential assumptions depend on the estimator and objective. Linear models also support engineered nonlinear features, so “cannot model nonlinearity” is too absolute. The practical question is whether the resulting function remains understandable and generalizes adequately.
Rule-based systems
Rules express conditions and consequences, commonly as IF-THEN statements. They may come from expert policy, learning procedures or a combination. An ordered rule list applies a particular precedence; other systems use different conflict-resolution strategies.
Rules can make a policy condition explicit and easier to update. They also accumulate exceptions. A large rule base with overlapping conditions can be harder to reason about than a compact statistical model, especially when different owners change different parts.
Test conflicting conditions, missing inputs and default behavior. The fact that an individual rule is readable does not establish that the complete system behaves correctly. Preserve the version and precedence that produced a decision so an explanation can identify the rule actually applied.
Generalized additive models
A basic generalized additive model combines an intercept and component functions of individual features on a specified link scale. A smooth function can represent a nonlinear relationship without requiring a separate rule for every interval. Plotting each component helps show the fitted relationship.
The additive structure is the source of both its usefulness and its limits. A base model does not capture arbitrary interactions merely by making its individual curves flexible. Extensions can include explicit interaction terms, which then need their own interpretation. The original GAM work by Hastie and Tibshirani provides the statistical foundation.
Individual plots can be inspected separately, but correlated inputs and sparse data regions still affect what can reasonably be concluded. A smooth curve outside well-supported data should not become confident advice. Compare predictive performance and uncertainty as well as the apparent simplicity of the plots.
Choose the model and explanation together
Data type alone does not choose the model. Categorical data can be encoded for linear models; nonlinear relationships can be modeled with additive components, engineered features or trees. Evaluate the actual problem and available data rather than applying a family-level shortcut.
There is also no universal interpretability ranking in which trees always beat linear models and GAMs. Five meaningful coefficients may be easier to understand than a large tree; a small set of curves may better express the task than either. Domain knowledge, predictive performance, stability, regulatory needs and maintenance all belong in the choice.
A worked illustration keeps three explanation questions separate
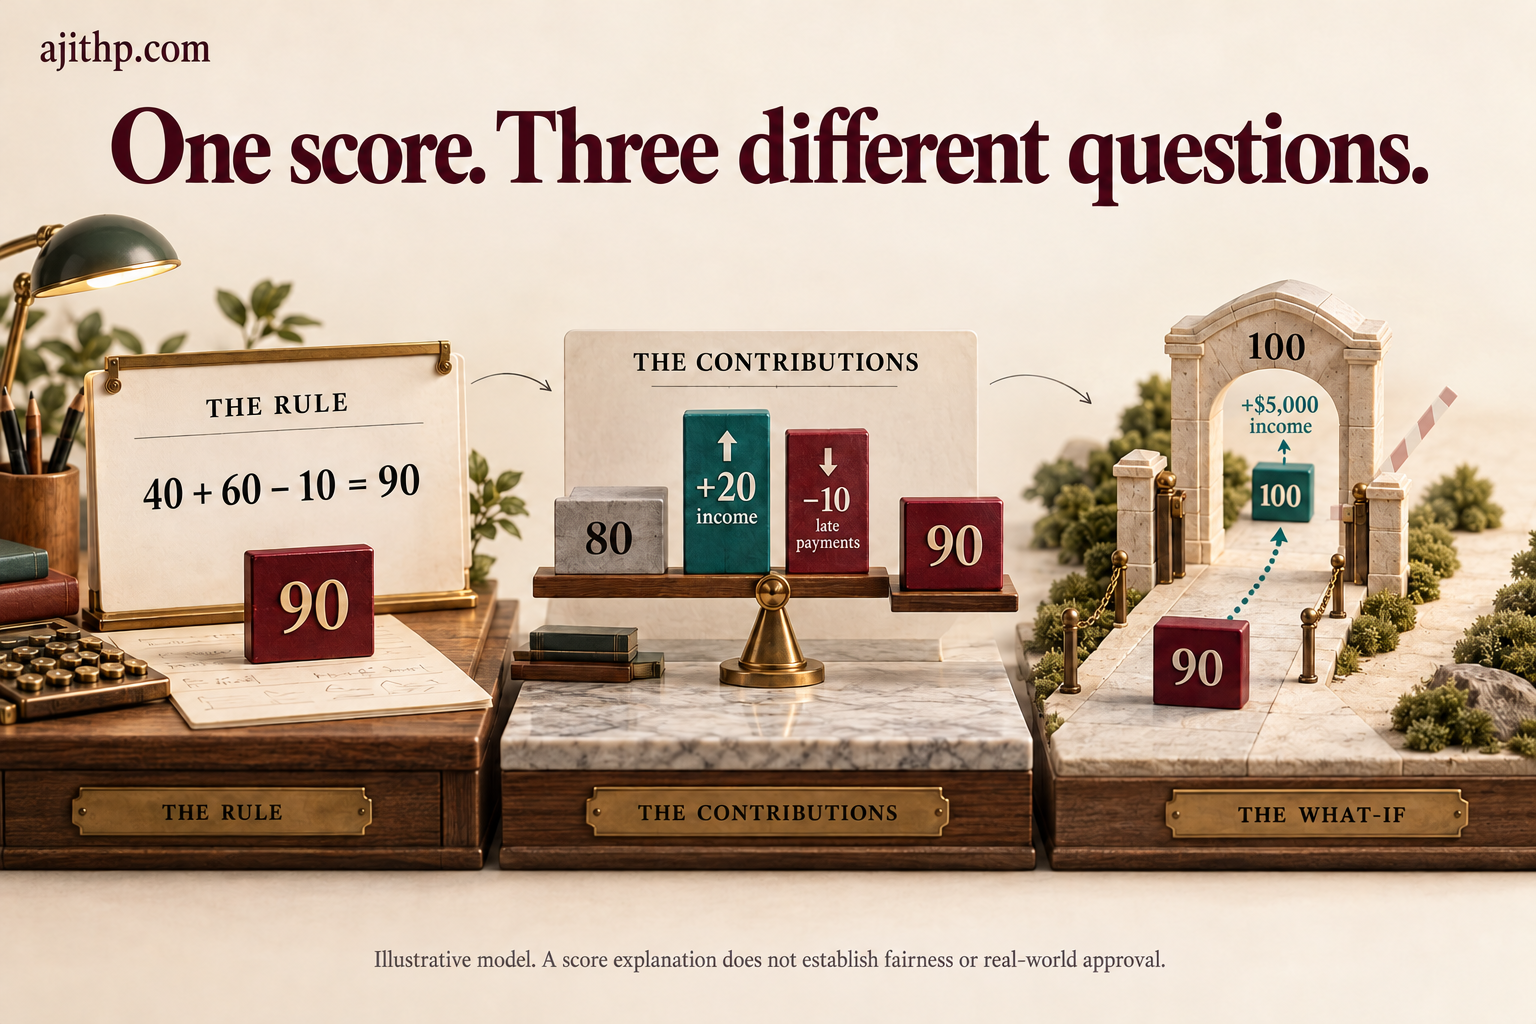
Consider a deliberately invented additive screening score for a training exercise. It is not a lending model or a recommendation for credit policy. The score is 40, plus 0.002 times annual income in dollars, minus 10 times the number of late payments. A score of at least 100 passes this toy threshold.
For income of $30,000 and one late payment, the calculation is 40 + 60 − 10 = 90. Increasing income by $5,000 while holding everything else fixed adds 10 and reaches 100. This is the model-level counterfactual used in the earlier example, with the assumptions made visible.
Setting the late-payment count from one to zero also reaches 100. The arithmetic permits both changes; the person’s options may not. A past late payment cannot simply be undone, while correcting one that was wrongly recorded is a different action. A useful counterfactual has to distinguish between those possibilities.
Now choose a reference record with $20,000 income and no late payments. Its score is 80. Relative to that reference, the example record has a +20 income contribution and a −10 late-payment contribution, which add to the score difference of +10. This is an exact additive decomposition of the toy function, not a claim that a SHAP implementation was run or that every SHAP background produces these values.
The three questions differ. The formula explains the rule; the reference comparison allocates a score difference; the counterfactual finds a change that crosses the toy threshold. None establishes whether using late payments is fair, whether the applicant can increase income, or whether the record is accurate. Those require evidence outside this arithmetic.

Applications need domain evidence as well as a method
Healthcare
For a diagnosis or risk score, connect the explanation with intended use, data quality, clinical performance and the clinician’s actual task. A saliency map may highlight an image artifact; a symptom attribution may expose an input error. Either is a reason to investigate before relying on the output.
Consider an illustrative retinal-screening workflow. The clinician receives an image, a risk output and a highlighted region. Review must establish whether the image is adequate, whether the finding is supported and whether the proposed next step fits the patient. The useful explanation is the one that helps that review, including exposing a reason to reject the model’s output; its presence alone says nothing about improved clinical outcomes.
De Fauw and colleagues' 2018 retinal study, involving DeepMind and Moorfields, used a two-stage architecture: OCT scans were mapped to tissue-segmentation hypotheses, then a classifier used those maps to infer diagnosis and referral probabilities. That intermediate representation provides something concrete to inspect. The architecture and referral evaluation do not establish that showing an explanation improves a clinician’s decisions; that is a further question to test.
Finance
A credit model, a fraud detector and a pricing system present different explanation duties and risks. For a credit decision, distinguish the model’s feature contribution from the actual reasons and policy conditions governing the decision. A customer needs an intelligible account and a usable correction or challenge process; internal analysts may need detailed attribution and subgroup analysis.
An explanation does not make an unfair rule acceptable. It can expose a dependency worth testing, but fairness claims need evidence about the chosen outcomes, populations and applicable rules. Fraud-control explanations also need access controls so legitimate review does not unnecessarily disclose exploitable operational details.
Autonomous systems
An account of sudden braking may require reconstructing perception, localization, planning and control, including the environment and sensor condition. A sentence generated after the event can be plausible while failing to identify the actual mechanism.
Use explanations as part of trace-based diagnosis and engineering validation. Preserve the software version and timing of the relevant signals. The engineer’s ability to reconstruct a failure and the passenger’s ability to understand an event are separate usability goals; neither replaces testing the safety of the control system.
Ethical dilemmas remain after an explanation is added
Privacy
An explanation can disclose sensitive input data to someone who should not receive it. A medical explanation that repeats a patient’s history is an access-control problem even if it says nothing about the training set. Extraction of private training information is a different threat requiring its own evidence and defenses.
Limit explanation access and retention according to the audience and purpose. Redaction and aggregation can reduce exposure but also remove information necessary for challenge or audit. Evaluate that trade-off instead of calling an explanation privacy-preserving merely because its interface is simple.
Gaming and legitimate recourse
Someone may falsify an input to manipulate a decision. Another person may legitimately correct a record or take an available action to qualify. These should not be treated as the same behavior.
Monitor for fraud and validate relevant inputs without withholding every useful explanation. A counterfactual that encourages an impossible or harmful action fails its purpose. Updating the model can change the boundary, so retain the model version and conditions attached to advice already given.
Oversimplification and misplaced reliance
A concise explanation necessarily selects information. Selection becomes dangerous when it hides a material limitation or presents a local approximation as the complete model. In an illustrative trading system, a small set of feature bars cannot account for market change, execution conditions and portfolio risk.
Offer layers appropriate to the audience, but make it possible to reach the necessary detail. Test whether users recognize errors and limits, rather than asking only whether they found the explanation clear or reassuring.
Rationalizing bias
A plausible narrative can normalize a biased hiring decision. Feature attribution can be numerically consistent while the underlying label, data collection or policy remains inappropriate. Audit those components and the resulting group outcomes rather than grading the explanation’s tone.
Include reviewers who understand the affected task and populations. Their participation helps identify missing questions, but diversity of review alone is not proof that bias has been eliminated.
Intellectual property and access rights
Detailed interfaces may reveal commercially sensitive behavior. Decide what different users need and protect confidential evidence appropriately. Do not assume that any useful explanation reproduces a proprietary algorithm, or that trade-secret claims automatically override applicable individual rights.
The distinction between a meaningful account and a complete source-code disclosure matters here. A governed evidence process can support review of contested information without promising unrestricted disclosure to every audience.
Sensitive domains and responsibility
In criminal justice, military settings and other consequential applications, an explanation must not become a justification for automating a decision that should not be automated. A predictive-policing explanation can describe a statistical dependency while leaving the legitimacy of the data and intervention unresolved.
Assign an accountable decision owner, define the permitted use and provide a real way to stop or challenge the process. The explanation is evidence for that process; it does not supply moral or legal authority to act.
Performance trade-offs
Some tasks may favor a more complex model; others may achieve the required performance with an interpretable one. Measure the difference and its consequences. Do not sacrifice a clinically important outcome merely to obtain a simpler chart, but do not assume a complex model is necessary because its family is fashionable.
A hybrid approach also has costs: another component to maintain, additional failure modes and possible mismatch between prediction and explanation. It needs validation as a system. Calling it a balance between accuracy and transparency does not establish that the balance has been achieved.
Evaluate the explanation as part of the operating system
Three kinds of checks belong together. First, test fidelity and stability under conditions meaningful for the method. Second, test whether the intended audience understands the account and can identify relevant failures. Third, test the decision process, including access, challenge, escalation and what happens when the evidence is insufficient.
Scalability adds another constraint. A perturbation-based explainer may require many model calls; a gradient method may need internal access; a detailed explanation may take longer to review than the decision permits. Measure computation and human effort at the workload’s actual scale. An attractive demonstration on one instance is not an operating-cost estimate.
Retain the input record, model and explainer versions, reference data, selected output, relevant settings and the explanation shown to the user, subject to appropriate privacy controls. If any of these changes, compare the effect before assuming that an old explanation remains valid. The human-oversight discussion addresses the wider problem of making review consequential; an explanation only helps if the person can use it before the relevant consequence.
For a practical first step, choose one decision and one audience. Establish what that person must understand, provide the necessary evidence, and include cases where the explanation or the underlying decision is wrong. A method earns its place when it helps the person make a better-supported decision and its limitations remain visible when it cannot.
Discover more from Ajith Vallath Prabhakar
Subscribe to get the latest posts sent to your email.
2 Comments